Range breadth
How wide the assortment actually is.
- SKU counts by normalised category
- Counts by price band
- Brand count and concentration
- Own-label share of range
- Period-over-period change

Scalable web, app and AI-powered collection across 40+ countries.
All services →Repricing driven by competitor moves rather than a weekly review.
Explore → Pricing & Promotions
 Brand & Intelligence
 Digital Shelf & Search
 Assortment
 For Retailers
Which solution fits?
Talk to ExpertTalabat, Careem Quik and Noon Minutes across 18 GCC cities.
Launch Demo →Tesco, Sainsbury's, Asda, Morrisons and Aldi, daily.
Get Early Access → E-Commerce Dashboard
 Flipkart Insights (Live) #1
 Grocery Intelligence
.svg) Grocery Price (U.S.)
.svg) Quick Commerce (India) HOT
 Food & Restaurant
 Fashion Intelligence
 Automotive
 Travel & Hospitality
 Real Estate
 Food Delivery Intelligence NEW
 OTT & Streaming NEW
 By Use Case
 Pricing Intelligence
 Digital Shelf Analytics
 MAP Monitoring HOT
 Cross-Border Price Parity NEW
 Share of Search
 Review Sentiment
 Kitchen Market Gaps NEW
 Dynamic Pricing / AI Repricing NEW
 Promotions & Deals Alerts NEW
 B2B / POI & Lead Data NEW
 By Region
 Flipkart Real-Time Insights
 Quick Commerce — Zepto · Blinkit
 Pincode Price Tracker
 GCC Q-Commerce — Talabat · Noon NEW
 UK Grocery — Tesco, Sainsbury's, Asda
 AU Grocery — Coles & Woolworths NEW
Sources we already run pipelines against. Download a real sample from any of them.
Browse coverage → Marketplace Scrapers
 Developer APIs
 Universal APIs
 Delivery & SDKs
Fixed monthly retainer, named engineer, no per-request metering.
Managed Data API → Knowledge Center
 Guides & Playbooks
 Downloads & Tools
 Trust & Company
Scalable web, app and AI-powered collection across 40+ countries.
All 58 services →Repricing driven by competitor moves rather than a weekly review.
Explore → Pricing & Promotions
Brand & Intelligence
Digital Shelf & Search
Assortment For RetailersWhich solution fits?
Talk to ExpertSources we already run pipelines against. Download a real sample from any of them.
Browse coverage →Talabat, Careem Quik and Noon Minutes across 18 GCC cities.
Launch Demo →Tesco, Sainsbury's, Asda, Morrisons and Aldi, daily.
Get Early Access → E-Commerce Dashboard
Flipkart Insights (Live) #1
Grocery Intelligence
Grocery Price (U.S.)
Quick Commerce (India) HOT
Food & Restaurant
Fashion Intelligence
Automotive
Travel & Hospitality
Real Estate
Food Delivery Intelligence NEW
OTT & Streaming NEW
By Use Case
Pricing Intelligence
Digital Shelf Analytics
MAP Monitoring HOT
Cross-Border Price Parity NEW
Share of Search
Review Sentiment
Kitchen Market Gaps NEW
Dynamic Pricing / AI Repricing NEW
Promotions & Deals Alerts NEW
B2B / POI & Lead Data NEW
By Region Flipkart Real-Time Insights
Quick Commerce — Zepto · Blinkit
Pincode Price Tracker
GCC Q-Commerce — Talabat · Noon NEW
UK Grocery — Tesco, Sainsbury's, Asda
AU Grocery — Coles & Woolworths NEW
Marketplace Scrapers
Developer APIs Universal APIs Delivery & SDKsFixed monthly retainer, named engineer, no per-request metering.
Managed Data API → Knowledge Center
Guides & Playbooks
Downloads & Tools
Trust & CompanyRange breadth, newness and what quietly disappeared.
Pricing tells you how a retailer competes. Assortment tells you what they have decided to compete on. The second changes less often and matters more, and almost nobody tracks it systematically.
Free pilot on your own sources, returned in 48 hours. No card, no trial clock — and you keep the sample data either way.
Last verified 5 August 2026 by the Actowiz Solutions Data Engineering team.
Catalog and assortment data describes range rather than price: how many SKUs a retailer carries in a category, at what price bands, from which brands, how much of it is own-label, what is newly introduced, what has been dropped, and how much overlaps with competitors.
Every one of those questions requires that categories mean the same thing across retailers, which they do not. Taxonomy mapping is therefore the prerequisite rather than a refinement.
We map published categories to a normalised structure with a confidence score, retain the published path alongside, and deduplicate multi-placed SKUs so counts are counts rather than placements.
A SKU disappearing from range is a commercial decision, and commercially it is often more informative than any price change. But disappearance is ambiguous: it can mean delisted, out of stock and hidden, seasonally withdrawn, or recategorised.
We require continued absence across multiple runs plus disappearance from category listings before classifying a delisting, and we flag the ambiguous cases rather than resolving them. A stock-out recorded as a delist corrupts range analysis; a delist recorded as a stock-out sends supply chain after a decision that has already been made.
Sales, margin, or why a decision was made. Assortment data tells you what was decided, not the reasoning or the result.
Range breadth and delisting are the core. Overlap analysis is what strategy teams build on.
How wide the assortment actually is.
What is being added, and how fast.
What quietly disappeared.
How differentiated retailers really are.
The taxonomy itself as data.
Where you are absent and competitors are not.
A managed engagement, not a tool licence. We own the pipeline and everything that breaks in it.
Every engagement delivers a documented schema. These are the core fields; the full dictionary runs to 100+ and is agreed during scoping.
| Field | Type | What it captures | Refresh |
|---|---|---|---|
retailer / period |
string | Retailer and the period the snapshot covers, so change is measurable | Per period |
category_published / category_norm / map_confidence |
string / decimal | Published path, normalised category and mapping confidence | Per period |
sku_count / sku_count_prev |
int | SKU count this period and last, deduplicated for multi-placement | Per period |
new_skus_30d / delisted_skus_30d |
int | Introductions and delistings over a trailing window | Per period |
newness_share_pct |
decimal | Proportion of range introduced recently, as a range-refresh signal | Per period |
own_label_share_pct |
decimal | Own-label proportion of the category range | Per period |
price_bands |
object | SKU counts by configurable price band, showing where range is concentrated | Per period |
brand_count / top_brand_share_pct |
int / decimal | Brand breadth and concentration within the category | Per period |
shared_skus / exclusive_to_a / overlap_pct |
int / decimal | Assortment overlap fields for retailer pair comparison | Per period |
delist_event / delist_confidence |
object / decimal | Delisting events with dates and confidence in the classification | Daily tier |
gap_categories |
array | Categories where competitors range and you do not | Per period |
SKU counts are deduplicated for multi-placement. A retailer listing the same product in four categories has one SKU, not four, and counting placements instead of products inflates range breadth by a variable and misleading amount.
Assortment work needs full category crawls rather than SKU lists, which makes category selection the main scoping decision.
Assortment analysis requires crawling entire categories rather than tracking a known SKU list, which is a different collection shape and cost profile from price monitoring. We scope categories deliberately for that reason. Request a source we don't list →
We deliver into 40+ countries. These are the markets where this particular service is requested most, and the reason demand concentrates there.
| Market | Why demand concentrates here |
|---|---|
| United Kingdom & Germany | Deep online assortments with clear category structures, which makes taxonomy mapping and overlap measurement most reliable. |
| United States | Enormous marketplace catalogues where range breadth and own-label expansion are the defining competitive dynamics. |
| India & Southeast Asia | Rapid assortment expansion and high listing churn, making newness and delisting detection unusually valuable. |
| France, Spain & Italy | Strong specialist retail with distinct range strategies, widely used for competitive differentiation analysis. |
We run production collection across 40+ countries. Coverage depth varies by market and by source, so we confirm what is actually available for your specific markets during scoping rather than claiming uniform global coverage. Ask about a market we don't list →
Buying and merchandising dominate, with brand distribution and strategy teams close behind.
Range decisions need to know what competitors carry, at what price bands, and what they have recently added or dropped.
Category range breadth by price band and brand with newness and delisting events, tracked period over period.
Range productivity
You cannot see which retailers range your products, which ranged them and stopped, or where competitors have listings you do not.
Listing presence across retailers with delisting detection, plus competitor range coverage in the same categories.
Distribution coverage %
Assortment overlap with competitors is unknown, so differentiation is asserted rather than measured.
Shared and exclusive SKU counts by category against named competitors, with overlap trend over time.
Category differentiation
Competitor range strategy shifts are visible in assortment months before they show in market share.
Category breadth, price band mix, own-label share and brand concentration tracked over time by retailer.
Strategic lead time
Own-label range decisions need to know competitor own-label breadth and where branded lines dominate.
Own-label share by category across retailers with new own-label introduction detection.
Own label penetration
Range breadth and newness cadence are observable operational signals ahead of reported performance.
Longitudinal range breadth, newness and own-label share panels by retailer and category.
Signal lead time
Four patterns, with the outcome each is judged on.
Full category crawls across your competitive set are normalised to a shared taxonomy, producing categories, price bands and brands where competitors range and you do not.
Outcome: Range expansion decisions driven by measured gaps rather than by supplier proposals.
SKU disappearance is tracked with continued-absence confirmation, so retailers that have dropped your lines are identified as events rather than discovered during a quarterly review.
Outcome: Delistings caught within a collection cycle instead of at the next range review.
Shared and exclusive SKU counts are computed between retailer pairs by category, showing how differentiated a range actually is and how that is changing.
Outcome: Differentiation claims replaced with measured overlap percentages.
New SKU introductions are detected with dates, producing newness share and introduction cadence by category and retailer over time.
Outcome: Range refresh planned against observed competitor cadence rather than an internal calendar.
Clients rarely permit naming. These are real engagement shapes with identifying detail removed, so you can judge whether the work resembles your situation.
The distribution team learned about dropped lines from sales reports or account conversations, typically a full quarter after the decision.
Full category enumeration with delisting detection requiring continued absence confirmation, distinguished from stock-outs and flagged where ambiguous.
Delistings surfaced within a collection cycle, with dates, ahead of the account conversation.
Weekly SKU counts showed a competitor apparently adding hundreds of lines in one category, prompting a range response.
Taxonomy restructure detection with published category paths retained alongside normalised categories.
The apparent expansion proved to be one category split into three, and the planned response was cancelled.
Examples are anonymised at client request. Named references are available on request under NDA. See published case studies →
Before you commit to anything, we run this service against your own sources and send you the output. If the coverage isn't there, the sample will show you that too — which is the point. We would rather lose the deal at the pilot than at month three.
Same collection pipeline and same QA underneath. The difference is who holds the schedule and how the data reaches you.
We own the collection, the QA and the delivery. You receive clean data on a schedule and never touch a scraper.
Best fit: Teams who need the data, not the infrastructure.
The same collection pipeline exposed as an authenticated REST endpoint your systems query directly.
Best fit: Product and engineering teams building on live data.
A defined pull for a specific question — market sizing, diligence, a pitch, a one-off audit.
Best fit: Research, strategy and diligence work with a deadline.
Every engagement is quoted individually, because the honest answer depends on your scope: how many sources, how many records, how often, and how the data reaches you. We scope it with you, run a free pilot on your own sources, and then quote a fixed monthly figure — no per-request metering and no overage billing when volumes move. Request a quote and you will have a number after one call.
Full category crawling plus taxonomy mapping is a different and heavier problem than tracking a known SKU list.
| Consideration | In-house scraping team | Generic proxy / DIY tool | Actowiz managed feed |
|---|---|---|---|
| Time to first usable data | 6–12 weeks of engineering before anything is trustworthy | Days, but output needs manual cleanup before use | Free pilot in 48 hours, production in 5–10 business days |
| Who fixes it when a source changes | Your engineers, at the cost of their roadmap | You do — tools report failures, they don't resolve them | We do, same business day, inside the retainer |
| Data quality assurance | Whatever your team has time to build | None beyond HTTP success | Schema validation plus sampled human QA on every run |
| Compliance documentation | Rarely produced, then requested urgently by legal | Not provided; terms risk sits with you | Sources, method and lawful basis documented for review |
| Accountability | Distributed across a team with other priorities | A support ticket queue | A named engineer and an account owner |
| True annual cost | Engineer salaries, proxies, hosting, ongoing maintenance | Low licence fee plus significant hidden analyst time | One fixed monthly retainer, quoted after scoping |
Teams that already buy price monitoring often assume assortment is a small extension of it. It is not, and the difference explains why assortment data is comparatively rare.
Assortment engagements are scoped by category rather than by SKU count, and weekly is usually the right cadence rather than daily — range changes on a weekly to monthly rhythm, and daily full-category crawls cost far more for little additional signal.
We do run daily on a narrower basis where newness or delisting alerting matters, monitoring category listings for additions and removals rather than re-enumerating everything. That hybrid is usually the right configuration: weekly full counts, daily change detection.
Normalising categories is what makes cross-retailer assortment comparison possible. Keeping the original is what makes it auditable, and both matter.
Published category paths are mapped to a normalised taxonomy using path structure, product attribute profiles and the products themselves — because a category is defined by its contents more reliably than by its name. Each mapping carries a confidence score.
That last point causes more false alarms than any other issue in assortment data. A retailer splitting one category into three produces an apparent range expansion that never happened. We detect taxonomy restructures explicitly and flag them, so period-over-period comparisons are not silently broken by someone else's site redesign.
For SKU-level pricing on the products discovered, this joins directly to pricing and product data on the same product keys.
Categories and competitor set are scoped first, since assortment work is priced by category crawl scope rather than SKU count.
You send us target sites, regions, SKUs or keywords. We return a field-level schema proposal, coverage estimate and refresh recommendation — usually within two working days.
We extract a real sample from your actual targets so you can inspect field fill rates, edge cases and match quality before any commitment.
Our engineers build extractors, then wire validation rules: type checks, range checks, duplicate detection and golden-record comparison against a manually verified subset.
Feeds run at your chosen cadence and land in the warehouse or bucket you already use. Schema changes are versioned and announced before they ship.
We watch coverage drift, fill rates and source changes daily. A named engineer owns your account, and layout breaks are fixed by us — not queued for you.
JSON, JSONL, CSV, Parquet or XLSX, delivered to Amazon S3, Google Cloud Storage, Azure Blob, SFTP, Snowflake, BigQuery, Databricks or a REST/GraphQL endpoint. Webhooks fire on completion, and every batch ships with a manifest containing row counts, schema version and QA results so your pipeline can fail loudly instead of silently ingesting a bad file.
We collect publicly accessible category, search and product pages. Category enumeration respects pagination and rate limits, and collection rates are set to be low-impact. We do not access retailer systems, supplier portals or any authenticated catalogue.
These are contractual, not marketing copy. They appear in the engagement document.
| Commitment | What we hold ourselves to |
|---|---|
| Pilot turnaround | A real sample from your own sources within 48 hours of scoping, at no cost. |
| Go-live | Production collection running within 5–10 business days of sign-off. |
| Delivery punctuality | 99.5% on-schedule delivery, measured monthly and reported to you. |
| Breakage response | Source layout changes triaged same business day; critical sources inside 4 hours. |
| Data quality | Schema validation on every run plus sampled human QA before any delivery leaves us. |
| Escalation | A named engineer and an account owner, not a shared ticket queue. |
| Change requests | Field additions and source changes handled inside the retainer, not re-quoted. |
| Exit | Your historical data exported in full on request. No lock-in, no export fee. |
Plain definitions of the terms used on this page, so procurement and legal reviewers are working from the same vocabulary as your data team.
What buying, distribution and strategy teams ask during evaluation.
Price monitoring tracks a list you supply. Assortment requires discovery — you cannot count what a retailer ranges by checking products you already know about, so entire categories have to be enumerated including products you have never seen.
That makes completeness matter more than freshness. A price feed missing 2% of SKUs is slightly incomplete; an assortment count missing 2% is a wrong number, and the error compounds across period comparisons. It is a heavier collection problem with a different cost profile.
By mapping published category paths to a normalised taxonomy using path structure, product attribute profiles and the actual products in the category — a category is defined by its contents more reliably than by its name. Mapping confidence is delivered per record.
We retain the published path alongside, so counts are auditable, you can remap to your own taxonomy without recollecting, and retailer conversations can use their category language rather than ours.
Usually, and we flag the cases where we cannot. Classification requires continued absence across multiple runs plus disappearance from category listings, not just an unavailable product page.
The distinction matters in both directions: a stock-out recorded as a delist corrupts range analysis, and a delist recorded as a stock-out sends supply chain chasing a decision that has already been made. Ambiguous cases carry a confidence score rather than a determination.
Weekly for full category counts, since range changes on a weekly to monthly rhythm and daily full crawls cost far more for little additional signal. Daily is worth it for change detection — monitoring category listings for additions and removals rather than re-enumerating everything.
That hybrid is the usual configuration: weekly full counts for breadth analysis, daily change detection for newness and delisting alerting.
We detect it and flag it, because it is the largest source of false alarms in assortment data. A retailer splitting one category into three produces an apparent range expansion that never happened.
Because we retain published paths alongside normalised categories, restructures are identifiable as restructures rather than being silently absorbed into period-over-period comparisons. Flagged periods can then be excluded or adjusted rather than misread.
Yes — shared SKU counts, exclusive counts per retailer and overlap percentage by category, tracked over time. It requires product identity matching across retailers, which is delivered with confidence scores.
Overlap is one of the more strategically useful outputs, because differentiation is usually asserted internally rather than measured. Retailers are frequently surprised by how high overlap actually is in categories they consider distinctive.
SKUs, deduplicated for multi-placement. A retailer listing the same product in four categories has one SKU, not four, and counting placements inflates range breadth by a variable and misleading amount.
Variants are handled per your definition — whether a colour or size counts as a separate SKU differs by category and by how you plan internally, so we agree it during scoping rather than imposing one rule across everything.
Yes, using retailer-specific own-label brand mappings rather than name matching, since many retailer brands do not carry the retailer's name and some are exclusive third-party brands.
Own-label share by category, and new own-label introduction detection, are among the most requested fields here — particularly in grocery and general merchandise where own-label expansion is the defining competitive dynamic.
We quote individually, and here the driver is category crawl scope rather than SKU count — because the SKU count is an output, not an input. Retailer count and category breadth determine the work.
A defined category set across a few competitors at weekly cadence sits at the lighter end. Full-catalogue enumeration across many retailers with daily change detection sits considerably higher. One scoping call, a free pilot on your own categories within 48 hours, then a fixed monthly quote. Request a quote.
Send us categories and competitors. We return range breadth, newness, delistings and overlap within 48 hours.
Free pilot, no card, no obligation. We'll show you the taxonomy mapping so you can check it.Our web scraping expertise is relied on by 4,000+ global enterprises including Zomato, Tata Consumer, Subway, and Expedia — helping them turn web data into growth.
Watch how businesses like yours are using Actowiz data to drive growth.
 4.8/5 Average Rating
 50+ Video Testimonials
 92% Client Retention
 50+ Countries Served
From Zomato to Expedia — see why global leaders trust us with their data.
Backed by automation, data volume, and enterprise-grade scale — we help businesses from startups to Fortune 500s extract competitive insights across the USA, UK, UAE, and beyond.


 Product Matching
 Attribute Tagging
 Content Optimization
 Sentiment Analysis
 Prompt-Based Reporting
We partner with agencies, system integrators, and technology platforms to deliver end-to-end solutions across the retail and digital shelf ecosystem.


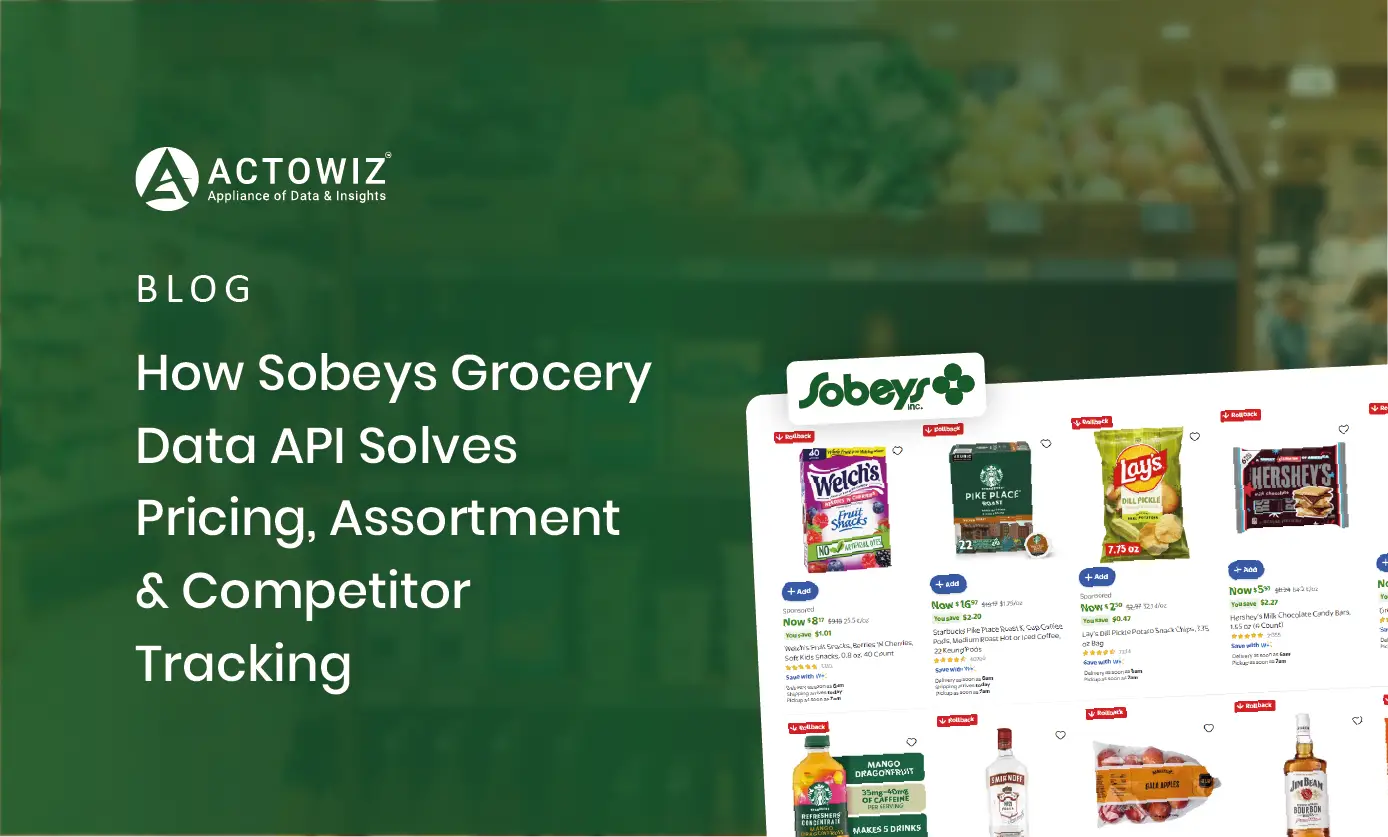
Sobeys Grocery Product Data API helps brands track product prices, availability, assortment, and competitor activity for smarter grocery market decisions.
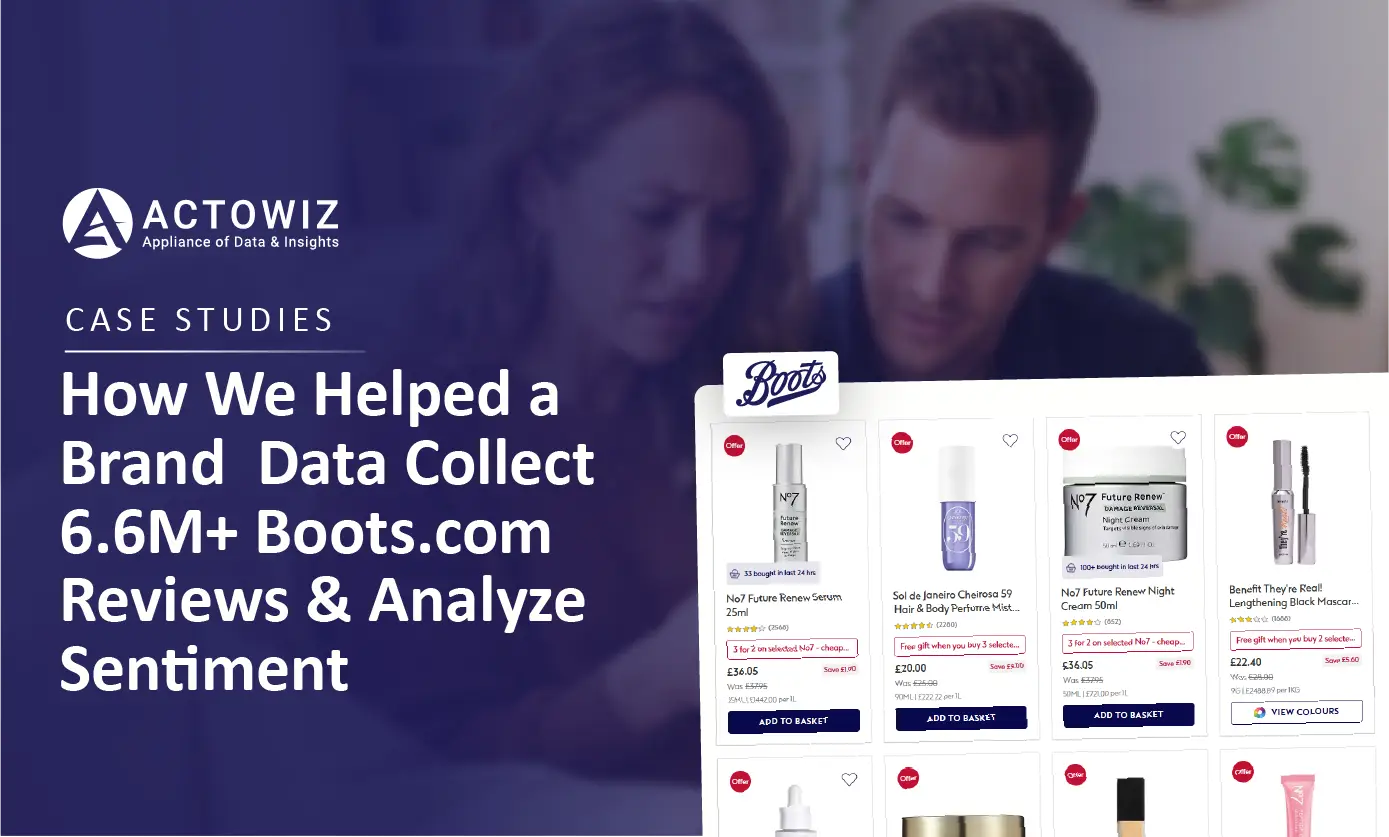
Boots.com Review Data Collection helps brands analyze product reviews, ratings, sentiment, customer feedback, and an additional 6.6M reviews at scale.

Amazon Zipcode-Level Product Data Report 2026 explores Hyperlocal Pricing Intelligence USA for tracking local prices, availability, and product trends.
Whether you're a startup or a Fortune 500 — we have the right plan for your data needs.


 377-7584 (USA).svg)

