Core services
Enterprise Data Extraction

Scalable web, app and AI-powered collection across 40+ countries.

All 58 services →
New 2026
AI Training Data

Corpus building with provenance and opt-out compliance.

Learn more →
Free pilot
24-hour sample

We run collection on your own sources before you commit.

Get a sample →
58Services
40+Countries
DEVELOPER

Ready-Made Scrapers

Pre-built for top platforms. Self-serve, no setup.

View All →
TRY FREE

API Playground

Test endpoints instantly. No credit card.

Start Free →
28Tools
2SDKs
icons Delivery & SDKs
Streaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
Need it managed instead?

Fixed monthly retainer, named engineer, no per-request metering.

Managed Data API →
HOT

Case Studies

How brands use Actowiz, with named outcomes.

Read →
FREE

Sample Datasets

Real output, no signup.

Download →
NEW

ROI Calculator

Model the return on a data engagement.

Calculate →
Food delivery commission and menu price markup analysis for restaurants

Introduction

"We have a product feed" and "our listings are agent-readable" are two different claims. The first describes a file you send somewhere. The second describes what an automated buyer encounters when it lands on your live product page, or reads the structured data behind it, and tries to answer a question: is this the product the shopper asked for, what does it cost right now, can it be bought where they are, and does that link still work.

Most brands can answer the first claim with a yes. Very few have measured the second. This post is about the measurement — how to score your existing live listings, where the failures actually cluster, and which fixes are cheap.

Two Actowiz pages already cover what an agent-facing feed should contain: data for AI agents and agentic commerce real-time product feeds sets out the field-level requirements, and AI shopping agent feeds covers delivery and refresh. This post assumes you have read those and now want to know what you currently have.

Why the feed and the listing diverge

Food delivery commission and menu price markup analysis for restaurants

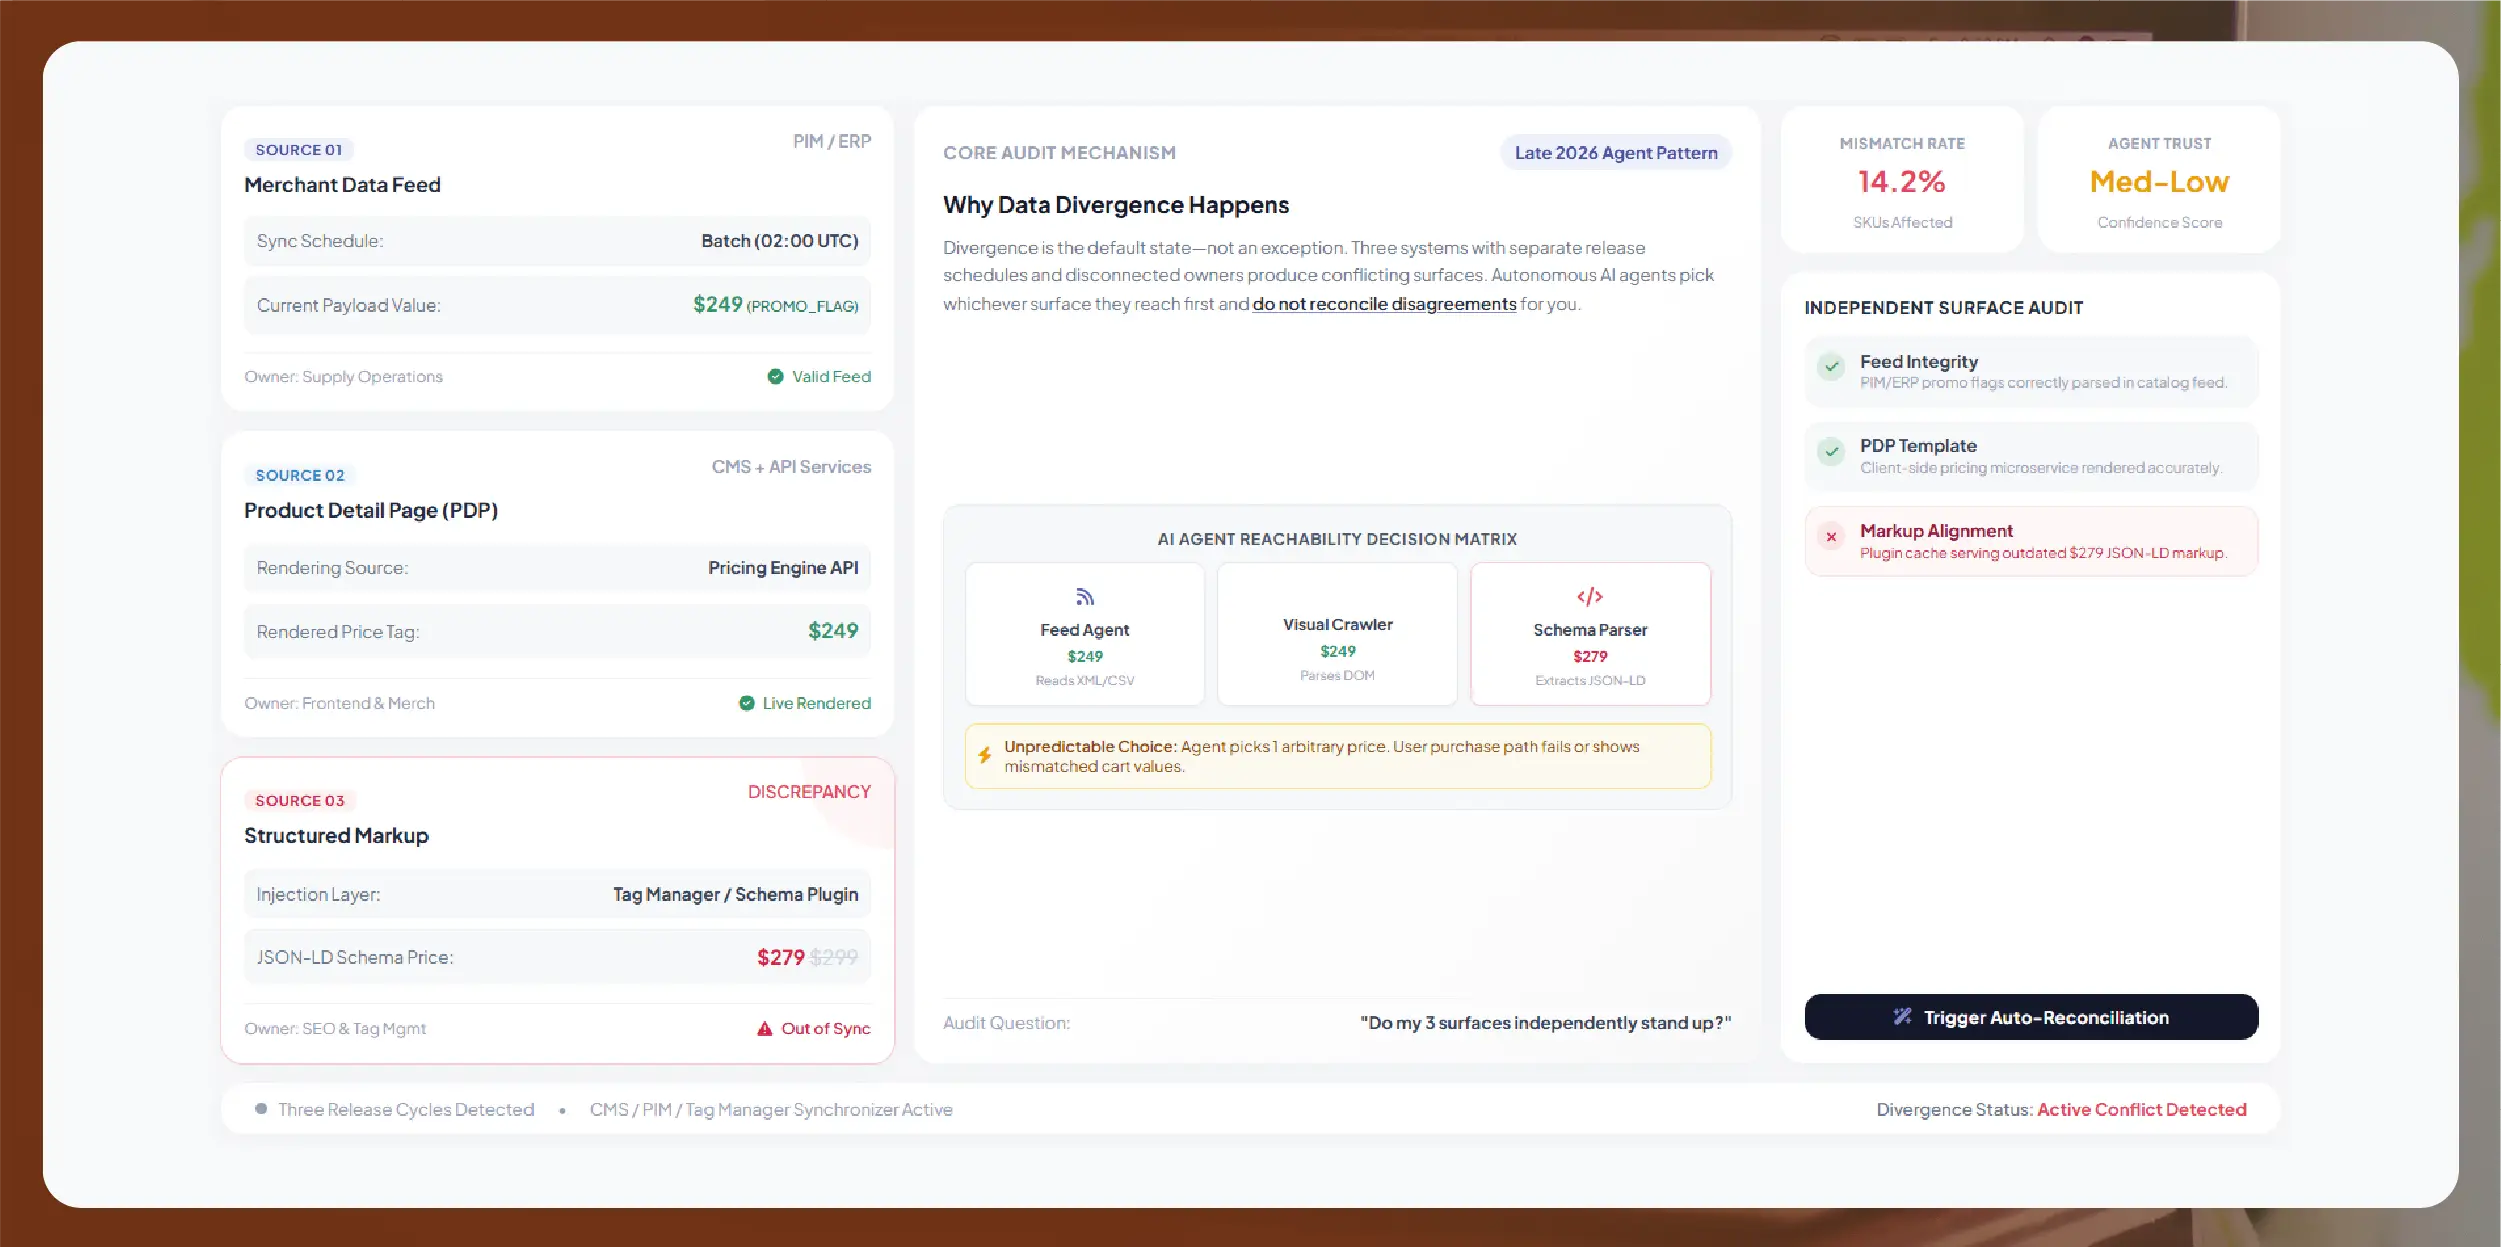
A merchant feed is generated from your PIM or ERP on a schedule. A product detail page is rendered by a template that pulls from a CMS, a pricing service, an inventory service and a handful of merchandising overrides. Structured markup on that page is generated by a third system — often a plugin, sometimes a tag manager injection.

Three systems, three release cycles, three sets of owners. Divergence is the default state, not the exception.

As of late 2026, the pattern across agent implementations is that an agent will use whichever source it can reach and trust, and it will not reconcile disagreements for you. If the page says 249, the markup says 279, and the feed says 249 with a promotion flag, the agent picks one. You do not control which. So the audit question is not "is my data good" but "do my three surfaces agree, and does each one independently stand up".

Designing the sample, not auditing everything

Auditing a full catalogue is a project. Auditing a well-chosen sample is a week. You want the sample to reflect the structural variety in your catalogue, because failures are almost always template-shaped rather than SKU-shaped.

Stratify on the dimensions that map to different code paths:

Stratum Why it splits Suggested minimum
Product template type Simple vs variant vs bundle vs configurable render differently 40 listings per template
Category Attribute schemas differ by category tree branch 25 per top-level category
Price state Promotional, clearance and regular price render through different components 30 per state
Availability state In stock, low stock, backorder, discontinued 20 per state
Age in catalogue Legacy SKUs predate current attribute standards 30 oldest quartile
Locale or market Separate site instances have separate defects Full set per market

Cap the total at something you can genuinely inspect — 300 to 600 listings is usually enough to find every template defect you have. Record the sampling frame, because next quarter's re-audit must be comparable. Once you know the defect classes, you can extrapolate the affected SKU count from your catalogue counts, which is more honest than claiming a catalogue-wide score you did not measure.

The scoring rubric

Score each listing on seven dimensions. Each dimension is pass, partial or fail, with an explicit pass condition. Vague conditions produce vague audits, so write the condition as something a script can check.

Dimension Pass condition Partial Common failure
Stable identity A product ID that persists across re-crawls and is not derived from the URL slug or title ID stable but not exposed in markup ID rotates when the title changes
External identifier resolvability GTIN, EAN, UPC or ASIN present, correct check digit, and resolves to this product Present but unverified Parent GTIN reused across variants
Structured attributes with units Each numeric attribute has value and unit in separate fields, using a controlled unit vocabulary Value and unit in one string "500ml" as free text; "Large" with no dimension
Price with currency and validity Numeric price, ISO currency code, and an explicit validity window or timestamp Price and currency, no validity Currency inferred from locale only
Location-aware availability Availability resolvable for a named delivery location, not a global boolean Global in-stock flag only "In stock" shown before postcode entry
Stable purchase URL Canonical URL, no session or tracking parameters required, resolves without a redirect chain Resolves but through 2+ redirects URL contains a session token
Page and markup agreement Price, availability, title and identifier match between rendered HTML and structured markup Matches on price only Markup generated from a stale cache

Collect the result as a row per listing per dimension, with the observed values, not just the verdict. [DATA: pass rate by dimension across the audited sample] and [DATA: share of audited listings passing all seven dimensions] are the two headline numbers, and the second is always far lower than readers expect.

The three-way consistency check

This is where most real failures live, and it is the part almost no internal audit does. For each sampled listing, capture three things at the same moment:

  • The rendered page as an agent would see it, including JavaScript-rendered content.
  • The structured markup extracted from that same render.
  • The corresponding row from your merchant feed, at the version live at that moment.

Then compare field by field. Same-moment capture matters. If you pull the page today and the feed export from last night, every price change looks like a defect. Timestamp everything and compare within a tight window.

Record disagreements by field and direction:

Field Page vs markup Page vs feed Markup vs feed
Price Pending Pending Pending
Availability Pending Pending Pending
Identifier Pending Pending Pending
Title Pending Pending Pending

Direction matters for diagnosis. Markup lagging the page points at a caching layer. The feed lagging both points at export frequency. The page lagging the feed usually means a CDN holding a stale render.

Weighting, so one bad dimension cannot hide

A simple average across seven dimensions is misleading. A listing that fails external identifier resolvability is not 86% agent-ready; it is largely invisible to any agent that resolves products by identifier. Two mechanics fix this.

First, gate. Define identity, identifier resolvability and purchase URL stability as gating dimensions. A fail on any gate caps the listing score, regardless of the other four. A cap in the 40s communicates the right thing without discarding the detail.

Second, weight the rest by the cost of getting it wrong. Price accuracy failures cause abandoned or disputed transactions. Attribute unit failures cause the product to be excluded from filtered comparisons, which is quieter but affects more queries.

Dimension Weight Gate
Stable identity 15 Yes
External identifier resolvability 20 Yes
Stable purchase URL 10 Yes
Price with currency and validity 20 No
Page and markup agreement 15 No
Structured attributes with units 12 No
Location-aware availability 8 No

Publish the weights with the score. An unexplained composite number invites argument; a weighted score with visible weights invites a conversation about the weights, which is the useful conversation.

Reading the output: cheap fixes versus catalogue work

Sort findings by fix cost, not by score. Two buckets behave very differently.

Template fixes. One change, catalogue-wide effect. Currency code missing from markup, price and unit concatenated into one string, session parameters in the canonical link, markup rendered from a cache with a longer TTL than the price component. These usually resolve in a sprint and move [DATA: composite score] materially.

Catalogue work. Per-SKU data entry or supplier chase. Missing or wrong GTINs, absent dimension attributes, variant-level identifiers that were never captured. This is quarters of work, so it needs prioritisation by revenue or by category competitiveness, not a blanket mandate.

The practical output is a two-column list: template defects with an owning engineering team, and catalogue gaps with an owning merchandising team and a SKU count. A single ranked list of 400 listings helps nobody.

Cadence and benchmarking

Re-audit the same stratified sample quarterly, and run the three-way consistency check monthly on a smaller subset, because that check catches regressions from unrelated releases. Re-audit within two weeks of any platform migration, PIM change or markup plugin update.

Your own score means little in isolation. If your identifier resolvability is [DATA: your pass rate] and the category median is [DATA: category median pass rate], you learn whether you are behind or whether the whole category is. Benchmarking means running the same rubric against a sample of competitor listings in the same categories — which is external collection work, and is exactly what digital shelf analytics coverage is for. Report your score as a position in the category distribution, not as an absolute.

Actowiz Solutions runs this audit as a measured exercise: stratified sampling across your live catalogue, same-moment capture of page, markup and feed, scored against the rubric above, with the same rubric applied to competitor listings for context.

We deliver the per-listing evidence rows alongside the scores, so every finding traces back to a captured observation rather than a judgement.

Request a free sample dataset →

FAQ

Does having a Google Merchant Center feed mean my listings are agent-ready?

No. A merchant feed is one surface. Agents also read the rendered product page and its structured markup, and those are generated by different systems on different release cycles. Agent readiness depends on all three surfaces being independently sound and in agreement with each other.

How many listings do I need to audit to get a useful result?

Enough to cover every structural variant in your catalogue. Stratify by template type, category, price state, availability state and market, then sample within each stratum. Most catalogues reveal all their template-level defects within 300 to 600 carefully chosen listings.

Which agent-readiness failures are quickest to fix?

Template-level ones: a missing currency code in markup, a price and unit concatenated into a single string, session parameters in the canonical URL, or markup served from a longer-lived cache than the price component. Each is one change with catalogue-wide effect. Missing or incorrect external identifiers are the slow category, because they require per-SKU work.

Conclusion

You can also reach us for all your mobile app scraping, data collection, web scraping, and instant data scraper service requirements!

Social Proof That Converts

Trusted by Global Leaders Across Q-Commerce, Travel, Retail, and FoodTech

Our web scraping expertise is relied on by 4,000+ global enterprises including Zomato, Tata Consumer, Subway, and Expedia — helping them turn web data into growth.

4,000+ Enterprises Worldwide
50+ Countries Served
20+ Industries
Join 4,000+ companies growing with Actowiz →
Real Results from Real Clients

Hear It Directly from Our Clients

Watch how businesses like yours are using Actowiz data to drive growth.

▶
1 min
★★★★★
"Actowiz Solutions offered exceptional support with transparency and guidance throughout. Anna and Saga made the process easy for a non-technical user like me. Great service, fair pricing!"
TG
Thomas Galido
Co-Founder / Head of Product at Upright Data Inc.
▶
2 min
★★★★★
"Actowiz delivered impeccable results for our company. Their team ensured data accuracy and on-time delivery. The competitive intelligence completely transformed our pricing strategy."
II
Iulen Ibanez
CEO / Datacy.es
▶
1:30
★★★★★
"What impressed me most was the speed — we went from requirement to production data in under 48 hours. The API integration was seamless and the support team is always responsive."
FC
Febbin Chacko
-Fin, Small Business Owner
icons 4.8/5 Average Rating
icons 50+ Video Testimonials
icons 92% Client Retention
icons 50+ Countries Served

Join 4,000+ Companies Growing with Actowiz

From Zomato to Expedia — see why global leaders trust us with their data.

Why Global Leaders Trust Actowiz

Backed by automation, data volume, and enterprise-grade scale — we help businesses from startups to Fortune 500s extract competitive insights across the USA, UK, UAE, and beyond.

icons
7+
Years of Experience
Proven track record delivering enterprise-grade web scraping and data intelligence solutions.
icons
4,000+
Projects Delivered
Serving startups to Fortune 500 companies across 50+ countries worldwide.
icons
200+
In-House Experts
Dedicated engineers across scrapers, AI/ML models, APIs, and data quality assurance.
icons
9.2M
Automated Workflows
Running weekly across eCommerce, Quick Commerce, Travel, Real Estate, and Food industries.
icons
270+ TB
Data Transferred
Real-time and batch data scraping at massive scale, across industries globally.
icons
380M+
Pages Crawled Weekly
Scaled infrastructure for comprehensive global data coverage with 99% accuracy.

AI Solutions Engineered
for Your Needs

→
LLM-Powered Attribute Extraction: High-precision product matching using large language models for accurate data classification.
→
Advanced Computer Vision: Fine-grained object detection for precise product classification using text and image embeddings.
→
GPT-Based Analytics Layer: Natural language query-based reporting and visualization for business intelligence.
→
Human-in-the-Loop AI: Continuous feedback loop to improve AI model accuracy over time.
icons Product Matching icons Attribute Tagging icons Content Optimization icons Sentiment Analysis icons Prompt-Based Reporting

Connect the Dots Across
Your Retail Ecosystem

We partner with agencies, system integrators, and technology platforms to deliver end-to-end solutions across the retail and digital shelf ecosystem.

icons
Analytics Services
icons
Ad Tech
icons
Price Optimization
icons
Business Consulting
icons
System Integration
icons
Market Research
Become a Partner →

Popular Datasets — Ready to Download

Browse All Datasets →
icons
Amazon
eCommerce
Free 100 rows
icons
Zillow
Real Estate
Free 100 rows
icons
DoorDash
Food Delivery
Free 100 rows
icons
Walmart
Retail
Free 100 rows
icons
Booking.com
Travel
Free 100 rows
icons
Indeed
Jobs
Free 100 rows

Latest Insights & Resources

View All Resources →
thumb
Blog

Web Data RFP Checklist: How to Write an RFP for Web Data Collection (2026)

Use this web data RFP checklist to define scope, sources, fields, SLA, QA and pricing models, then score vendors fairly.

thumb
Case Study

How Sensitive Skin Skincare Product Data API Helps Brands Track Cleansers, Serums, Moisturizers, and Sunscreens

Sensitive Skin Skincare Product Data API helps brands track cleansers, serums, moisturizers, and sunscreens with structured product data.

thumb
Report

Germany Marketplace Market Data Report 2026 for Brand Pricing Intelligence

German marketplace data report 2026: online retail size, Amazon.de, Otto, Kaufland and Zalando price signals, PAngV rules and peak seasons.

Start Where It Makes Sense for You

Whether you're a startup or a Fortune 500 — we have the right plan for your data needs.

icons
Enterprise
Book a Strategy Call
Custom solutions, dedicated support, volume pricing for large-scale needs.
icons
Growing Brand
Get Free Sample Data
Try before you buy — 500 rows of real data, delivered in 2 hours. No strings.
icons
Just Exploring
View Plans & Pricing
Transparent plans from $500/mo. Find the right fit for your budget and scale.
Get in Touch
Let's Talk About
Your Data Needs
Tell us what data you need — we'll scope it for free and share a sample within hours.
  • icons
    Free Sample in 2 HoursShare your requirement, get 500 rows of real data — no commitment.
  • icons
    Plans from $500/monthFlexible pricing for startups, growing brands, and enterprises.
  • icons
    US-Based SupportOffices in New York & California. Aligned with your timezone.
  • icons
    ISO 9001 & 27001 CertifiedEnterprise-grade security and quality standards.
Request Free Sample Data
Fill the form below — our team will reach out within 2 hours.
+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours

Request Free Sample Data

Our team will reach out within 2 hours with 500 rows of real data — no credit card required.

+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours