Core services
Enterprise Data Extraction

Scalable web, app and AI-powered collection across 40+ countries.

All 58 services →
New 2026
AI Training Data

Corpus building with provenance and opt-out compliance.

Learn more →
Free pilot
24-hour sample

We run collection on your own sources before you commit.

Get a sample →
58Services
40+Countries
DEVELOPER

Ready-Made Scrapers

Pre-built for top platforms. Self-serve, no setup.

View All →
TRY FREE

API Playground

Test endpoints instantly. No credit card.

Start Free →
28Tools
2SDKs
icons Delivery & SDKs
Streaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
Need it managed instead?

Fixed monthly retainer, named engineer, no per-request metering.

Managed Data API →
HOT

Case Studies

How brands use Actowiz, with named outcomes.

Read →
FREE

Sample Datasets

Real output, no signup.

Download →
NEW

ROI Calculator

Model the return on a data engagement.

Calculate →
Crex Data Scraping - Solving Accuracy and Data Consistency Issues in Cricket Analytics

Introduction

Automotive is one of the most data-rich retail categories online and one of the least systematically tracked. Vehicle listings, dealer inventory, OEM specification catalogues, tyre and parts pricing across marketplaces, and used-vehicle valuations are all publicly published and structurally extractable. This guide covers what exists across five data layers, what each is used for, and why automotive data collection is harder than general e-commerce.

Why Automotive Data Is Structurally Different

Crex Data Scraping - Solving Accuracy and Data Consistency Issues in Cricket Analytics

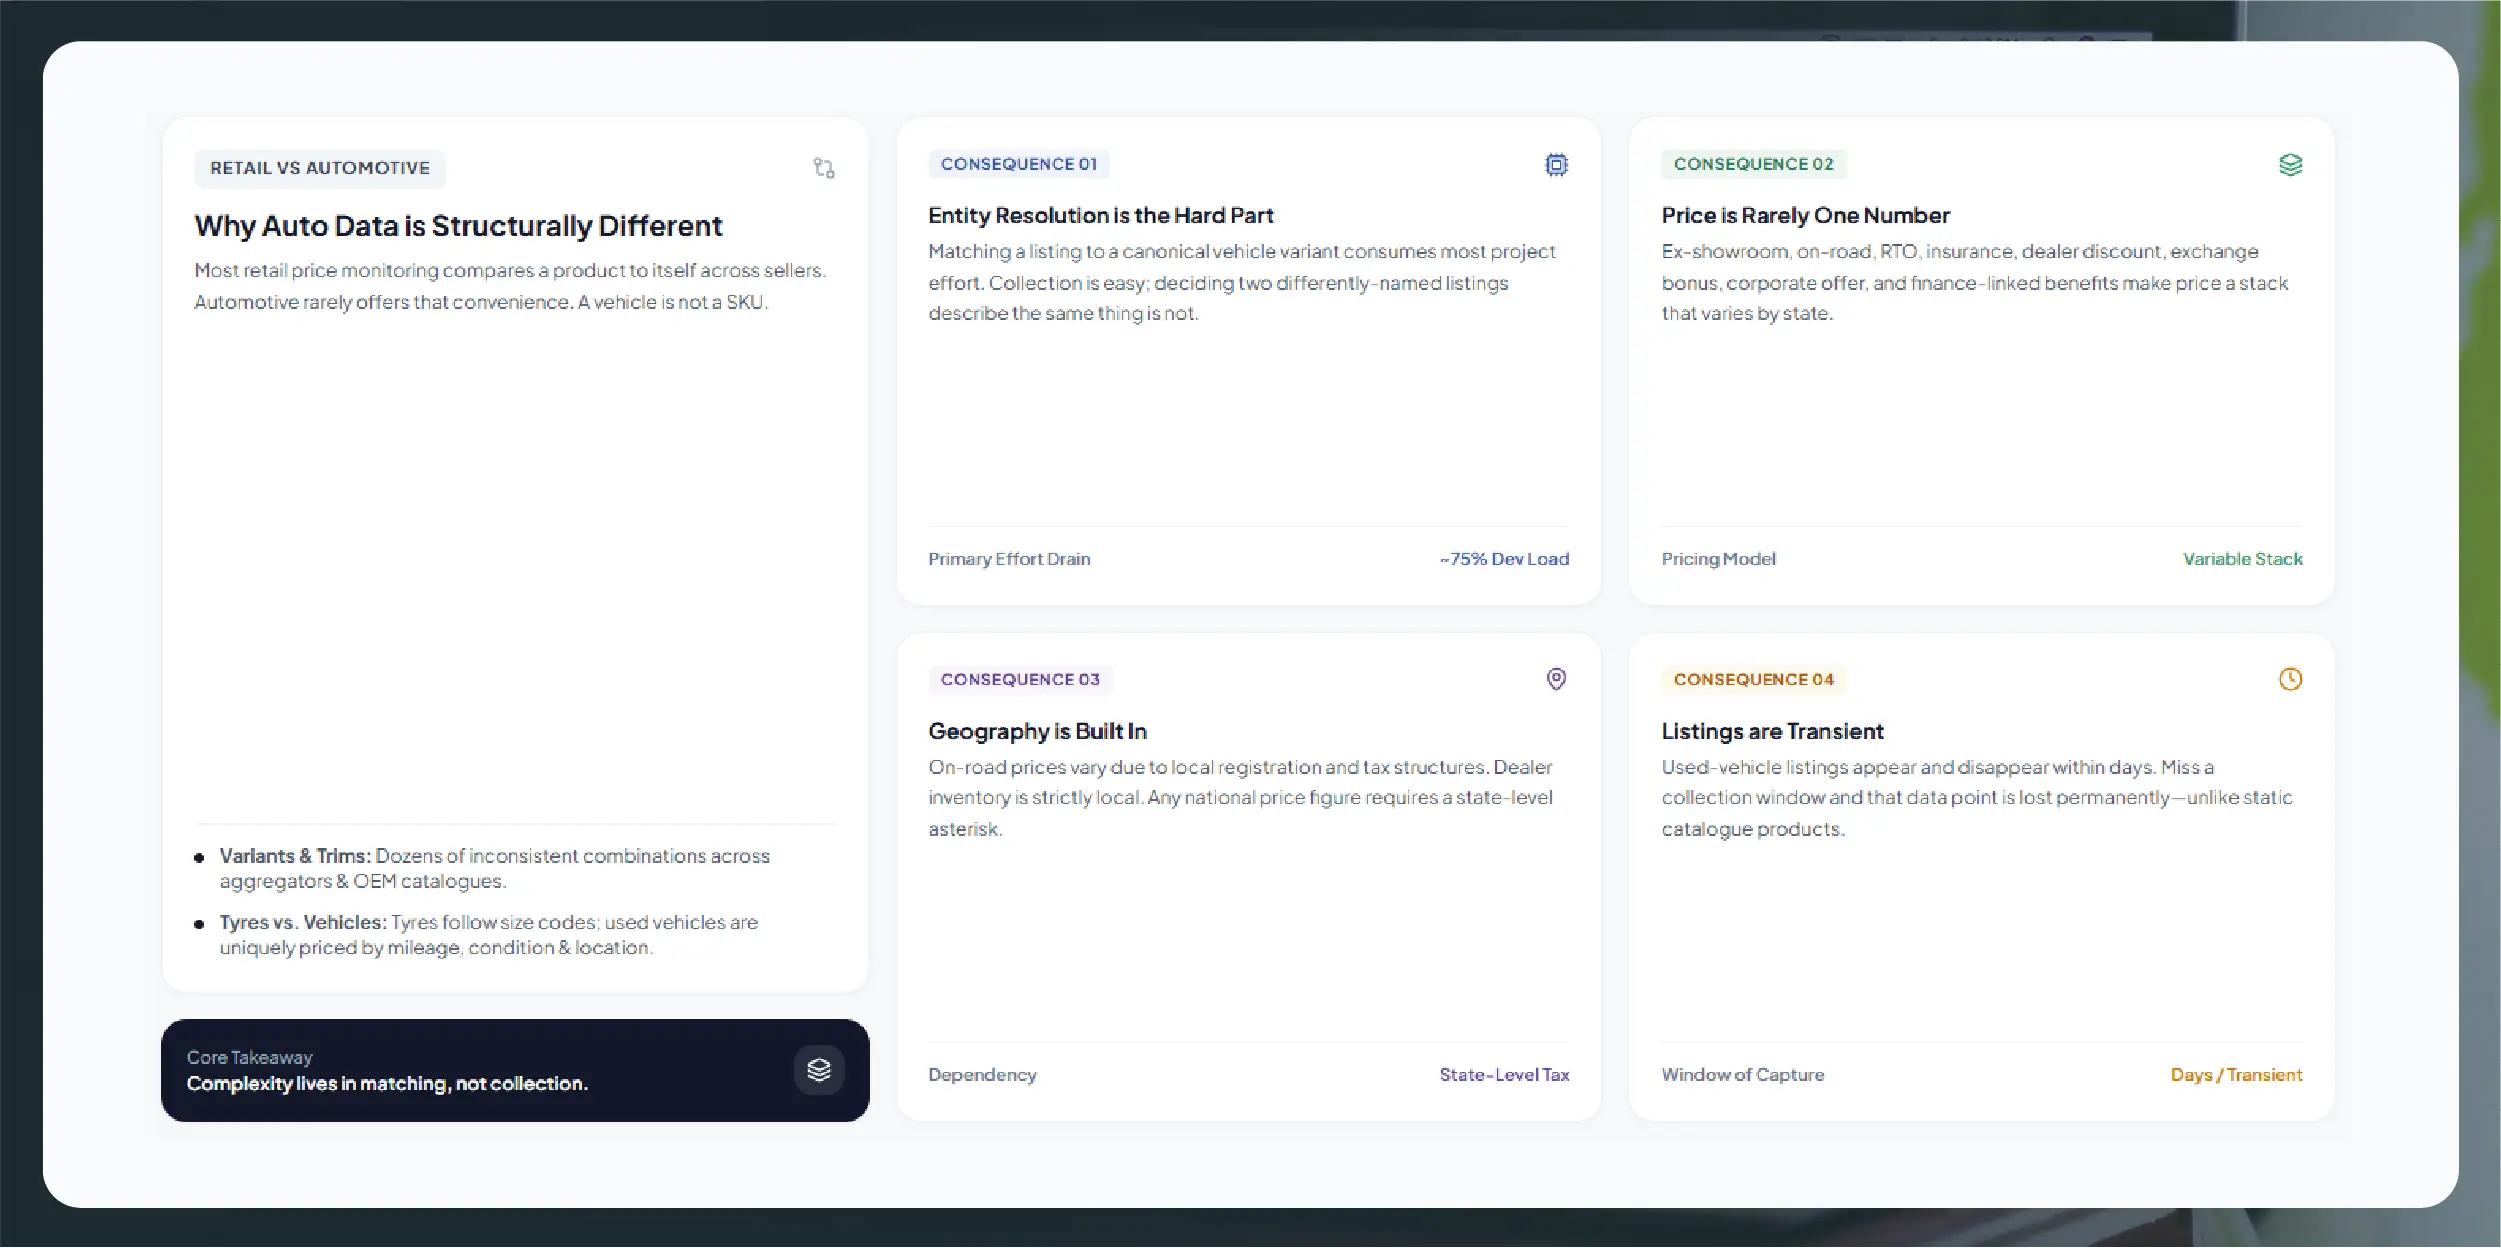
Most retail price monitoring compares a product to itself across sellers. Automotive rarely offers that convenience.

A vehicle is not a SKU. The same model exists as dozens of variant-trim-fuel-transmission combinations, named inconsistently across dealer sites, aggregator portals and OEM catalogues. A tyre is closer to a SKU but is identified by a size code that appears in several formats. A used vehicle is genuinely unique — mileage, condition, ownership history and location all price it independently.

Four consequences follow:

  • Entity resolution is the hard part. Matching a listing to a canonical vehicle variant is where most automotive data projects consume their effort. Collection is comparatively straightforward; deciding that two differently-named listings describe the same thing is not.
  • Price is rarely one number. Ex-showroom, on-road, RTO and insurance components, dealer discount, exchange bonus, corporate offer, finance-linked benefit — an automotive "price" is a stack, and the stack varies by state.
  • Geography is built in. On-road price in India varies by state because of registration and tax structure. Dealer inventory is inherently local. Any national automotive price figure needs a state-level asterisk.
  • Listings are transient. Used-vehicle listings appear and disappear within days. Miss a collection window and that data point is gone permanently — unlike a catalogue product, which is still there tomorrow.

The Five Layers of Automotive Data

Layer 1 — New vehicle catalogue and specifications

What's published: Model and variant listings, engine and transmission specifications, dimensions, feature-by-variant matrices, colour options, mileage claims, ex-showroom price by variant, on-road price by city or state.

Sources: OEM websites, automotive aggregator portals, review and comparison sites.

Used for: Competitive specification benchmarking, feature-gap analysis by price band, variant-strategy and trim-ladder decisions, price-positioning studies.

Difficulty: Moderate. Structured and relatively stable, but variant naming across sources requires a canonical mapping layer that has to be maintained rather than built once.

Layer 2 — Dealer network and inventory

What's published: Dealer locations and contact details, brands represented, service versus sales designation, and where exposed, available inventory by variant and colour.

Sources: OEM dealer locators, dealer group websites, aggregator dealer directories.

Used for: Network coverage and white-space mapping, competitive footprint analysis, territory planning, inventory-availability benchmarking.

Difficulty: Low to moderate for locator data. Inventory-level data is inconsistently exposed and varies substantially by brand and market.

Layer 3 — Used vehicle listings

What's published: Make, model, variant, year of manufacture, kilometres driven, fuel type, transmission, ownership count, asking price, location, seller type, listing photographs, days on market where shown.

Sources: Used-car marketplaces, classified platforms, organized used-car retail platforms, dealer inventory pages.

Used for: Residual-value and depreciation curve modelling, used-market pricing benchmarks, supply-and-demand analysis by model and region, lending and insurance valuation inputs.

Difficulty: High. Listing volumes are large, churn is fast, duplicates across platforms are common, and condition-based price variance means the analysis needs statistical treatment rather than simple comparison.

Layer 4 — Tyres, parts and accessories

What's published: Product listings with size and specification codes, brand, model, price, discount, seller, stock status, ratings and reviews across marketplaces and specialist retailers.

Sources: General marketplaces (Amazon, Flipkart, Lazada and regional equivalents), specialist automotive retailers and apps, OEM parts catalogues where public.

Used for: Aftermarket price monitoring, MRP compliance and MAP-violation detection, unauthorized-seller identification, assortment and availability tracking, competitor promotional monitoring.

Difficulty: Moderate. This layer behaves most like conventional e-commerce monitoring, with the addition of size-code normalization — the same tyre size expressed in several formats has to resolve to one entity.

This is the layer most likely to deliver value fastest, because it is the layer where automotive data most resembles the retail monitoring that is already a solved problem.

Layer 5 — Reviews, sentiment and content signals

What's published: Owner reviews and ratings, expert reviews, complaint-forum discussion, video review engagement metrics.

Sources: Aggregator review sections, marketplace product reviews, owner forums, video platforms.

Used for: Product-issue early detection, brand-perception tracking, feature-priority research, service-quality benchmarking.

Difficulty: Moderate to high. Volume is manageable; extracting a reliable signal from unstructured opinion is the harder half.

What Each Buyer Type Typically Needs

Buyer Primary layers Typical first question
OEM product planning 1, 5 How does our variant ladder compare to competitors' at each price band?
OEM sales & network 2 Where is our dealer coverage weaker than a competitor's?
Dealer group 2, 3 What are comparable vehicles listed at within our catchment?
Tyre / parts brand 4 Who is selling us below MRP, and where?
Used-car platform 3 What is the real market price curve for this model-year-condition combination?
Lender / insurer 3 What residual value should we underwrite for this asset?
Aftermarket marketplace 4, 5 Where are our assortment and price gaps versus competing marketplaces?

The Mistake Most Automotive Data Projects Make

They start with the widest layer.

The instinct is to begin with complete used-listing coverage across every platform, because that is where the volume and the apparent insight sit. It is also the layer with the worst ratio of collection effort to early usable output — entity resolution, duplicate handling and condition-adjusted price modelling all have to work before the first number means anything.

Projects that produce value quickly usually start at Layer 1 or Layer 4, where entity resolution is tractable and the output is directly comparable. They establish the canonical mapping layer on the easier data, then extend it into used listings once the vocabulary is stable.

Put concretely: build your variant dictionary against OEM catalogues, where the naming is authoritative, before you try to match twenty thousand messy classified listings against it.

What a Sensible Starting Scope Looks Like

Automotive data programs work best when the first phase is narrow enough to prove the mapping layer:

  • One layer. Tyres and parts across two marketplaces, or new-vehicle catalogue data for one segment.
  • One market. One country, and where on-road pricing is involved, a defined state list.
  • A bounded entity set. Ten to thirty models, or a defined tyre-size list — not a category sweep.
  • Two to four weeks at target frequency, long enough to observe price movement and listing churn.

The output that matters from a first phase is not the dataset. It is a validated entity-resolution map and a realistic estimate of how much variance exists in your specific segment. Both are prerequisites for scoping anything larger honestly.

Actowiz Solutions has delivered automotive data collection including vehicle listing and image data from Cardekho and Bikedekho, and tyre pricing across Lazada Malaysia, Lazada Thailand and the Tuhu app for the Malaysian market. Automotive engagements are scoped as defined pilots — we prefer to prove the entity-resolution layer on your segment before committing to ongoing coverage.

FAQ

What automotive data can be collected legally?

Publicly published information — vehicle specifications and prices on OEM and aggregator sites, dealer locator details, publicly listed used-vehicle advertisements, marketplace product listings for parts and accessories, and public reviews. Authenticated dealer systems, DMS platforms and restricted portals are out of scope. Confirm your specific use case with legal counsel.

Can you extract on-road prices by state?

Where they are published. On-road price varies by state due to registration and tax structure, so it is collected per state rather than nationally. Some sources publish state or city-level on-road breakdowns; others publish ex-showroom only, with on-road available at dealer level.

How is used-car listing data handled given how fast listings change?

With a fixed collection cadence and append-only storage. A used-vehicle listing that disappears is unrecoverable, so the collection frequency defines the resolution of any subsequent depreciation or days-on-market analysis. Daily collection is common for active markets.

What is the hardest part of automotive data extraction?

Entity resolution — matching inconsistently named listings to a canonical variant. Collection is comparatively routine. Most automotive project effort goes into the mapping layer that decides two differently-worded listings describe the same vehicle.

Can tyre and parts pricing be monitored across marketplaces?

Yes, and this is generally the fastest-to-value automotive layer because it behaves like conventional e-commerce monitoring. The additional requirement is size and specification-code normalization so the same tyre expressed in different formats resolves to one entity.

Do you build automotive dashboards?

Data is delivered in your schema for your BI layer, and dashboard-ready structured feeds are a standard delivery format. Where a hosted view is needed, that is scoped alongside the data engagement.

Conclusion

You can also reach us for all your mobile app scraping, data collection, web scraping , and instant data scraper service requirements!

Social Proof That Converts

Trusted by Global Leaders Across Q-Commerce, Travel, Retail, and FoodTech

Our web scraping expertise is relied on by 4,000+ global enterprises including Zomato, Tata Consumer, Subway, and Expedia — helping them turn web data into growth.

4,000+ Enterprises Worldwide
50+ Countries Served
20+ Industries
Join 4,000+ companies growing with Actowiz →
Real Results from Real Clients

Hear It Directly from Our Clients

Watch how businesses like yours are using Actowiz data to drive growth.

▶
1 min
★★★★★
"Actowiz Solutions offered exceptional support with transparency and guidance throughout. Anna and Saga made the process easy for a non-technical user like me. Great service, fair pricing!"
TG
Thomas Galido
Co-Founder / Head of Product at Upright Data Inc.
▶
2 min
★★★★★
"Actowiz delivered impeccable results for our company. Their team ensured data accuracy and on-time delivery. The competitive intelligence completely transformed our pricing strategy."
II
Iulen Ibanez
CEO / Datacy.es
▶
1:30
★★★★★
"What impressed me most was the speed — we went from requirement to production data in under 48 hours. The API integration was seamless and the support team is always responsive."
FC
Febbin Chacko
-Fin, Small Business Owner
icons 4.8/5 Average Rating
icons 50+ Video Testimonials
icons 92% Client Retention
icons 50+ Countries Served

Join 4,000+ Companies Growing with Actowiz

From Zomato to Expedia — see why global leaders trust us with their data.

Why Global Leaders Trust Actowiz

Backed by automation, data volume, and enterprise-grade scale — we help businesses from startups to Fortune 500s extract competitive insights across the USA, UK, UAE, and beyond.

icons
7+
Years of Experience
Proven track record delivering enterprise-grade web scraping and data intelligence solutions.
icons
4,000+
Projects Delivered
Serving startups to Fortune 500 companies across 50+ countries worldwide.
icons
200+
In-House Experts
Dedicated engineers across scrapers, AI/ML models, APIs, and data quality assurance.
icons
9.2M
Automated Workflows
Running weekly across eCommerce, Quick Commerce, Travel, Real Estate, and Food industries.
icons
270+ TB
Data Transferred
Real-time and batch data scraping at massive scale, across industries globally.
icons
380M+
Pages Crawled Weekly
Scaled infrastructure for comprehensive global data coverage with 99% accuracy.

AI Solutions Engineered
for Your Needs

→
LLM-Powered Attribute Extraction: High-precision product matching using large language models for accurate data classification.
→
Advanced Computer Vision: Fine-grained object detection for precise product classification using text and image embeddings.
→
GPT-Based Analytics Layer: Natural language query-based reporting and visualization for business intelligence.
→
Human-in-the-Loop AI: Continuous feedback loop to improve AI model accuracy over time.
icons Product Matching icons Attribute Tagging icons Content Optimization icons Sentiment Analysis icons Prompt-Based Reporting

Connect the Dots Across
Your Retail Ecosystem

We partner with agencies, system integrators, and technology platforms to deliver end-to-end solutions across the retail and digital shelf ecosystem.

icons
Analytics Services
icons
Ad Tech
icons
Price Optimization
icons
Business Consulting
icons
System Integration
icons
Market Research
Become a Partner →

Popular Datasets — Ready to Download

Browse All Datasets →
icons
Amazon
eCommerce
Free 100 rows
icons
Zillow
Real Estate
Free 100 rows
icons
DoorDash
Food Delivery
Free 100 rows
icons
Walmart
Retail
Free 100 rows
icons
Booking.com
Travel
Free 100 rows
icons
Indeed
Jobs
Free 100 rows

Latest Insights & Resources

View All Resources →
thumb
Blog

Web Data RFP Checklist: How to Write an RFP for Web Data Collection (2026)

Use this web data RFP checklist to define scope, sources, fields, SLA, QA and pricing models, then score vendors fairly.

thumb
Case Study

How Sensitive Skin Skincare Product Data API Helps Brands Track Cleansers, Serums, Moisturizers, and Sunscreens

Sensitive Skin Skincare Product Data API helps brands track cleansers, serums, moisturizers, and sunscreens with structured product data.

thumb
Report

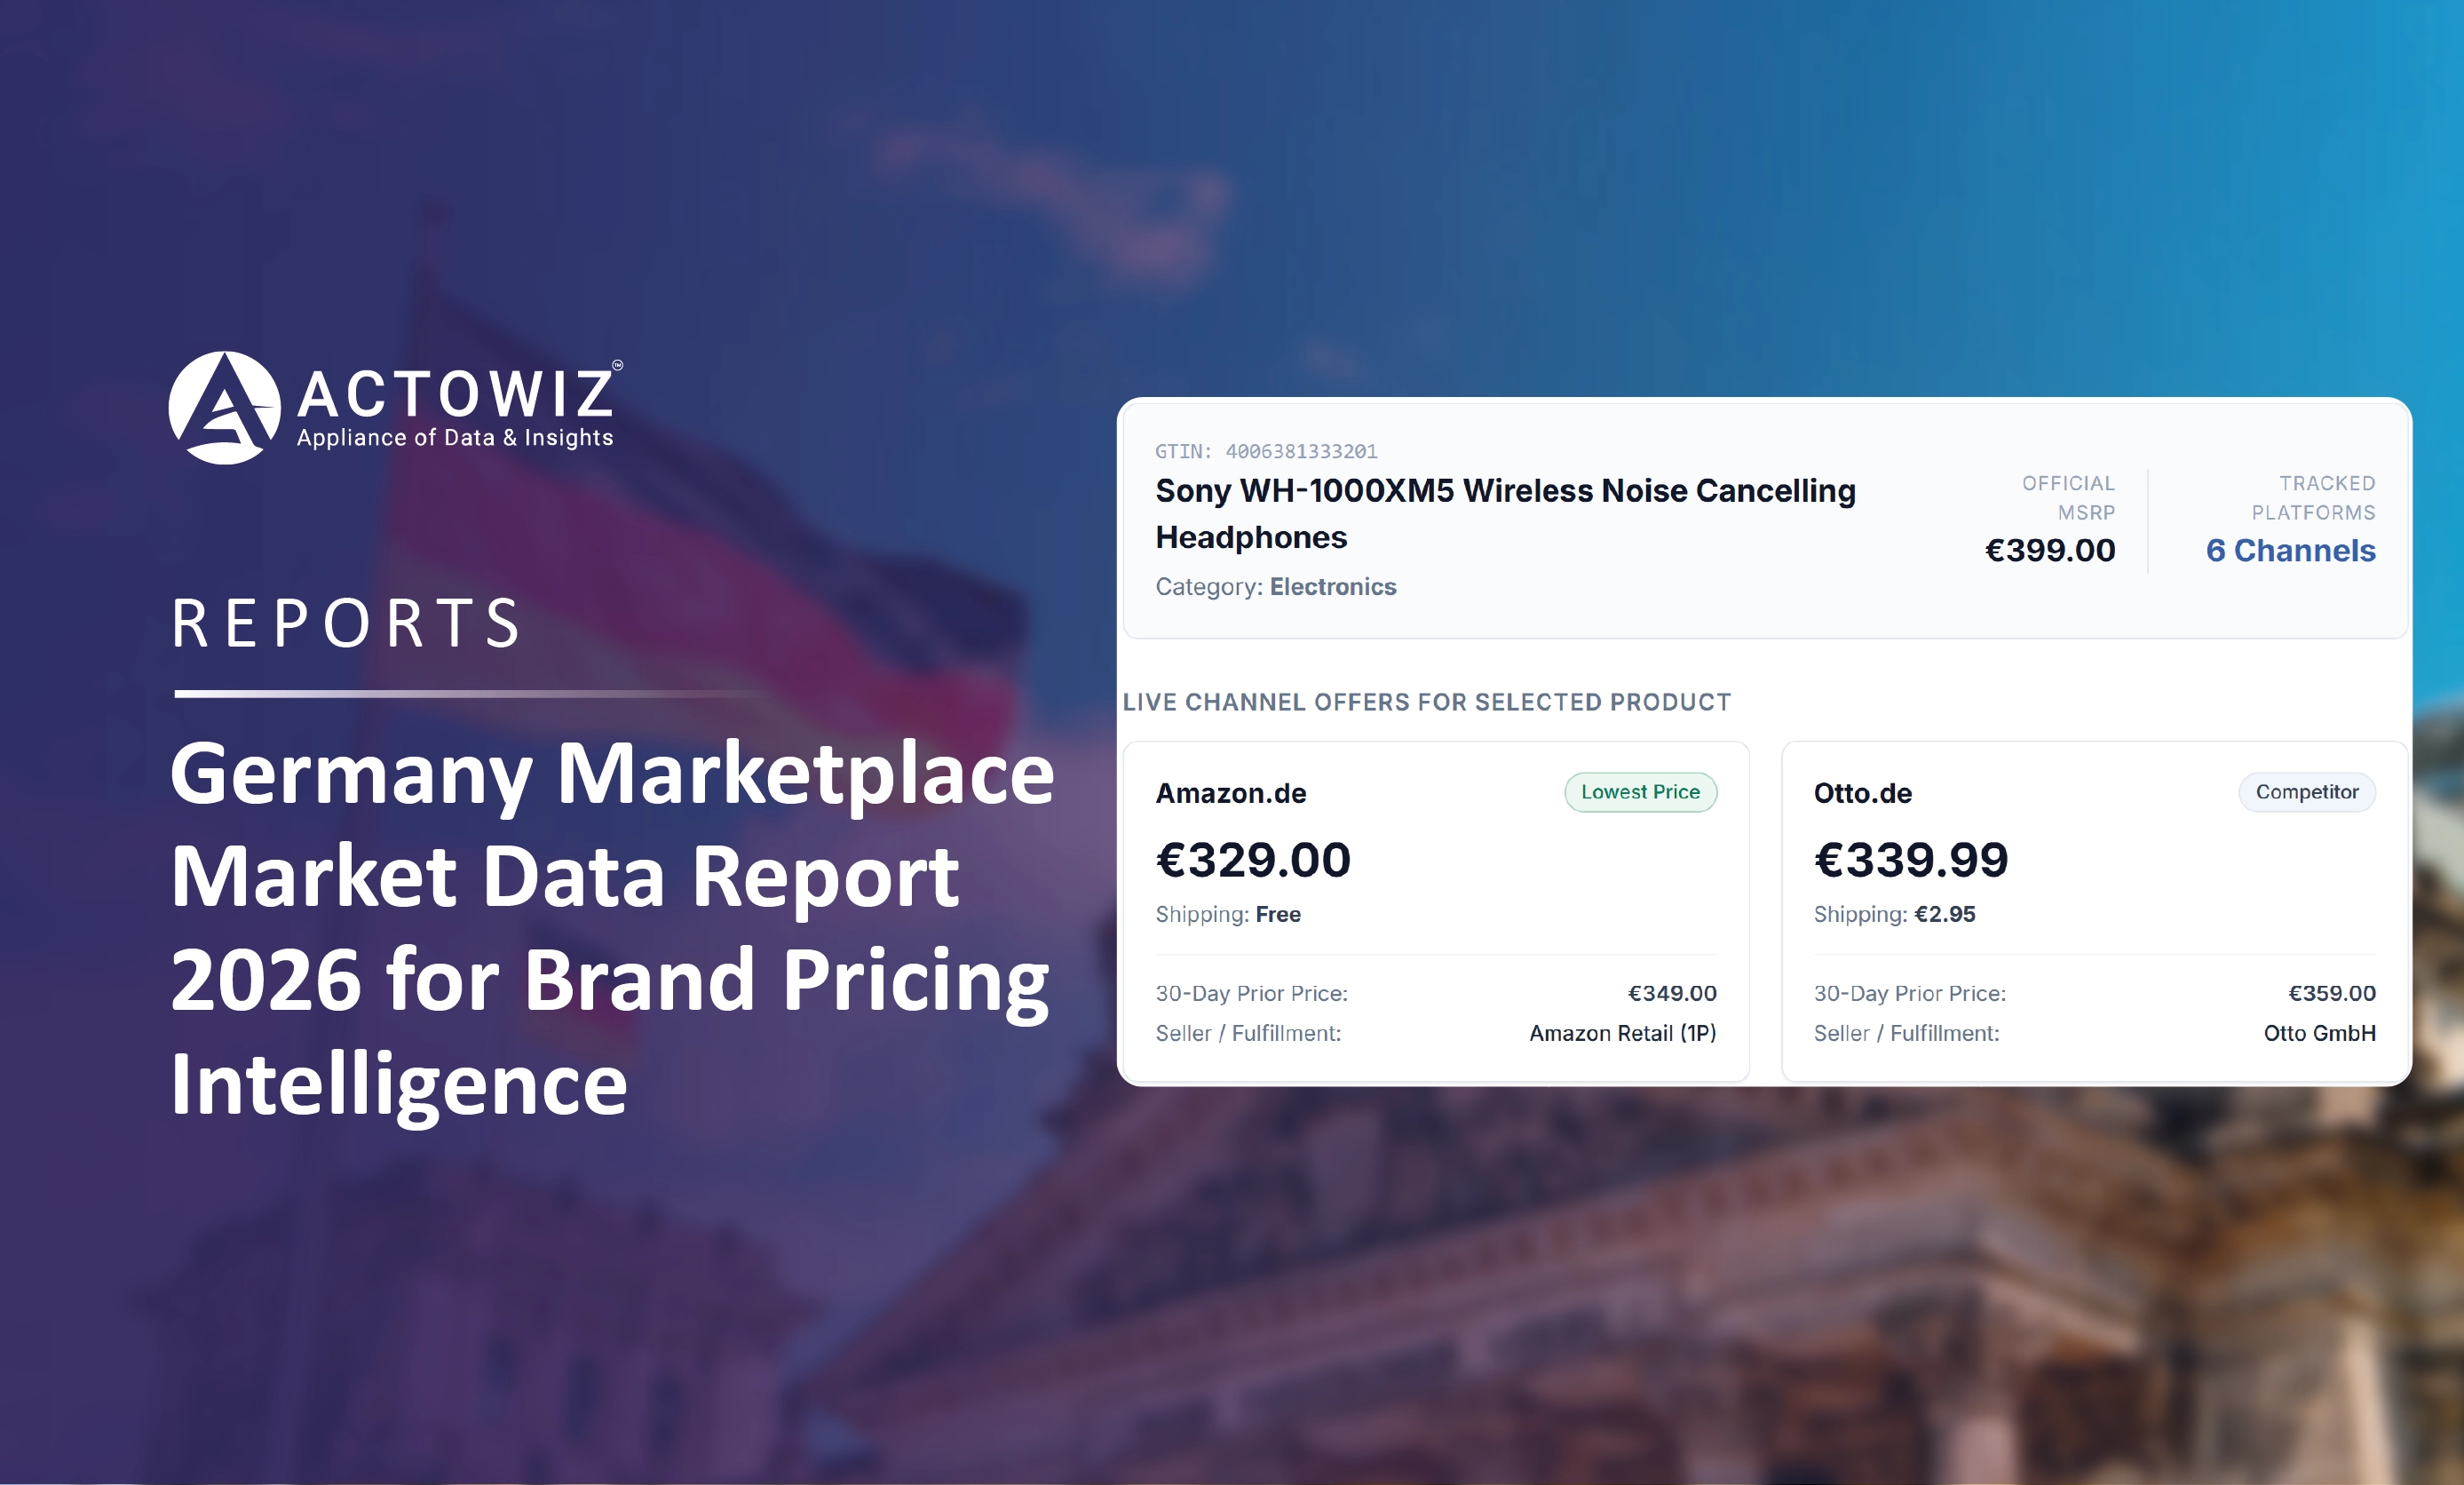
Germany Marketplace Market Data Report 2026 for Brand Pricing Intelligence

German marketplace data report 2026: online retail size, Amazon.de, Otto, Kaufland and Zalando price signals, PAngV rules and peak seasons.

Start Where It Makes Sense for You

Whether you're a startup or a Fortune 500 — we have the right plan for your data needs.

icons
Enterprise
Book a Strategy Call
Custom solutions, dedicated support, volume pricing for large-scale needs.
icons
Growing Brand
Get Free Sample Data
Try before you buy — 500 rows of real data, delivered in 2 hours. No strings.
icons
Just Exploring
View Plans & Pricing
Transparent plans from $500/mo. Find the right fit for your budget and scale.
Get in Touch
Let's Talk About
Your Data Needs
Tell us what data you need — we'll scope it for free and share a sample within hours.
  • icons
    Free Sample in 2 HoursShare your requirement, get 500 rows of real data — no commitment.
  • icons
    Plans from $500/monthFlexible pricing for startups, growing brands, and enterprises.
  • icons
    US-Based SupportOffices in New York & California. Aligned with your timezone.
  • icons
    ISO 9001 & 27001 CertifiedEnterprise-grade security and quality standards.
Request Free Sample Data
Fill the form below — our team will reach out within 2 hours.
+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours

Request Free Sample Data

Our team will reach out within 2 hours with 500 rows of real data — no credit card required.

+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours