Core services
Enterprise Data Extraction

Scalable web, app and AI-powered collection across 40+ countries.

All 58 services →
New 2026
AI Training Data

Corpus building with provenance and opt-out compliance.

Learn more →
Free pilot
24-hour sample

We run collection on your own sources before you commit.

Get a sample →
58Services
40+Countries
DEVELOPER

Ready-Made Scrapers

Pre-built for top platforms. Self-serve, no setup.

View All →
TRY FREE

API Playground

Test endpoints instantly. No credit card.

Start Free →
28Tools
2SDKs
icons Delivery & SDKs
Streaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
Need it managed instead?

Fixed monthly retainer, named engineer, no per-request metering.

Managed Data API →
HOT

Case Studies

How brands use Actowiz, with named outcomes.

Read →
FREE

Sample Datasets

Real output, no signup.

Download →
NEW

ROI Calculator

Model the return on a data engagement.

Calculate →
New restaurant openings data tracking on Swiggy and Zomato

Introduction

A client asks how many new restaurants opened in Pune last month. You crawl Swiggy for Pune, get a listing count, and realise the number tells you nothing. You have a stock figure. The question was about flow.

This is the central design problem in new-listing detection. Openings are a delta, not a snapshot. No single crawl of any food delivery platform can tell you how many restaurants are new, because listings carry no reliable "date added" field. The answer has to be built out of repeated observation — baseline construction, delta calculation, the four false-positive classes that wreck naive counts, geo-sampling design, and the mirror problem of closure detection.

Why one crawl cannot answer the question

Suppose you crawl Zomato for Bengaluru and find a total listing count. To extract openings you would need a trustworthy creation timestamp per listing. In practice, platforms rarely expose one; where a date-like field exists it often reflects last profile edit rather than first appearance; and "new" badges in the app are marketing flags with undisclosed rules.

So the only defensible definition of a new listing is observational: an entity present in period t that was absent in period t-1, under a stable and repeated sampling method.

All the weight sits on "stable" and "repeated". If your sample area shifts, your crawl depth changes, or your parser starts missing a listing card type, your delta measures your own instability rather than the market.

Building the baseline

The baseline is a full enumeration of listings for a defined geography, captured at a fixed point, every record carrying a stable identity key.

Identity is the hard part. You need a key that survives a restaurant renaming itself or moving one street over. A practical composite:

Key component Stability Notes
Platform outlet ID High when present Best primary key; preserve verbatim
Normalised name Medium Lowercased, punctuation and branch suffixes stripped
Geocode Medium-high Round to ~5 decimals; small drifts are normal
Address hash Medium Breaks when the platform reformats addresses
Cuisine tag set Low Tiebreaker only

Store all of them. A match on platform ID is conclusive. Normalised name plus geocode within a small radius is strong. Anything weaker goes to a review queue, not straight into the "new" bucket.

Run the baseline at least twice before trusting it. Two full passes a few days apart expose the listings your crawl sees only intermittently — exactly the records that later masquerade as openings.

The four false positives that break naive counts

New restaurant openings data tracking on Swiggy and Zomato

Most of the work in this problem is not detection. It is disqualification. Four classes of record will appear as "absent last month, present this month" without any restaurant having opened.

1. Re-listings. An outlet was delisted, deactivated or hidden, then returned, possibly under a new outlet ID. Defence: keep a long-lived archive of retired records and check every candidate against full history, not just the prior period.

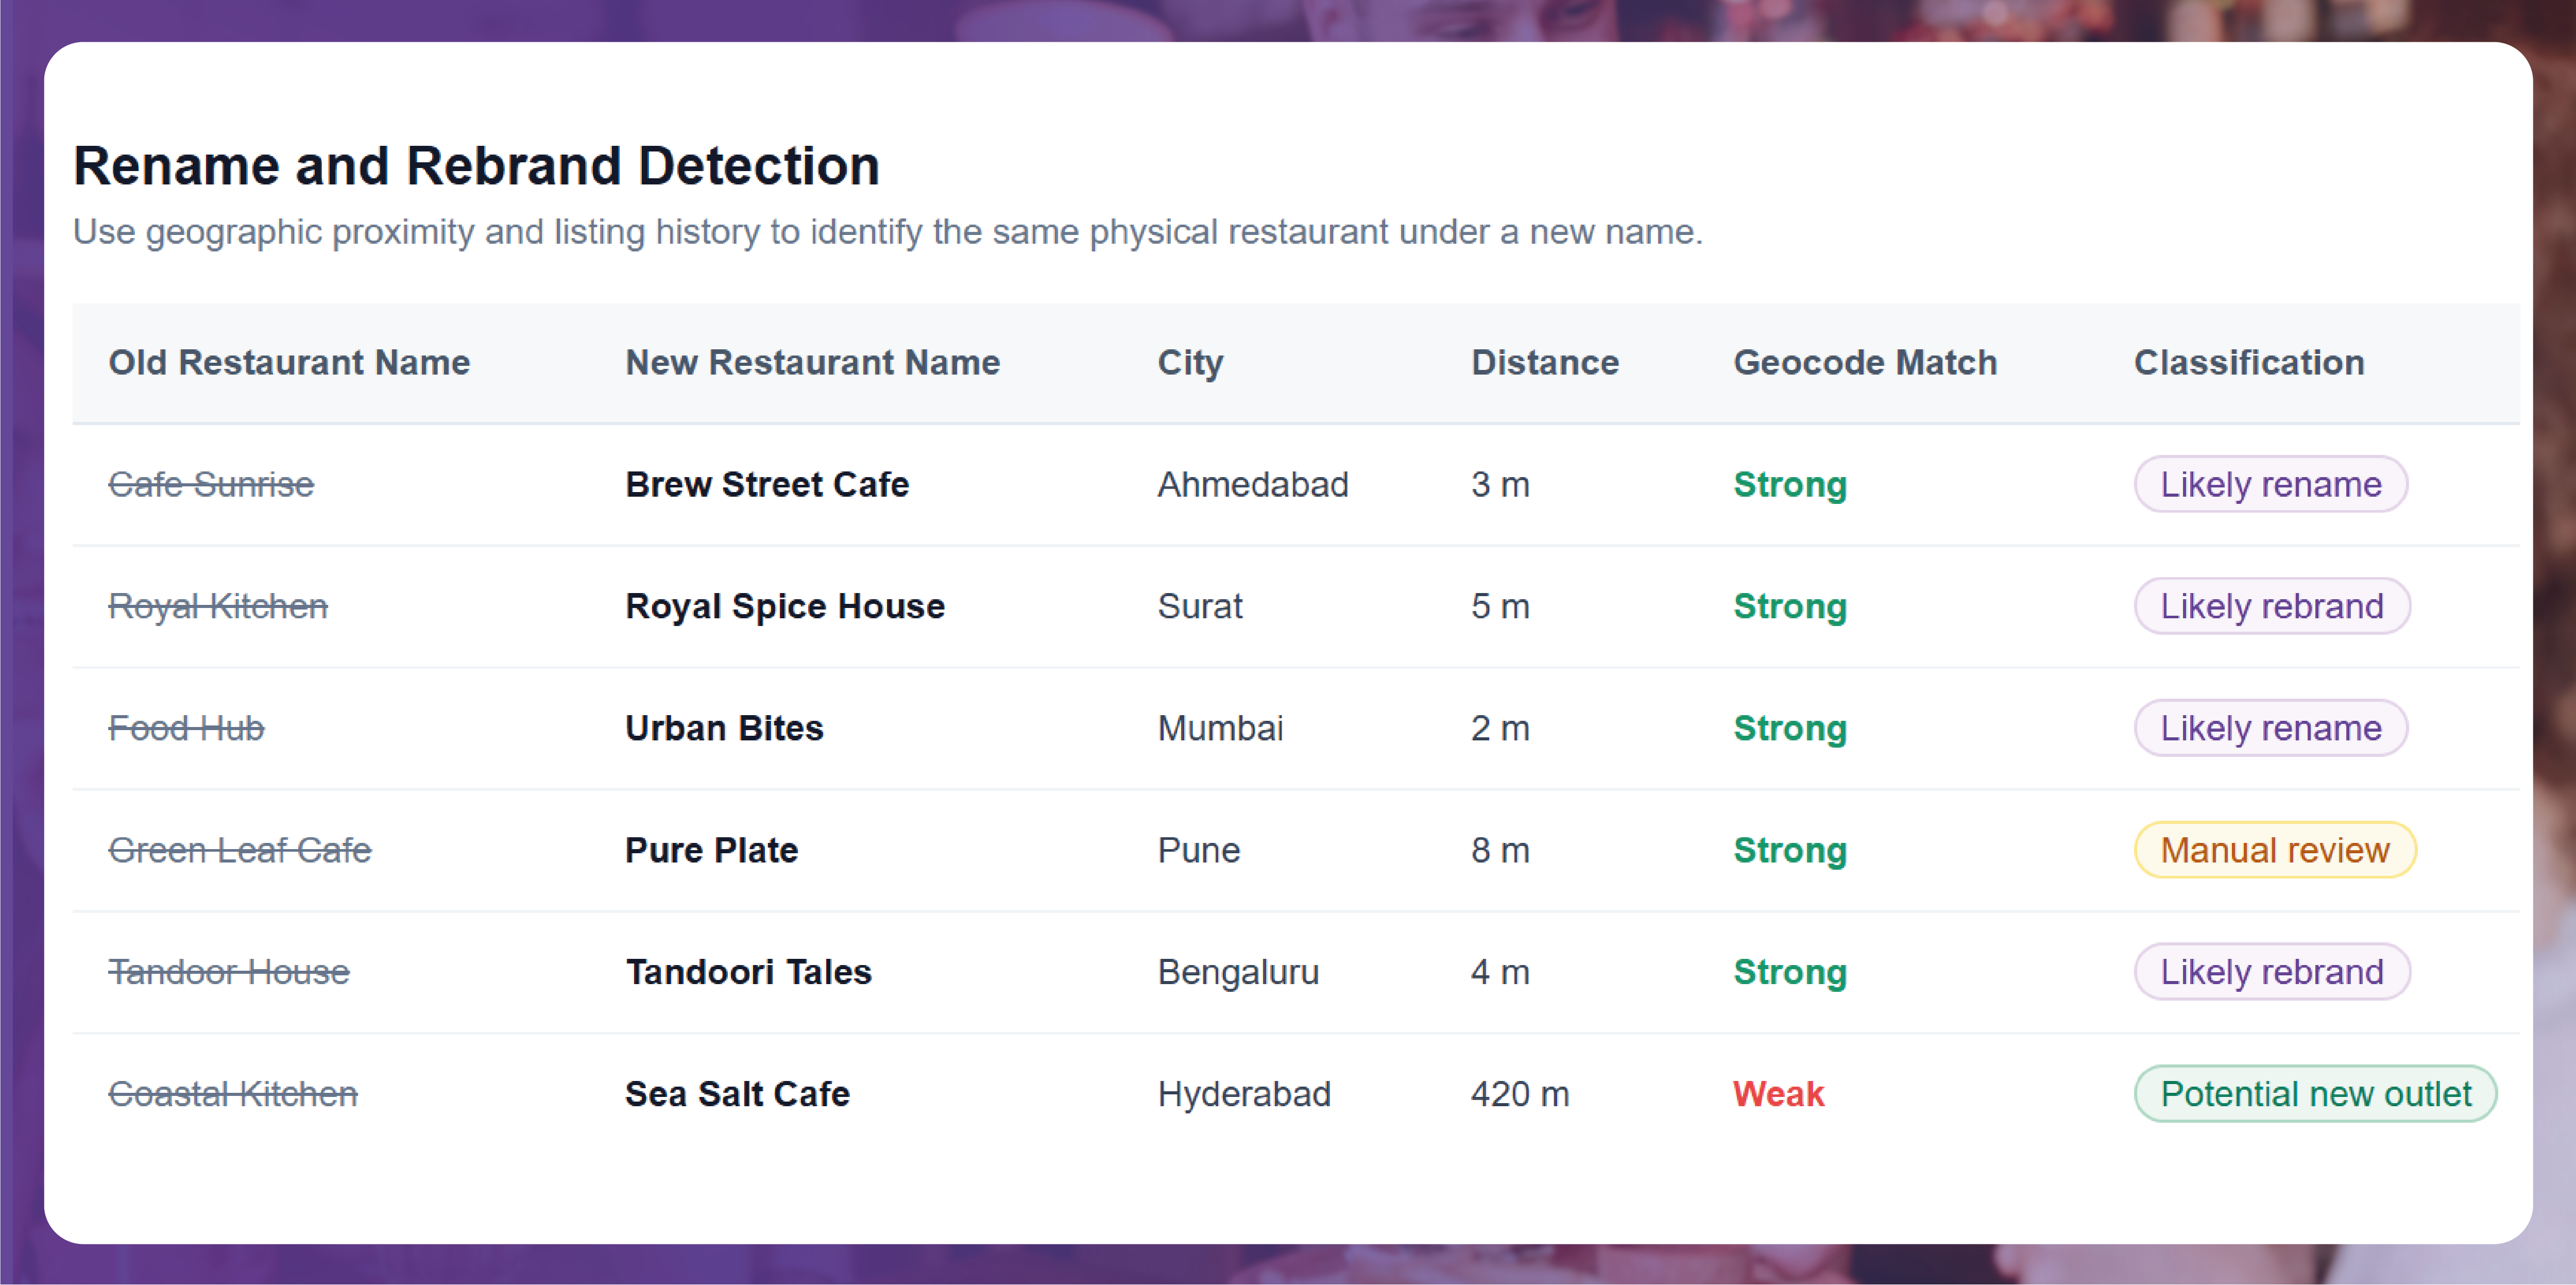
2. Renames and rebrands. The same kitchen at the same address changes trading name — absent on name, present on name, identical on geocode. Defence: geocode-first matching. A candidate sitting within a few metres of a record that disappeared in the same period is a rename until proven otherwise.

3. Cloud-kitchen brands stacked on one kitchen. The most consequential class in Indian metros. One physical kitchen may run several virtual brands, each a separate listing. Brand four launching is a new listing, not a new kitchen. Defence: report both. Maintain a kitchen-level rollup keyed on geocode plus licence identifiers where visible, and publish new-listing and estimated new-kitchen counts separately. Never merge them silently.

4. Serviceability changes. Listings are filtered by whether the outlet delivers to your query location. A two-year-old outlet becomes visible when the platform widens its radius, or when you query a slightly different coordinate. Defence: fix sampling coordinates permanently, never re-deriving them per run, and treat first-appearance at one point differently from first-appearance across the city grid.

That fourth class is why ad-hoc scrapes produce wildly inflated opening counts. Serviceability noise dominates genuine openings in most months.

Geo-sampling design for a city

Because listings are serviceability-filtered, one query point does not enumerate a city. You need a set of sample points whose delivery catchments overlap enough to cover the city without gaps.

Two viable designs:

Grid sampling. Lay a regular lattice over the built-up area, spaced meaningfully smaller than the typical delivery radius so catchments overlap. Tighten in dense cores, loosen at peri-urban fringes.

Locality sampling. Use the platform's own locality taxonomy plus a point per administrative ward. This matches how demand is organised, but locality lists change, which is itself a stability risk.

A hybrid works best: locality centroids for reporting, plus a background grid to catch what the locality list misses.

Design parameter How to set it Failure if set wrong
Point spacing Fraction of observed median delivery radius Coverage holes that look like closures
Point count per city Built-up area and density tiers Month-to-month variance swamps the signal
Coordinate persistence Frozen at project start, versioned on change Drifting points create phantom openings
Crawl depth per point To end of list, not first N cards Truncation makes the tail look volatile
Cadence Fixed calendar day, same weekday band Weekday mix changes visible inventory

Document the point set as a versioned artefact. When it changes, restate the historical series or break it explicitly. Silent geography changes are the most common reason a listings series stops being comparable with itself.

Field schema for a listing record

Every pass writes one row per outlet per sample point, plus a deduplicated city-level roll-up.

Field Type Purpose
observation_date date Pass identifier
platform enum Swiggy, Zomato, other
sample_point_id string Which fixed coordinate produced this sighting
outlet_id_platform string Platform's own identifier, verbatim
name_raw / name_normalised string Untouched / lowercased, suffix-stripped
brand_key string Chain grouping key, null for independents
latitude, longitude float Listing geocode
cuisine_tags array As listed
rating_value, rating_count float, int Secondary signal; rating_count near zero supports newness
is_serviceable boolean Deliverable to this sample point at this time
listing_status enum Open, closed-for-now, temporarily unavailable
first_seen_date, last_seen_date date Derived, not scraped
evidence_class enum new / re-listing / rename / stacked-brand / serviceability

rating_count deserves attention. A genuinely new outlet starts with very few reviews; a re-listing usually carries its rating history forward. Low review volume is corroborating evidence, not proof, and should never be the sole test.

The monthly delta calculation

For city c, month m:

  • Deduplicate month m sightings to one row per outlet, city level.
  • Left-anti-join against the cumulative history of all outlets ever seen in c, not just month m-1.
  • Route each candidate through the disqualification tests: archive match, geocode-proximity rename check, stacked-brand rollup, serviceability check against sample-point history.
  • Report: gross new listings, net of re-listings, net of renames, and estimated new kitchens. Four numbers, not one.
  • Attach a coverage statistic — how many sample points returned a complete response this pass — so a soft month can be distinguished from a partial collection.

That coverage statistic is what separates a measurement from a guess. If the share of sample points with complete response drops, the delta is not comparable and you say so.

Closure detection is the same problem, mirrored

An outlet absent this month may have closed, gone temporarily unavailable, dropped out of your serviceability window, or been missed by a failed request.

The rule that keeps closure counts honest: require persistent absence across multiple consecutive passes and multiple sample points before classifying a closure. A single-pass disappearance is noise. Distinguish closure from listing_status = closed-for-now, which is an operating-hours state, not a business outcome.

Closures need a longer confirmation window than openings, so closure figures lag. Report them with their own as-of date rather than forcing both into one table.

Who uses this and what they do with it

FMCG distribution planning. New-outlet density by locality shows where a distributor's route coverage is falling behind. The metric is new listings per locality per month, compared against serviced-account lists.

Cloud-kitchen site selection. Operators want localities with rising listing counts but a thin brand set in their target cuisine — a two-axis read on listing growth and cuisine concentration.

Consultancies and market-entry teams. Openings flow updates monthly, unlike licensing data. Useful for reading a category's momentum in a city, expressed as share of new listings by cuisine, not as any claim about revenue.

POS, supply and fintech vendors prospecting. A confirmed new listing is a timely lead. Here freshness beats depth, which argues for higher cadence on a narrower field set.

Each needs the same pipeline and a different aggregation. Build the record once; aggregate many ways.

Actowiz Solutions runs fixed-geography, fixed-cadence collection across Swiggy, Zomato and other delivery platforms, with versioned sample-point sets and full observation history retained for delta work.

We deliver the four-number opening series with coverage statistics attached, so you can tell a real market movement from a collection artefact.

Frequently Asked Questions

Can you tell how many restaurants opened in a city from a single scrape?

No. Openings are a difference between two observations. A single crawl gives a total listing count with no reliable creation date, so a baseline and at least one repeat pass under identical sampling are required.

How do you separate a genuinely new restaurant from a re-listing or rename?

By checking each candidate against the full historical archive, not just the prior month, and by matching on geocode proximity as well as name. Candidates that match a recently disappeared outlet at the same location are classified as renames.

Why do new-listing counts differ depending on where the crawl queries from?

Delivery platforms filter listings by serviceability to the querying location. Sample coordinates must be fixed permanently and versioned, or changes in delivery radius will appear as openings.

You can also reach us for all your mobile app scraping, data collection, web scraping, and instant data scraper service requirements!

Request a free sample dataset of new restaurant openings on Swiggy and Zomato with coverage statistics.
Get a free sample dataset
Social Proof That Converts

Trusted by Global Leaders Across Q-Commerce, Travel, Retail, and FoodTech

Our web scraping expertise is relied on by 4,000+ global enterprises including Zomato, Tata Consumer, Subway, and Expedia — helping them turn web data into growth.

4,000+ Enterprises Worldwide
50+ Countries Served
20+ Industries
Join 4,000+ companies growing with Actowiz →
Real Results from Real Clients

Hear It Directly from Our Clients

Watch how businesses like yours are using Actowiz data to drive growth.

▶
1 min
★★★★★
"Actowiz Solutions offered exceptional support with transparency and guidance throughout. Anna and Saga made the process easy for a non-technical user like me. Great service, fair pricing!"
TG
Thomas Galido
Co-Founder / Head of Product at Upright Data Inc.
▶
2 min
★★★★★
"Actowiz delivered impeccable results for our company. Their team ensured data accuracy and on-time delivery. The competitive intelligence completely transformed our pricing strategy."
II
Iulen Ibanez
CEO / Datacy.es
▶
1:30
★★★★★
"What impressed me most was the speed — we went from requirement to production data in under 48 hours. The API integration was seamless and the support team is always responsive."
FC
Febbin Chacko
-Fin, Small Business Owner
icons 4.8/5 Average Rating
icons 50+ Video Testimonials
icons 92% Client Retention
icons 50+ Countries Served

Join 4,000+ Companies Growing with Actowiz

From Zomato to Expedia — see why global leaders trust us with their data.

Why Global Leaders Trust Actowiz

Backed by automation, data volume, and enterprise-grade scale — we help businesses from startups to Fortune 500s extract competitive insights across the USA, UK, UAE, and beyond.

icons
7+
Years of Experience
Proven track record delivering enterprise-grade web scraping and data intelligence solutions.
icons
4,000+
Projects Delivered
Serving startups to Fortune 500 companies across 50+ countries worldwide.
icons
200+
In-House Experts
Dedicated engineers across scrapers, AI/ML models, APIs, and data quality assurance.
icons
9.2M
Automated Workflows
Running weekly across eCommerce, Quick Commerce, Travel, Real Estate, and Food industries.
icons
270+ TB
Data Transferred
Real-time and batch data scraping at massive scale, across industries globally.
icons
380M+
Pages Crawled Weekly
Scaled infrastructure for comprehensive global data coverage with 99% accuracy.

AI Solutions Engineered
for Your Needs

→
LLM-Powered Attribute Extraction: High-precision product matching using large language models for accurate data classification.
→
Advanced Computer Vision: Fine-grained object detection for precise product classification using text and image embeddings.
→
GPT-Based Analytics Layer: Natural language query-based reporting and visualization for business intelligence.
→
Human-in-the-Loop AI: Continuous feedback loop to improve AI model accuracy over time.
icons Product Matching icons Attribute Tagging icons Content Optimization icons Sentiment Analysis icons Prompt-Based Reporting

Connect the Dots Across
Your Retail Ecosystem

We partner with agencies, system integrators, and technology platforms to deliver end-to-end solutions across the retail and digital shelf ecosystem.

icons
Analytics Services
icons
Ad Tech
icons
Price Optimization
icons
Business Consulting
icons
System Integration
icons
Market Research
Become a Partner →

Popular Datasets — Ready to Download

Browse All Datasets →
icons
Amazon
eCommerce
Free 100 rows
icons
Zillow
Real Estate
Free 100 rows
icons
DoorDash
Food Delivery
Free 100 rows
icons
Walmart
Retail
Free 100 rows
icons
Booking.com
Travel
Free 100 rows
icons
Indeed
Jobs
Free 100 rows

Latest Insights & Resources

View All Resources →
thumb
Blog

Web Data RFP Checklist: How to Write an RFP for Web Data Collection (2026)

Use this web data RFP checklist to define scope, sources, fields, SLA, QA and pricing models, then score vendors fairly.

thumb
Case Study

How Sensitive Skin Skincare Product Data API Helps Brands Track Cleansers, Serums, Moisturizers, and Sunscreens

Sensitive Skin Skincare Product Data API helps brands track cleansers, serums, moisturizers, and sunscreens with structured product data.

thumb
Report

Germany Marketplace Market Data Report 2026 for Brand Pricing Intelligence

German marketplace data report 2026: online retail size, Amazon.de, Otto, Kaufland and Zalando price signals, PAngV rules and peak seasons.

Start Where It Makes Sense for You

Whether you're a startup or a Fortune 500 — we have the right plan for your data needs.

icons
Enterprise
Book a Strategy Call
Custom solutions, dedicated support, volume pricing for large-scale needs.
icons
Growing Brand
Get Free Sample Data
Try before you buy — 500 rows of real data, delivered in 2 hours. No strings.
icons
Just Exploring
View Plans & Pricing
Transparent plans from $500/mo. Find the right fit for your budget and scale.
Get in Touch
Let's Talk About
Your Data Needs
Tell us what data you need — we'll scope it for free and share a sample within hours.
  • icons
    Free Sample in 2 HoursShare your requirement, get 500 rows of real data — no commitment.
  • icons
    Plans from $500/monthFlexible pricing for startups, growing brands, and enterprises.
  • icons
    US-Based SupportOffices in New York & California. Aligned with your timezone.
  • icons
    ISO 9001 & 27001 CertifiedEnterprise-grade security and quality standards.
Request Free Sample Data
Fill the form below — our team will reach out within 2 hours.
+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours

Request Free Sample Data

Our team will reach out within 2 hours with 500 rows of real data — no credit card required.

+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours