Core services
Enterprise Data Extraction

Scalable web, app and AI-powered collection across 40+ countries.

All 58 services →
New 2026
AI Training Data

Corpus building with provenance and opt-out compliance.

Learn more →
Free pilot
24-hour sample

We run collection on your own sources before you commit.

Get a sample →
58Services
40+Countries
DEVELOPER

Ready-Made Scrapers

Pre-built for top platforms. Self-serve, no setup.

View All →
TRY FREE

API Playground

Test endpoints instantly. No credit card.

Start Free →
28Tools
2SDKs
icons Delivery & SDKs
Streaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
Need it managed instead?

Fixed monthly retainer, named engineer, no per-request metering.

Managed Data API →
HOT

Case Studies

How brands use Actowiz, with named outcomes.

Read →
FREE

Sample Datasets

Real output, no signup.

Download →
NEW

ROI Calculator

Model the return on a data engagement.

Calculate →
Real-Time API vs Batch Data for Q-Commerce - Which Approach Solves Data Freshness Challenges?

Introduction

Real-Time API vs Batch Data for Q-Commerce depends on how quickly a business needs information to make decisions. Real-time APIs are better suited to fast-changing prices, inventory, and availability, while batch data is valuable for historical analysis, benchmarking, trend discovery, and large-scale reporting. For most Q-commerce businesses, a hybrid model can connect immediate operational intelligence with deeper historical insights.

Quick commerce has changed the importance of data freshness. When products can be delivered within minutes, information about price, stock, promotions, and assortment can also become outdated quickly. A retailer, brand, marketplace seller, or analytics provider may lose decision-making accuracy if yesterday's data is used to evaluate today's market.

This is why Quick Commerce Data Scraping increasingly requires more than simply collecting product information. Businesses must determine which attributes need real-time monitoring, which can be collected periodically, and which require historical storage for trend analysis.

For example, a stockout detected several hours late may distort availability analysis. A competitor price captured once per day may miss an intraday promotion. Conversely, continuously collecting every historical product attribute through an expensive real-time pipeline can create unnecessary infrastructure and processing costs.

The right approach therefore starts with the business question—not the technology.

What Should Q-Commerce Businesses Choose for Fresh Data?

The practical answer is to match the collection frequency to the rate at which the business variable changes.

Business Requirement Real-Time API Batch Data Recommended Use
Current product price Strong fit Moderate fit Real-time for active pricing
Stock availability Strong fit Limited for urgent decisions Real-time
Historical price trends Can be expensive Strong fit Batch
Competitor benchmarking Strong fit Strong fit Hybrid
Large catalog analysis Possible Strong fit Batch
Promotion detection Strong fit Moderate fit Real-time/hybrid
Long-term forecasting Limited alone Strong fit Batch
Operational alerts Strong fit Weak fit Real-time
Executive reporting Useful Strong fit Batch
Data warehouse creation Useful Strong fit Hybrid

The most effective architecture often uses real-time collection for volatile attributes and scheduled datasets for slower-moving or historical information.

How Does Fresh Operational Data Improve Q-Commerce Decisions?

Real-Time API vs Batch Data for Q-Commerce - Which Approach Solves Data Freshness Challenges?

Real-Time Q-Commerce Data API is designed around immediacy. Instead of waiting for a scheduled extraction cycle, businesses can receive or retrieve updated information when a decision depends on current market conditions.

This matters because Q-commerce operates across highly dynamic variables. Product prices can change during the day. Promotional campaigns may be activated for short periods. Stock availability can fluctuate as orders arrive. Delivery zones can also influence whether a product is visible to a customer.

A real-time architecture can therefore support applications such as:

  • Price-change alerts
  • Stockout monitoring
  • Promotion detection
  • Availability tracking
  • Competitor event monitoring
  • Dynamic assortment analysis
  • Operational dashboards
  • Automated decision workflows

The major advantage is freshness. If a business needs to respond within minutes, a daily or hourly dataset may not be sufficient.

What Does the Data Flow Look Like?

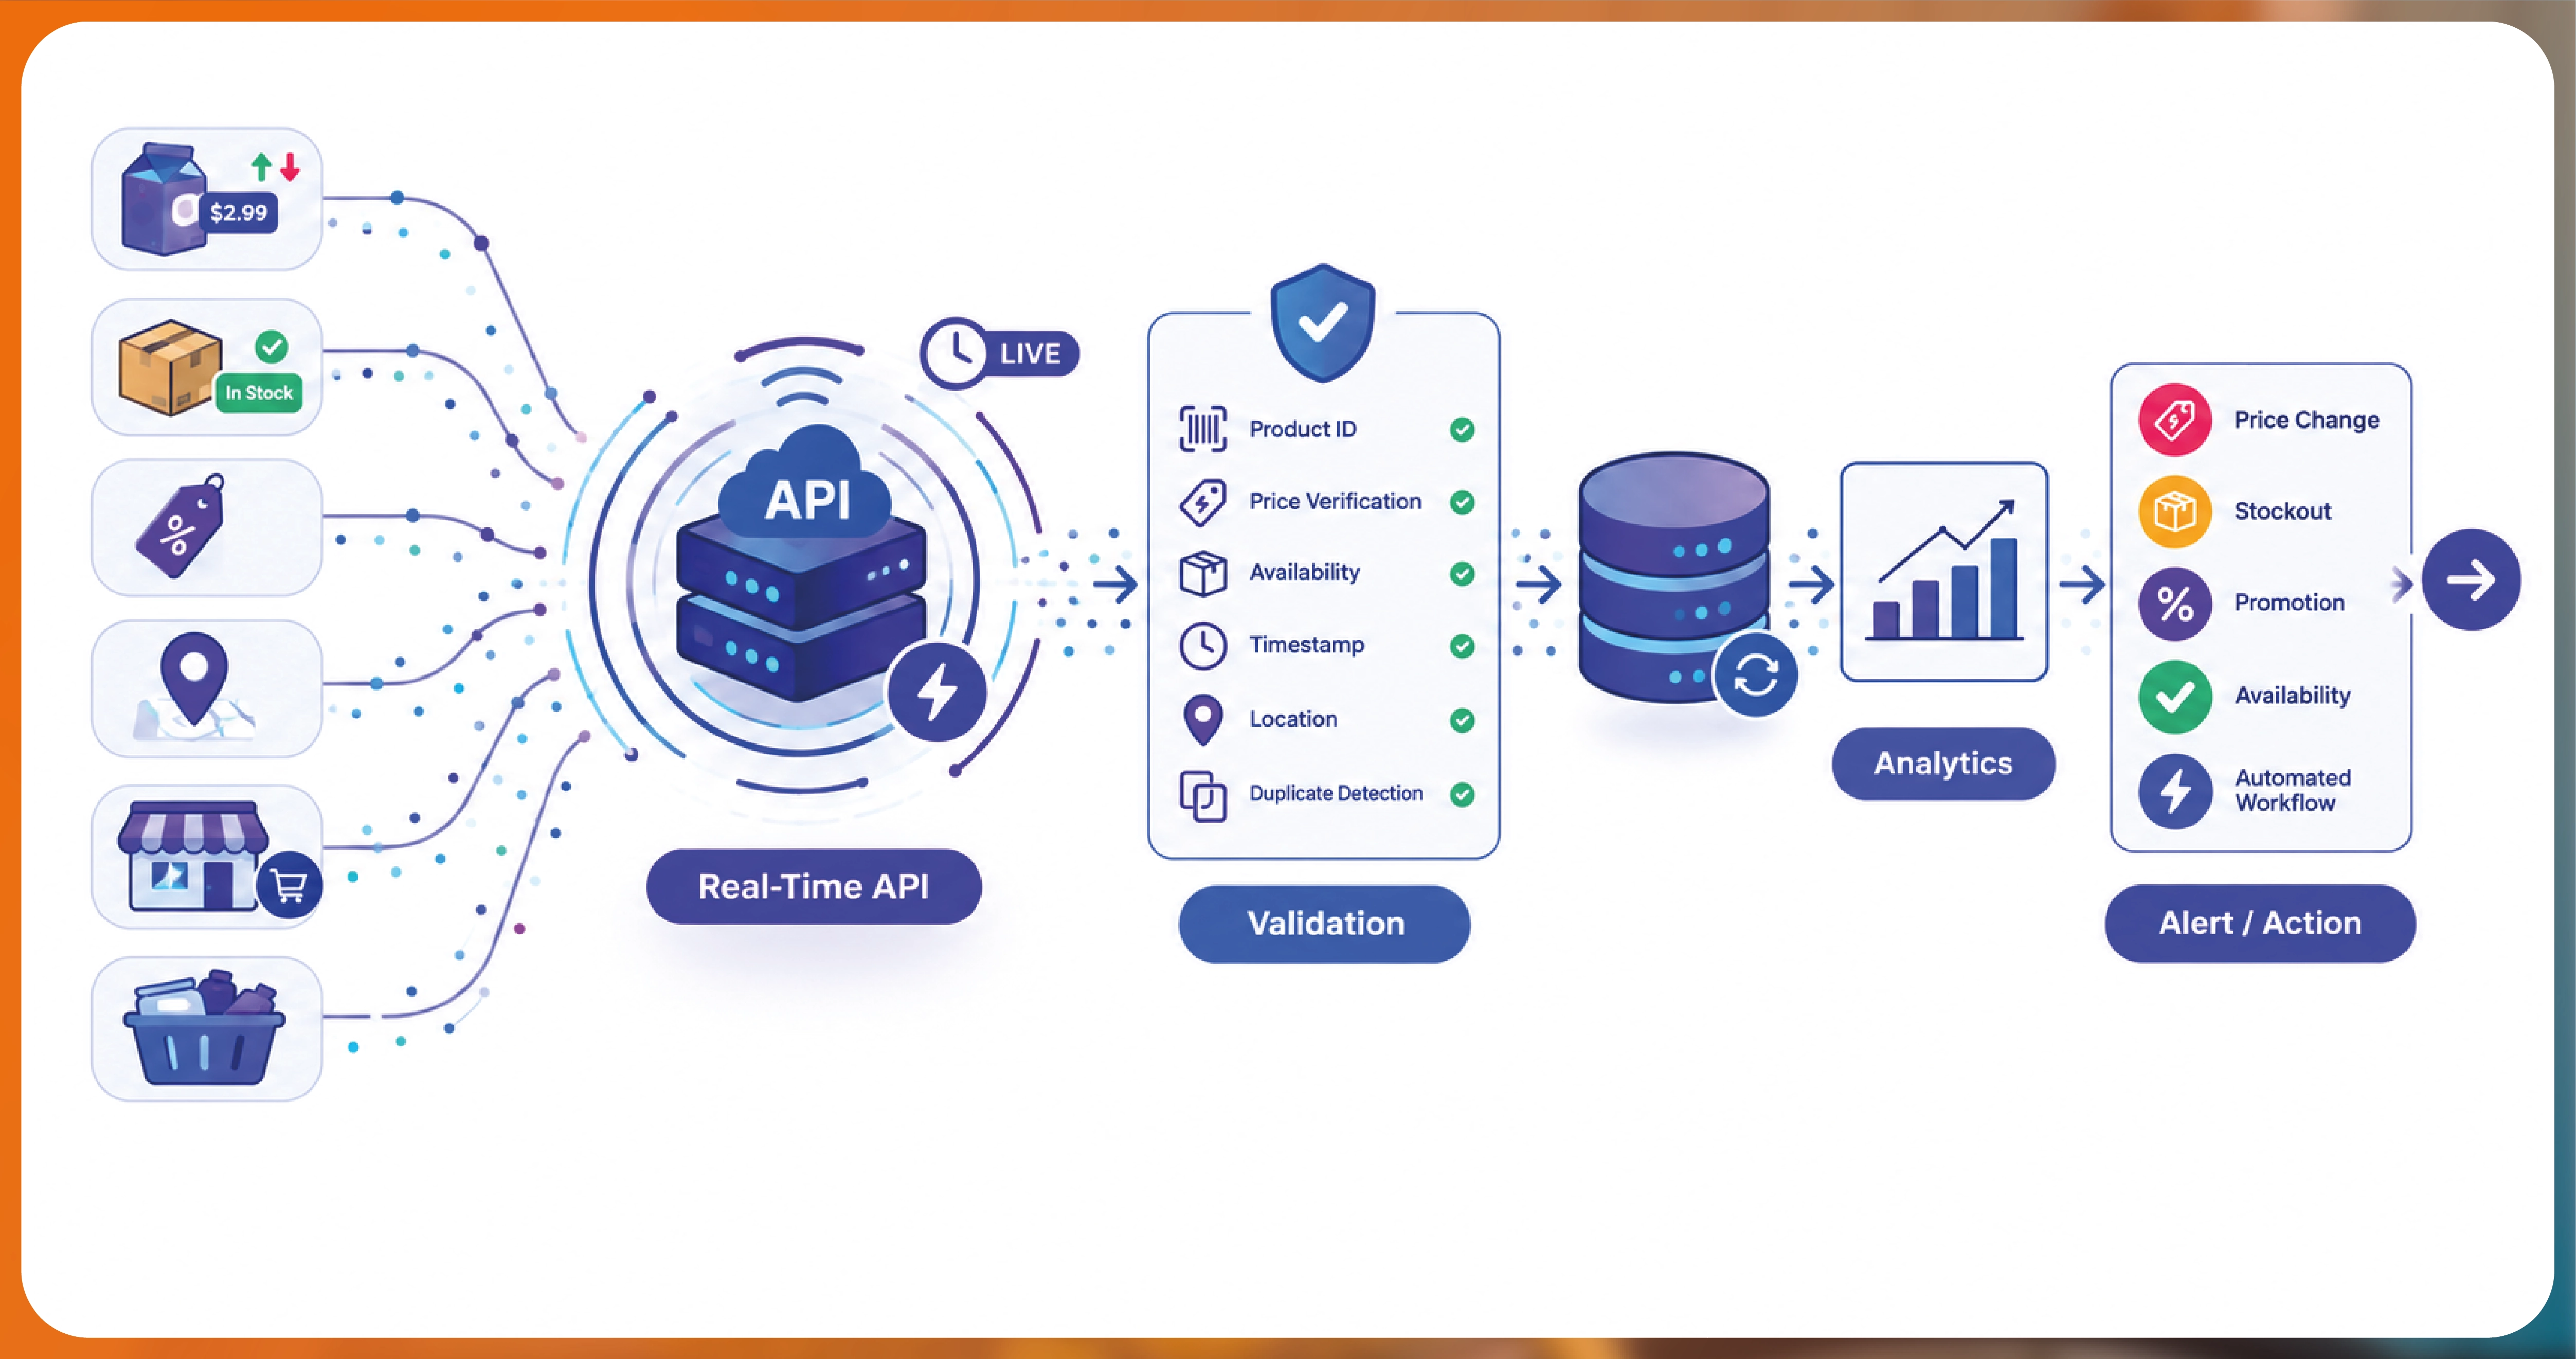
A typical real-time pipeline can follow this structure:

Source → API/Data Collection → Validation → Normalization → Database → Analytics → Alert/Action

The validation stage is important. Fresh data is not automatically useful data. A real-time system should still check product identifiers, prices, availability states, timestamps, location information, and duplicate records before the information reaches downstream applications.

Key Metrics for Real-Time Monitoring
Metric Why It Matters
Data latency Shows how quickly source changes reach the system
Update frequency Measures how often records are refreshed
Availability accuracy Helps identify actual stock conditions
Price-change detection Identifies competitive movement
API success rate Measures pipeline reliability
Data completeness Shows whether required attributes are captured

A useful operational target is not simply "real time." Businesses should define an acceptable freshness window, such as five minutes, fifteen minutes, or one hour, based on the business decision being supported.

When Does Scheduled Collection Make More Sense?

Q-Commerce Batch Data Extraction collects information according to a predefined schedule. Depending on the use case, the process may run hourly, several times per day, daily, weekly, or according to another business-defined interval.

Batch collection is especially useful when the goal is analysis rather than immediate intervention.

Consider a retailer analyzing six months of competitor pricing. It does not necessarily need an API response every minute. Instead, it needs a consistent historical dataset containing timestamps, products, prices, promotions, availability, and seller or location information.

Batch data can also simplify large-scale processing. Thousands or millions of records can be collected, normalized, validated, and loaded into a warehouse for analysis.

Where Batch Collection Creates Value
Use Case Why Batch Works
Historical trend analysis Builds consistent time-series data
Product catalog analysis Handles large volumes efficiently
Price benchmarking Enables comparable historical snapshots
Assortment analysis Supports category-level comparisons
Forecasting Provides historical training data
Management reporting Produces structured reporting datasets
Market research Enables cross-period comparisons

Batch processing also provides predictable infrastructure requirements. Instead of maintaining continuous pipelines for every attribute, businesses can prioritize collection schedules according to data volatility.

The Freshness Trade-Off

The weakness of batch processing is obvious: the dataset can become stale between collection cycles.

If a Q-commerce platform changes a product price at 10:15 AM and the next scheduled extraction happens at 6 PM, the dataset does not capture the change when it occurred.

That does not make batch data ineffective. It means the collection frequency should match the rate of change.

How Can Businesses Compare the Two Data Models?

Real-Time vs Batch Q-Commerce Data Scraping is not necessarily an either-or decision. The more useful question is which data attributes require immediate visibility and which can be analyzed through scheduled snapshots.

For example, current price and stock availability may require frequent refreshes, while product descriptions, brand information, category classifications, and historical performance can be processed less frequently.

This creates a hybrid architecture.

Real-Time API vs Batch Data for Q-Commerce: Practical Comparison
Factor Real-Time Approach Batch Approach
Freshness Very high Depends on schedule
Infrastructure More continuous More scheduled
Historical depth Requires storage strategy Naturally suited
Cost control Can increase with frequency Generally easier to schedule
Immediate alerts Excellent Limited
Large historical analysis Requires accumulated data Excellent
Price monitoring Excellent Good for snapshots
Inventory monitoring Excellent Good for trend analysis
Forecasting Needs historical layer Excellent
Operational complexity Higher Generally simpler

The ideal solution depends on the buyer persona.

For Q-Commerce Operators

Operators may prioritize inventory, fulfillment, availability, and assortment signals.

For Consumer Brands

Brands may focus on competitor prices, product availability, promotions, share of assortment, and digital shelf visibility.

For Retailers

Retailers may need category benchmarking, price intelligence, SKU monitoring, and historical market comparisons.

For Data and Analytics Teams

Analytics teams usually need both fresh signals and historical records so that real-time observations can be interpreted within a longer trend.

The strongest architecture connects the two rather than treating them as competing systems.

How Can Stock Visibility Be Improved?

Extract Q-Commerce Stock Availability Data when inventory visibility is directly connected to pricing, sales, fulfillment, or competitive decisions.

Stock availability is particularly sensitive in quick commerce because product visibility can change rapidly. A product may be listed in the morning, become unavailable during peak demand, and return later after replenishment.

A single daily snapshot may therefore hide important availability patterns.

Businesses can monitor fields such as:

  • Product ID or SKU
  • Product name
  • Brand
  • Category
  • Pack size
  • Current price
  • Discount
  • Availability status
  • Location or service area
  • Product URL
  • Timestamp
  • Promotion status
  • Seller or fulfillment information where available
Example Availability Dataset
SKU Product Location Price Availability Timestamp
QC101 Product A Zone 1 ₹149 In Stock 10:00
QC101 Product A Zone 1 ₹149 Out of Stock 12:00
QC101 Product A Zone 1 ₹159 In Stock 15:00
QC205 Product B Zone 2 ₹299 Low/Available 16:00

The value comes from the sequence, not just the individual record.

With timestamped observations, businesses can identify recurring stockouts, availability gaps, regional differences, and relationships between price changes and product availability.

What Can Historical Availability Reveal?

Suppose a product is unavailable every evening between 7 PM and 9 PM. A real-time monitoring system can detect the event, while a historical dataset can reveal that the event is recurring.

That distinction is important.

Real-time data identifies what is happening. Historical data helps explain why it keeps happening.

Why Should Businesses Build Long-Term Data History?

A Historical Q-Commerce Dataset turns individual observations into a usable business asset.

Real-time data is valuable for immediate action, but without storage, today's signal can disappear tomorrow. Historical data allows teams to reconstruct market movements and compare performance across periods.

For example, a historical dataset can answer:

  • When did competitor prices change?
  • How often did a product go out of stock?
  • Which brands increased promotional activity?
  • How did assortment change over time?
  • Which products experienced recurring discounts?
  • Which locations had stronger availability?
  • How frequently did competitors introduce new SKUs?
Suggested Historical Data Structure
Field Example Purpose
Timestamp Establishes when data was observed
SKU Enables product-level tracking
Product name Identifies the item
Brand Supports brand analysis
Category Enables category benchmarking
Price Measures price movement
Discount Tracks promotional intensity
Availability Measures stock visibility
Location Enables geographic analysis
URL Maintains source reference
Collection method Distinguishes real-time/batch records
2020–2026: How Has the Market Changed?

From 2020 onward, quick commerce moved from an emerging convenience model into a significant part of India's digital retail ecosystem. Data published by DataWeave shows Indian quick-commerce GMV rising from about $0.1 billion in 2020 to $0.2 billion in 2021, $1.6 billion in 2022, $2.3 billion in 2023, and $2.8 billion in 2024. Reuters, citing Bain & Company and Flipkart, reported that quick commerce accounted for more than two-thirds of India's e-grocery orders in 2024, with the market reaching roughly $6–7 billion and representing 10% of total e-retail spending. A 2026 PayNXT360 market update estimates the Indian market reached $5.48 billion in 2024 and forecasts continued expansion through 2029. Meanwhile, a January 2026 SEBI-filed prospectus citing Redseer estimated 1.1–1.3 billion quick-commerce shipments in FY2025, with annual shipment growth projected at 29–44% through FY2030. These figures illustrate why data infrastructure has become increasingly important: as transaction frequency, assortment, geographic coverage, and competitive activity expand, businesses need both fresh operational signals and structured historical records. The 2020–2026 period therefore represents a transition from basic product visibility toward continuous, location-aware, analytics-ready commerce intelligence.

How Does Competitive Pricing Benefit from Faster Data?

Q-Commerce Competitive Price Tracking helps businesses understand how competitors position products across prices, discounts, availability, and promotions.

Pricing decisions are especially sensitive to data freshness. A competitor may temporarily reduce a product's price during a campaign. If the change is captured only after the promotion ends, the resulting analysis may underestimate competitive intensity.

A structured pricing system can track:

  • Base price
  • Selling price
  • Discount percentage
  • Promotional price
  • Product pack size
  • Brand
  • Category
  • Competitor
  • Location
  • Timestamp
  • Availability
  • Price history
What Does a Price Intelligence Workflow Look Like?

Collect → Validate → Normalize → Match SKUs → Compare → Detect Changes → Analyze → Report

Product matching is one of the most important stages.

Two competing listings may use different titles, pack sizes, images, or descriptions for substantially similar products. Comparing them without normalization can generate misleading conclusions.

For example:

Product Pack Competitor A Competitor B Difference
Brand X 500 g ₹220 ₹210 ₹10
Brand Y 1 kg ₹480 ₹495 ₹15
Brand Z 250 ml ₹140 ₹129 ₹11

The business should compare equivalent products before calculating price gaps.

Why Does Freshness Matter in Competitive Intelligence?

Real-Time API vs Batch Data for Q-Commerce becomes especially relevant when a business wants to detect short-lived pricing events.

A hybrid model can collect high-priority SKUs frequently while processing the broader catalog through scheduled batch jobs.

This approach can reduce unnecessary real-time processing while maintaining visibility into important competitive signals.

How Can Actowiz Solutions Help?

Data Intelligence Services can help businesses design a collection strategy around the speed, volume, and analytical value of their data requirements.

Actowiz Solutions can support structured data workflows for Q-commerce use cases by focusing on collection, normalization, validation, storage, and analytics-ready delivery.

A practical implementation can include:

1. Requirement Mapping

The first step is identifying which attributes require real-time, near-real-time, hourly, daily, or periodic collection.

2. Multi-Source Data Collection

Data can be collected from relevant websites, marketplaces, and mobile applications according to the defined project requirements.

3. Product and SKU Normalization

Product names, pack sizes, categories, prices, availability fields, and identifiers can be standardized to make cross-source comparison easier.

4. Historical Data Storage

Timestamped records can create a structured history of prices, products, promotions, and availability.

5. Validation

Automated validation can check missing values, duplicate records, inconsistent formats, and unexpected changes.

6. Real-Time and Batch Architecture

Real-Time API vs Batch Data for Q-Commerce can be incorporated into a hybrid pipeline, where volatile data receives more frequent updates and slower-moving attributes are collected through scheduled jobs.

7. Analytics-Ready Delivery

Final datasets can be structured for dashboards, business intelligence systems, pricing analysis, forecasting, competitor monitoring, or internal data warehouses.

8. Scalable Data Collection

As product catalogs, cities, categories, and monitored competitors expand, the collection framework can be designed to support increasing data volumes.

The objective is not to collect everything continuously. It is to collect the right information at the right frequency for the right business decision.

What Should Businesses Consider Before Selecting a Data Strategy?

Before choosing between real-time and batch processing, teams should answer five questions:

1. How quickly does the underlying data change?

2. How quickly must the business respond to that change?

3. How much historical data is required?

4. What volume of SKUs and locations must be monitored?

5. Which decisions depend on immediate versus historical information?

A product catalog with slow-changing descriptions may only require periodic collection. Competitor prices and availability may require much more frequent monitoring.

This distinction can help businesses avoid both extremes: collecting stale information or spending resources on unnecessary continuous updates.

What Is the Most Practical Architecture for Q-Commerce?

For many businesses, a three-layer model is practical:

Layer 1 — Real-Time Signals

Monitor prices, stock status, promotions, and other fast-changing attributes.

Layer 2 — Scheduled Catalog Collection

Collect broader product and competitor information periodically.

Layer 3 — Historical Intelligence

Store timestamped records to support trend analysis, forecasting, benchmarking, and strategic planning.

This architecture allows operational teams to respond quickly while giving analysts the historical context required for better decisions.

Conclusion

The choice between real-time and batch processing should be based on business requirements, not simply on the newest technology. Real-time collection is valuable when prices, availability, promotions, or other signals can change quickly and require immediate action. Batch data is highly useful for large-scale catalog analysis, historical benchmarking, reporting, and forecasting.

For Q-commerce businesses, the strongest strategy is often a hybrid model. Use frequent data collection for volatile attributes and scheduled processing for broader datasets. Store both in a structured historical layer so that immediate events can later become strategic insights.

Real-Time API vs Batch Data for Q-Commerce is ultimately a question of freshness, frequency, scale, and decision speed. The right architecture gives every data point an appropriate collection cadence while maintaining the historical context required for deeper analysis.

Actowiz Solutions can help businesses build scalable data workflows around these requirements through AI-Powered Scraping Services, Web Scraping, and Mobile App Scraping, with structured real-time dataset delivery for analytics and decision-making.

You can also reach us for all your mobile app scraping, data collection, web scraping, and instant data scraper service requirements!

Social Proof That Converts

Trusted by Global Leaders Across Q-Commerce, Travel, Retail, and FoodTech

Our web scraping expertise is relied on by 4,000+ global enterprises including Zomato, Tata Consumer, Subway, and Expedia — helping them turn web data into growth.

4,000+ Enterprises Worldwide
50+ Countries Served
20+ Industries
Join 4,000+ companies growing with Actowiz →
Real Results from Real Clients

Hear It Directly from Our Clients

Watch how businesses like yours are using Actowiz data to drive growth.

▶
1 min
★★★★★
"Actowiz Solutions offered exceptional support with transparency and guidance throughout. Anna and Saga made the process easy for a non-technical user like me. Great service, fair pricing!"
TG
Thomas Galido
Co-Founder / Head of Product at Upright Data Inc.
▶
2 min
★★★★★
"Actowiz delivered impeccable results for our company. Their team ensured data accuracy and on-time delivery. The competitive intelligence completely transformed our pricing strategy."
II
Iulen Ibanez
CEO / Datacy.es
▶
1:30
★★★★★
"What impressed me most was the speed — we went from requirement to production data in under 48 hours. The API integration was seamless and the support team is always responsive."
FC
Febbin Chacko
-Fin, Small Business Owner
icons 4.8/5 Average Rating
icons 50+ Video Testimonials
icons 92% Client Retention
icons 50+ Countries Served

Join 4,000+ Companies Growing with Actowiz

From Zomato to Expedia — see why global leaders trust us with their data.

Why Global Leaders Trust Actowiz

Backed by automation, data volume, and enterprise-grade scale — we help businesses from startups to Fortune 500s extract competitive insights across the USA, UK, UAE, and beyond.

icons
7+
Years of Experience
Proven track record delivering enterprise-grade web scraping and data intelligence solutions.
icons
4,000+
Projects Delivered
Serving startups to Fortune 500 companies across 50+ countries worldwide.
icons
200+
In-House Experts
Dedicated engineers across scrapers, AI/ML models, APIs, and data quality assurance.
icons
9.2M
Automated Workflows
Running weekly across eCommerce, Quick Commerce, Travel, Real Estate, and Food industries.
icons
270+ TB
Data Transferred
Real-time and batch data scraping at massive scale, across industries globally.
icons
380M+
Pages Crawled Weekly
Scaled infrastructure for comprehensive global data coverage with 99% accuracy.

AI Solutions Engineered
for Your Needs

→
LLM-Powered Attribute Extraction: High-precision product matching using large language models for accurate data classification.
→
Advanced Computer Vision: Fine-grained object detection for precise product classification using text and image embeddings.
→
GPT-Based Analytics Layer: Natural language query-based reporting and visualization for business intelligence.
→
Human-in-the-Loop AI: Continuous feedback loop to improve AI model accuracy over time.
icons Product Matching icons Attribute Tagging icons Content Optimization icons Sentiment Analysis icons Prompt-Based Reporting

Connect the Dots Across
Your Retail Ecosystem

We partner with agencies, system integrators, and technology platforms to deliver end-to-end solutions across the retail and digital shelf ecosystem.

icons
Analytics Services
icons
Ad Tech
icons
Price Optimization
icons
Business Consulting
icons
System Integration
icons
Market Research
Become a Partner →

Popular Datasets — Ready to Download

Browse All Datasets →
icons
Amazon
eCommerce
Free 100 rows
icons
Zillow
Real Estate
Free 100 rows
icons
DoorDash
Food Delivery
Free 100 rows
icons
Walmart
Retail
Free 100 rows
icons
Booking.com
Travel
Free 100 rows
icons
Indeed
Jobs
Free 100 rows

Latest Insights & Resources

View All Resources →
thumb
Blog

Real-Time API vs Batch Data for Q-Commerce - Which Approach Solves Data Freshness Challenges?

Understand Real-Time API vs Batch Data for Q-Commerce and choose the right data strategy to improve pricing, inventory, availability, and decisions.

thumb
Case Study

How We Help Brands with Wine Data Collection from Tabelog

Discover Wine Data Collection from Tabelog to analyze wine listings, prices, ratings, restaurant trends, menus, and competitive market insights.

thumb
Report

E-Com & Q-Com Review Intelligence Report 2026

Discover how E-Com & Q-Com Review Intelligence Report 2026 helps brands analyze reviews, sentiment, product issues, and customer trends across major platforms.

Start Where It Makes Sense for You

Whether you're a startup or a Fortune 500 — we have the right plan for your data needs.

icons
Enterprise
Book a Strategy Call
Custom solutions, dedicated support, volume pricing for large-scale needs.
icons
Growing Brand
Get Free Sample Data
Try before you buy — 500 rows of real data, delivered in 2 hours. No strings.
icons
Just Exploring
View Plans & Pricing
Transparent plans from $500/mo. Find the right fit for your budget and scale.
Get in Touch
Let's Talk About
Your Data Needs
Tell us what data you need — we'll scope it for free and share a sample within hours.
  • icons
    Free Sample in 2 HoursShare your requirement, get 500 rows of real data — no commitment.
  • icons
    Plans from $500/monthFlexible pricing for startups, growing brands, and enterprises.
  • icons
    US-Based SupportOffices in New York & California. Aligned with your timezone.
  • icons
    ISO 9001 & 27001 CertifiedEnterprise-grade security and quality standards.
Request Free Sample Data
Fill the form below — our team will reach out within 2 hours.
+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours

Request Free Sample Data

Our team will reach out within 2 hours with 500 rows of real data — no credit card required.

+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours