Core services
Enterprise Data Extraction

Scalable web, app and AI-powered collection across 40+ countries.

All 58 services →
New 2026
AI Training Data

Corpus building with provenance and opt-out compliance.

Learn more →
Free pilot
24-hour sample

We run collection on your own sources before you commit.

Get a sample →
58Services
40+Countries
DEVELOPER

Ready-Made Scrapers

Pre-built for top platforms. Self-serve, no setup.

View All →
TRY FREE

API Playground

Test endpoints instantly. No credit card.

Start Free →
28Tools
2SDKs
icons Delivery & SDKs
Streaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
Need it managed instead?

Fixed monthly retainer, named engineer, no per-request metering.

Managed Data API →
HOT

Case Studies

How brands use Actowiz, with named outcomes.

Read →
FREE

Sample Datasets

Real output, no signup.

Download →
NEW

ROI Calculator

Model the return on a data engagement.

Calculate →
Crex Data Scraping - Solving Accuracy and Data Consistency Issues in Cricket Analytics

Introduction

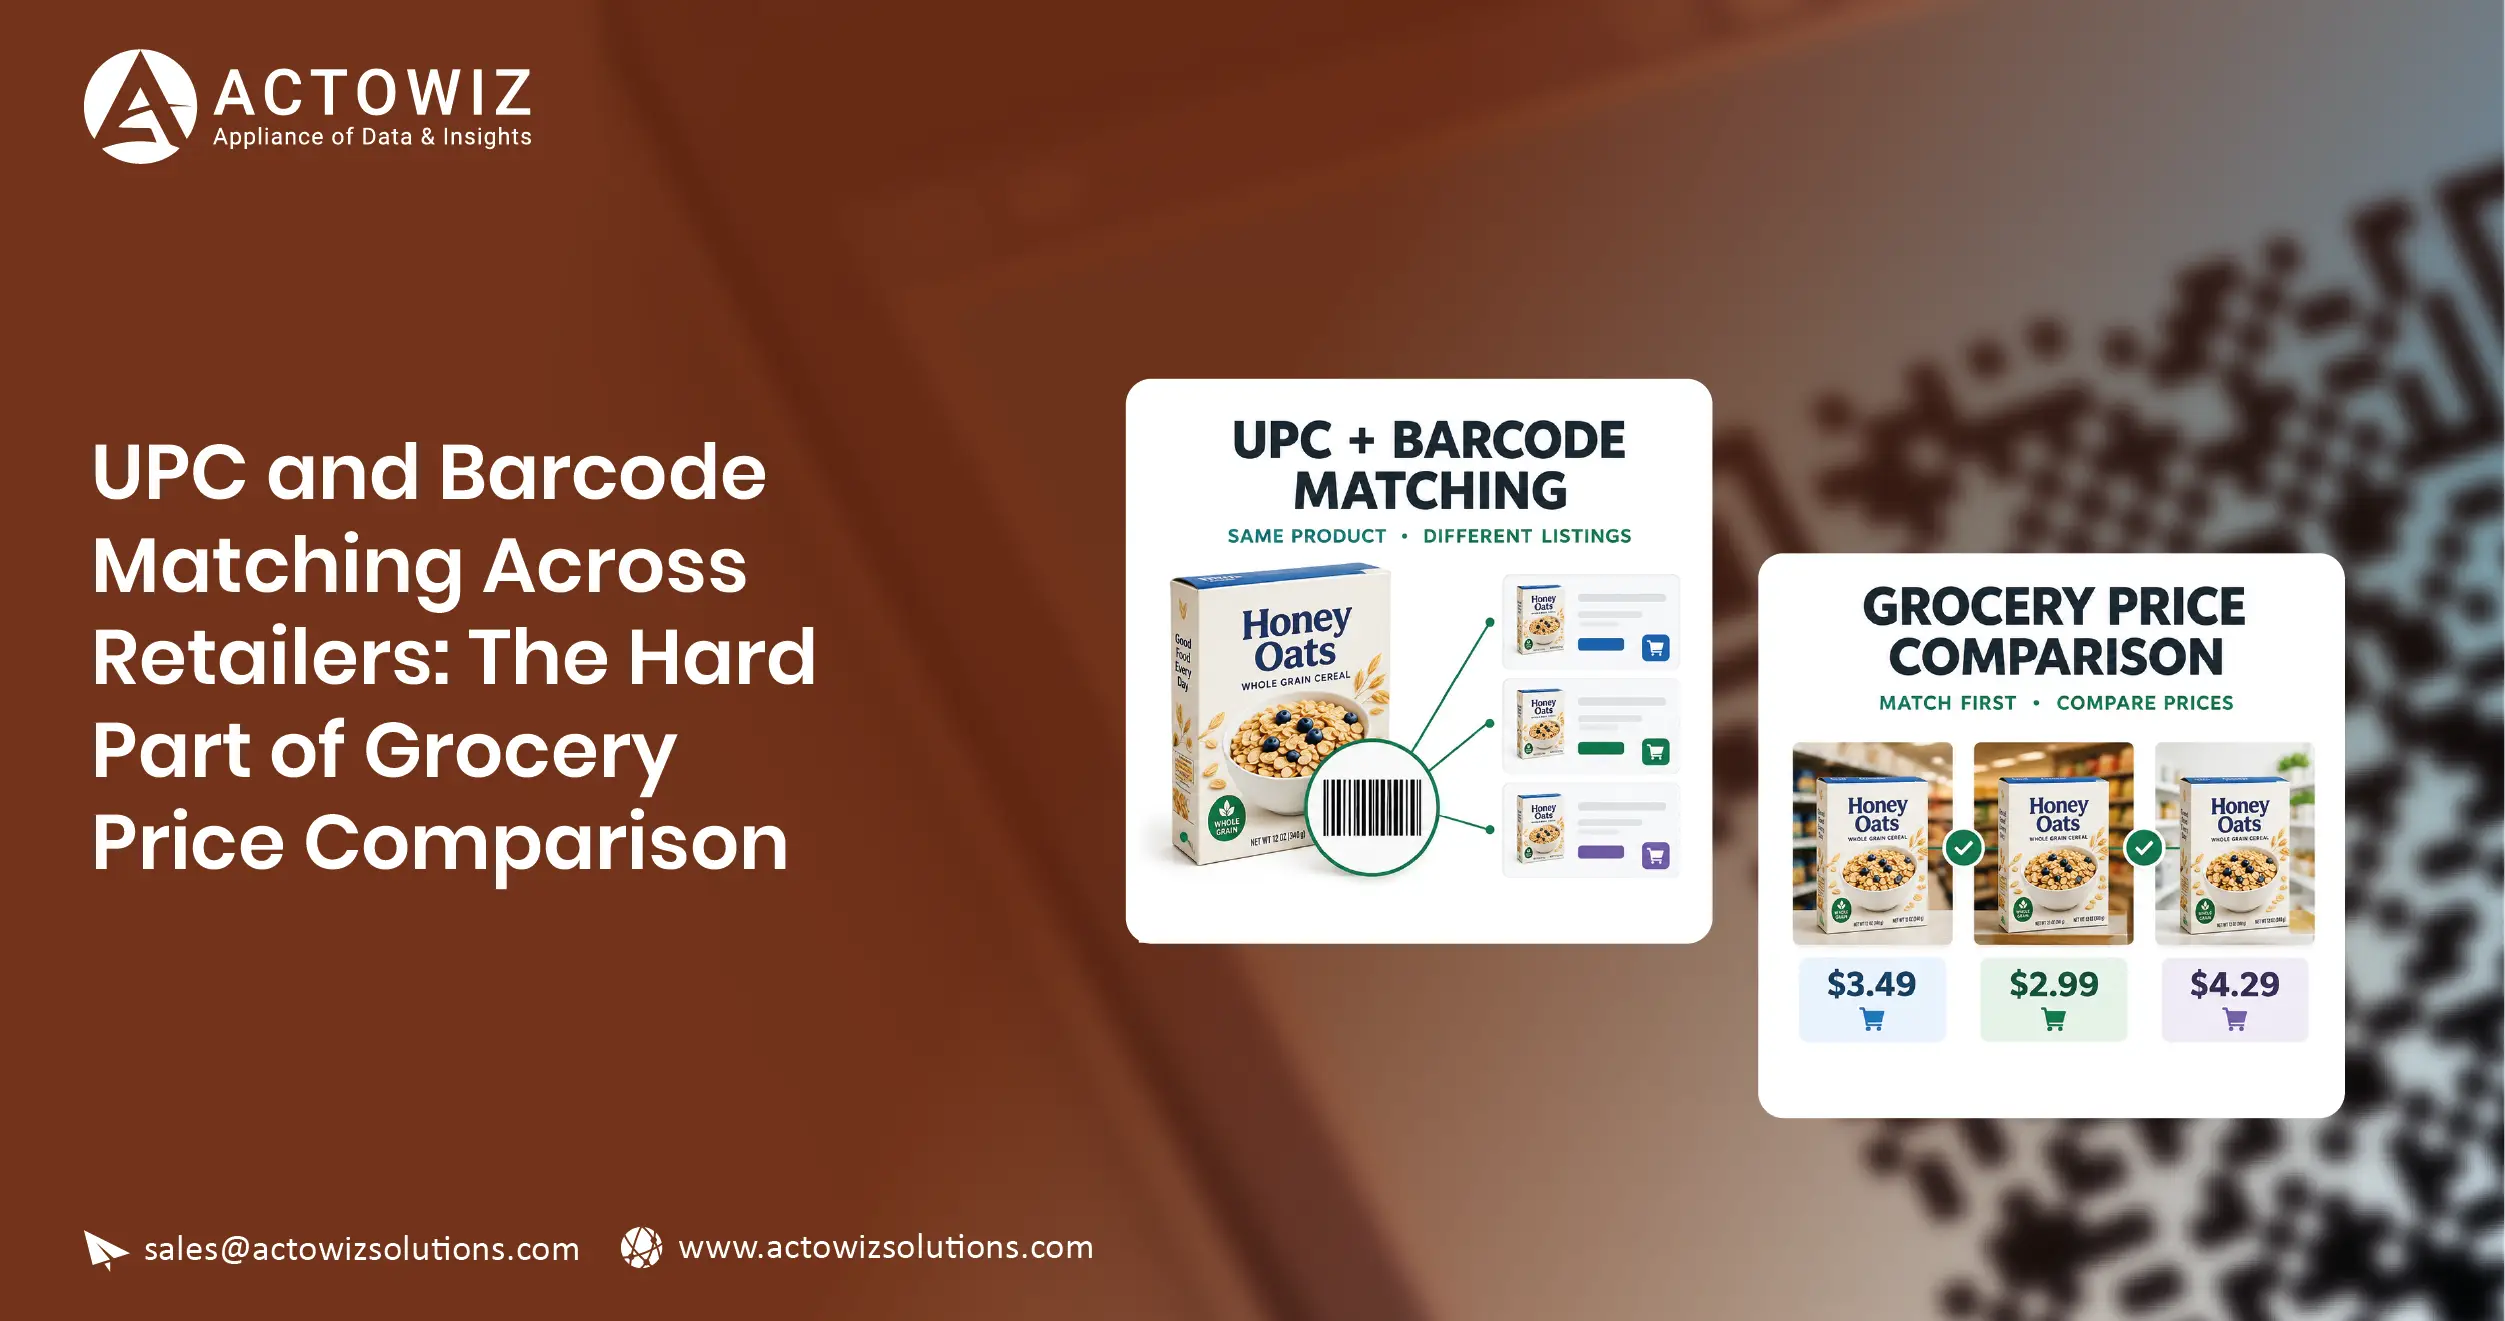
Collecting grocery prices is a solved engineering problem. Knowing that Retailer A's item and Retailer B's item are the same product is not.

Every price comparison, every price index, every "we are 3% above the market" conclusion rests on the matching layer. And matching fails quietly. A wrong match does not throw an error. It produces a number that looks exactly like a right number, and it flows into a dashboard where someone makes a pricing decision with it.

This is the part to get right before anything downstream is worth building.

Why barcode matching is necessary but not sufficient

GTIN — UPC in North America, EAN in Europe and Australia — identifies a specific trade item. When both retailers publish it, matching is trivial and correct.

They frequently do not. Five structural reasons:

  • Private label has no shared barcode. Great Value, Good & Gather, Tesco own-label, Coles brand, Aldi's exclusive range. Each retailer assigns its own code. There is no shared identifier because there is no shared product. Private label is also where price competition is fiercest, so this gap sits precisely where you most need a match.
  • Multipacks get their own codes. A single can, a six-pack, and a twelve-pack each carry a distinct GTIN. Matching on barcode alone treats them as unrelated. Comparing a six-pack price against a twelve-pack price without normalising to unit basis produces a meaningless comparison.
  • Retailers assign internal IDs and do not always publish the barcode. Walmart's item identifier, Target's TCIN, and retailer-specific SKUs are the operational keys. GTIN may be present, absent, or wrong.
  • GTIN referents drift. Reformulations, repackaging, and supplier changes mean two observations sharing a GTIN months apart may not be the same product.
  • Weighted and loose items have no meaningful barcode. Fresh produce, deli, and bakery are priced by weight with store-assigned codes.

The realistic position: barcode gives a correct match on a portion of the catalogue, concentrated in packaged national brands. The rest needs a constructed match.

[DATA: share of tracked lines with a usable published GTIN, by retailer]

The match hierarchy

Run matching as an ordered cascade. Each tier is cheaper and more reliable than the next, so exhaust each before descending.

Match Tiers
Tier Method Typical precision Cost
1 Exact GTIN match Very high Trivial
2 Normalised brand + size + variant High Low, rules-based
3 Attribute similarity / embedding match Medium Moderate, needs tuning
4 Human review queue Highest Expensive per item
5 Equivalence set (private label) Definitional Expensive, but durable

Tier 1 — exact GTIN. Both sides publish a GTIN and they agree. Validate the check digit and normalise length. Reject codes that fail validation rather than trusting them; a malformed GTIN is a data error, not a weak signal.

Tier 2 — normalised attributes. The workhorse. Requires a brand dictionary, a size parser, and a variant vocabulary. Covers most branded lines where GTIN is missing on one side.

Tier 3 — similarity matching. Vector similarity over product titles and attributes, or a trained classifier over feature pairs. Good at surfacing candidates, poor at final adjudication. Use it to generate ranked candidates, then gate on attribute agreement — never accept a similarity score alone, because a model will confidently pair a 500g product with a 1kg one.

Tier 4 — human review. For everything the cascade cannot resolve above threshold. Not a failure mode; a designed component.

Tier 5 — equivalence sets. For private label, where no true match exists. You are defining comparability rather than discovering identity, and that definition must be written down.

Record the tier on every match. match_method and match_confidence must travel with the matched pair forever, so downstream consumers can filter.

Size and unit normalisation rules

Most matching failures trace back to size parsing. Sizes are written inconsistently, and the variations are endless.

Rules that carry the most weight:

Size Normalisation Rules
Rule Example Canonical result
Parse value and UoM separately "500g" value 500, uom g
Convert to canonical base 500 g 0.5 kg
Mass, volume and count are distinct families 500g vs 500ml Never interconvert
Extract pack count separately "6 x 330ml" pack 6, unit 330 ml, total 1.98 L
Handle fluid vs dry ounces "16 fl oz" vs "16 oz" Volume vs mass — different families
Normalise imperial volume by region US fl oz vs UK fl oz Differ; resolve by market
Parse ranges and approximations "approx 1.2kg" value 1.2, flag is_approximate
Handle count-only items "12 ct" count 12, no mass or volume
Handle drained vs total weight "400g (240g drained)" Capture both; match on the stated primary
Preserve the raw string Always size_raw never discarded

Two absolute rules. Never interconvert mass and volume — a 500g jar and a 500ml bottle are not the same size, and water-density assumptions are how a honey comparison goes wrong. And never discard the raw size string, because size_raw is the evidence when a match is challenged, and parsers improve.

Derive a total_quantity in canonical units — pack_count x unit_size — and match on that plus pack_count. Two products with the same total quantity but different pack counts are different products for shelf comparison, though they may be comparable on unit price.

Multipacks and case packs

The cleanest model represents a product as a base item plus a pack configuration.

Pack Configuration Model
Field Example
base_item_key Cola, 330 ml can
pack_count 24
unit_size_value, unit_size_uom 330, ml
total_quantity_value, total_quantity_uom 7.92, l
pack_type single / multipack / case / variety_pack
gtin The multipack's own code

This supports three comparison modes cleanly:

  • Like-for-like — same base_item_key and same pack_count. The only fair shelf-price comparison.
  • Unit basis — same base_item_key, any pack count, compared on price per canonical unit. Fair economic comparison, but note that a shopper buying one unit cannot access the 24-pack rate.
  • Availability — whether a retailer offers a given pack configuration at all. A real competitive finding.

Variety packs need separate handling. A mixed twelve-pack has no single base_item_key. Model it as its own item with a composition list, and exclude it from like-for-like comparison against single-flavour packs.

Case packs sold in club or wholesale channels frequently carry a different GTIN and a different pack size from retail. Flag pack_type explicitly so club-channel prices do not silently undercut retail prices in a comparison that was never like-for-like.

Confidence scoring and auto-accept thresholds

Every match needs a score, and the score needs a defined meaning.

A workable composition:

Match Confidence Signals
Signal Weight direction
GTIN agreement Decisive when present and valid
Brand agreement after normalisation Strong
Total quantity agreement within tolerance Strong; disagreement is near-fatal
Pack count agreement Strong for like-for-like
Variant agreement (flavour, fat content, form) Strong
Title similarity Weak on its own
Category agreement Weak but useful as a veto
Image similarity Supporting signal

Then define three bands, and set them from measured outcomes rather than intuition:

Confidence Bands
Band Action
High Auto-accept, sampled audit
Medium Review queue, prioritised by commercial impact
Low Reject, or hold as an unmatched candidate

The threshold should be calibrated against a hand-labelled gold set drawn from your own categories. Two metrics matter, and they trade off:

  • Precision — of accepted matches, how many are correct. This is what protects your numbers.
  • Recall — of true matches, how many were found. This is what protects your coverage.

For pricing decisions, favour precision. A missing match is a visible gap someone can act on. A wrong match is an invisible error that corrupts a decision. Publish both numbers alongside any matched dataset.

[DATA: precision and recall by match tier against a hand-labelled gold set] [DATA: auto-accept rate and audit-detected error rate at the chosen threshold]

The human review loop

Review is a permanent operational function, not a one-time cleanup.

Review Loop Design
Component Design point
Queue prioritisation Rank by commercial impact — volume and price gap — not by arrival order
Reviewer interface Side-by-side images, titles, sizes, and the signals that drove the score
Decision options Accept, reject, accept-with-correction, escalate
Correction capture A reviewer fixing a size error should feed the parser, not just the row
Gold set growth Every decision becomes labelled training data
Audit sampling Sample auto-accepted matches continuously
Re-review triggers Reformulation, size change, new pack configuration

The feedback path is what makes review economical. A reviewer who corrects "1L" being parsed as 1 gram has fixed one row. A reviewer whose correction updates the parser has fixed every future row. Instrument for the second.

Matches also decay. Products are reformulated, resized, and discontinued. Set a revalidation cadence for high-impact matched pairs, and trigger re-review whenever a matched item's size, brand, or pack count changes.

How a bad match corrupts everything downstream

Follow one wrong match through a pipeline.

A 1.75-litre bottle is matched to a 2-litre bottle. Both are the same brand and flavour. Title similarity is high. Size parsing missed the difference.

Downstream Corruption Chain
Stage Effect
Price row Two prices joined as the same product
Price index Retailer appears cheaper than it is
Gap report A false price gap appears
Repricing rule Triggers a price cut that was never needed
Margin Real margin lost on real volume
Share of shelf Distorted, because item counts are wrong
Trust When someone spot-checks a shelf, the entire dataset is doubted

The last row is the expensive one. One demonstrable bad match invites scrutiny of every number, and a dataset nobody trusts has no value regardless of how much of it is correct.

This is why match provenance is not optional. Every matched pair should carry method, confidence, reviewer if applicable, and decision date. When a number is challenged, you should be able to show how the match was made in one query.

Frequently asked questions

Is UPC matching enough to compare prices across retailers?

No. Private label carries no shared barcode, multipacks have their own codes, and many retailers publish only internal IDs. Barcode matching resolves a portion of the catalogue — mainly packaged national brands — and the remainder needs normalised attribute matching plus human review.

How do you compare a six-pack against a twelve-pack?

Model the product as a base item plus pack configuration, and derive total quantity in canonical units. Compare like-for-like only within the same pack count; compare across pack counts on price per unit, labelled clearly as a unit-basis comparison.

What confidence threshold should auto-accept a match?

One calibrated against a hand-labelled gold set from your own categories, favouring precision over recall. A missing match is a visible gap; a wrong match is an invisible error that corrupts every downstream price number. Report precision and recall, not just match rate.

Conclusion

Actowiz Solutions runs grocery matching as an audited cascade — validated GTIN, normalised brand, size, variant and pack attributes, similarity candidates gated on attribute agreement, and a prioritised human review queue.

Match method, confidence, and reviewer decision travel with every matched pair, and precision and recall are reported against a client-supplied reference set rather than asserted.

You can also reach us for all your mobile app scraping, data collection, web scraping , and instant data scraper service requirements!

Social Proof That Converts

Trusted by Global Leaders Across Q-Commerce, Travel, Retail, and FoodTech

Our web scraping expertise is relied on by 4,000+ global enterprises including Zomato, Tata Consumer, Subway, and Expedia — helping them turn web data into growth.

4,000+ Enterprises Worldwide
50+ Countries Served
20+ Industries
Join 4,000+ companies growing with Actowiz →
Real Results from Real Clients

Hear It Directly from Our Clients

Watch how businesses like yours are using Actowiz data to drive growth.

▶
1 min
★★★★★
"Actowiz Solutions offered exceptional support with transparency and guidance throughout. Anna and Saga made the process easy for a non-technical user like me. Great service, fair pricing!"
TG
Thomas Galido
Co-Founder / Head of Product at Upright Data Inc.
▶
2 min
★★★★★
"Actowiz delivered impeccable results for our company. Their team ensured data accuracy and on-time delivery. The competitive intelligence completely transformed our pricing strategy."
II
Iulen Ibanez
CEO / Datacy.es
▶
1:30
★★★★★
"What impressed me most was the speed — we went from requirement to production data in under 48 hours. The API integration was seamless and the support team is always responsive."
FC
Febbin Chacko
-Fin, Small Business Owner
icons 4.8/5 Average Rating
icons 50+ Video Testimonials
icons 92% Client Retention
icons 50+ Countries Served

Join 4,000+ Companies Growing with Actowiz

From Zomato to Expedia — see why global leaders trust us with their data.

Why Global Leaders Trust Actowiz

Backed by automation, data volume, and enterprise-grade scale — we help businesses from startups to Fortune 500s extract competitive insights across the USA, UK, UAE, and beyond.

icons
7+
Years of Experience
Proven track record delivering enterprise-grade web scraping and data intelligence solutions.
icons
4,000+
Projects Delivered
Serving startups to Fortune 500 companies across 50+ countries worldwide.
icons
200+
In-House Experts
Dedicated engineers across scrapers, AI/ML models, APIs, and data quality assurance.
icons
9.2M
Automated Workflows
Running weekly across eCommerce, Quick Commerce, Travel, Real Estate, and Food industries.
icons
270+ TB
Data Transferred
Real-time and batch data scraping at massive scale, across industries globally.
icons
380M+
Pages Crawled Weekly
Scaled infrastructure for comprehensive global data coverage with 99% accuracy.

AI Solutions Engineered
for Your Needs

→
LLM-Powered Attribute Extraction: High-precision product matching using large language models for accurate data classification.
→
Advanced Computer Vision: Fine-grained object detection for precise product classification using text and image embeddings.
→
GPT-Based Analytics Layer: Natural language query-based reporting and visualization for business intelligence.
→
Human-in-the-Loop AI: Continuous feedback loop to improve AI model accuracy over time.
icons Product Matching icons Attribute Tagging icons Content Optimization icons Sentiment Analysis icons Prompt-Based Reporting

Connect the Dots Across
Your Retail Ecosystem

We partner with agencies, system integrators, and technology platforms to deliver end-to-end solutions across the retail and digital shelf ecosystem.

icons
Analytics Services
icons
Ad Tech
icons
Price Optimization
icons
Business Consulting
icons
System Integration
icons
Market Research
Become a Partner →

Popular Datasets — Ready to Download

Browse All Datasets →
icons
Amazon
eCommerce
Free 100 rows
icons
Zillow
Real Estate
Free 100 rows
icons
DoorDash
Food Delivery
Free 100 rows
icons
Walmart
Retail
Free 100 rows
icons
Booking.com
Travel
Free 100 rows
icons
Indeed
Jobs
Free 100 rows

Latest Insights & Resources

View All Resources →
thumb
Blog

Tour Operator Data Scraping: Prices, Availability and Inventory Across 10+ Sites (2026 Guide)

Tour operator data scraping across 10+ sites: prices, availability calendars and inventory from Viator, GetYourGuide, Klook and more.

thumb
Case Study

How Sensitive Skin Skincare Product Data API Helps Brands Track Cleansers, Serums, Moisturizers, and Sunscreens

Sensitive Skin Skincare Product Data API helps brands track cleansers, serums, moisturizers, and sunscreens with structured product data.

thumb
Report

Quick Commerce Availability Index Q4 2026: Market Data Report for Top 50 FMCG Brands Across 10 Indian Cities

Quick commerce availability index for Q4 2026: OOS rate, listing coverage and price index for 50 FMCG brands across 10 Indian cities.

Start Where It Makes Sense for You

Whether you're a startup or a Fortune 500 — we have the right plan for your data needs.

icons
Enterprise
Book a Strategy Call
Custom solutions, dedicated support, volume pricing for large-scale needs.
icons
Growing Brand
Get Free Sample Data
Try before you buy — 500 rows of real data, delivered in 2 hours. No strings.
icons
Just Exploring
View Plans & Pricing
Transparent plans from $500/mo. Find the right fit for your budget and scale.
Get in Touch
Let's Talk About
Your Data Needs
Tell us what data you need — we'll scope it for free and share a sample within hours.
  • icons
    Free Sample in 2 HoursShare your requirement, get 500 rows of real data — no commitment.
  • icons
    Plans from $500/monthFlexible pricing for startups, growing brands, and enterprises.
  • icons
    US-Based SupportOffices in New York & California. Aligned with your timezone.
  • icons
    ISO 9001 & 27001 CertifiedEnterprise-grade security and quality standards.
Request Free Sample Data
Fill the form below — our team will reach out within 2 hours.
+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours

Request Free Sample Data

Our team will reach out within 2 hours with 500 rows of real data — no credit card required.

+1 ▼
✓ Free 500-row sample · No credit card · Response within 2 hours