-
Core services
Enterprise Data Extraction
Scalable web, app and AI-powered collection across 40+ countries.
All services →58Services40+Countries⚙ How we deliverEnterprise Web Crawling Managed Data API Live Crawler HOT AI-Powered Scraping HOT Custom Data Extraction Mobile App Scraping AI Training Data NEW📌 Start hereAll 58 services — overview How pricing works Free 24-hour sample Talk to an engineer📊 By data typePricing & Product Data #1 Stock & Availability NEW Catalog & Assortment NEW Retail Search & Share of Shelf NEW Reviews & Ratings Data Promotions & Offers Content & Media Seller & Vendor Data Location & Geo Data SERP & AI Search HOT News Data Financial & Market Data Lead & Contact Data ESG & Sustainability NEW Patents & IP NEWE-commerce & Retail #1 Quick Commerce HOT Grocery & FMCG Food Delivery Travel & Hospitality Real Estate & PropTech Fashion & Apparel Electronics & Appliances Healthcare & Pharma Insurance Automotive & EV Telecom & Broadband NEW Logistics & Freight NEW Jobs & Recruitment OTT & Entertainment NEW Social Media App Store & ASO Education & EdTech Agriculture & Commodities Wine, Spirits & Liquor Fuel & Energy Gaming & Sports Government & Tenders NEW By industry🏷 By platform🌐 By market
-
TRENDING
AI Dynamic Pricing
Repricing driven by competitor moves rather than a weekly review.
Explore →27Solutions5CategoriesPrice Monitoring AI Dynamic Pricing HOT Product Matching Smart Repricer Promo Tracking Cross-Border Pricing NEW Multi-Currency NEW Pricing & Promotions
MAP Violations Brand Protection Counterfeit Detection Price Intelligence AI HOT Data Intelligence
 Brand & Intelligence
Share of Search Content Audit & PDP Reviews & Ratings Retail Media Buy Box Monitoring Social Commerce HOT Live Commerce NEW Agentic Commerce NEW
 Digital Shelf & Search
Assortment Planning Competitive Benchmarking Product Availability Q-Commerce NEW
 AssortmentE-commerce Intelligence Hyperlocal Insights POI & Store Locator DTC Brand Analytics NEW
 For Retailers
Which solution fits?
Talk to Expert -
NEW 2026
GCC Quick Commerce
Talabat, Careem Quik and Noon Minutes across 18 GCC cities.
Launch Demo →Early accessUK Grocery Price Tracker
Tesco, Sainsbury's, Asda, Morrisons and Aldi, daily.
Get Early Access →11+DashboardsDailyUpdates By Industry
 E-Commerce Dashboard
 Flipkart Insights (Live) #1
 Grocery Intelligence
.svg) Grocery Price (U.S.)
.svg) Quick Commerce (India) HOT
 Food & Restaurant
 Fashion Intelligence
 Automotive
 Travel & Hospitality
 Real Estate
 Food Delivery Intelligence NEW
 OTT & Streaming NEW
 Fuel & EV Charging Price Tracker NEW
 By Use Case
 Pricing Intelligence
 Digital Shelf Analytics
 MAP Monitoring HOT
 Cross-Border Price Parity NEW
 Share of Search
 Review Sentiment
 Kitchen Market Gaps NEW
 Dynamic Pricing / AI Repricing NEW
 Promotions & Deals Alerts NEW
 B2B / POI & Lead Data NEW
 AI Search Visibility Dashboard NEW
 Baby Products on Quick Commerce NEW
 Hotel & Flight Rate Parity NEW
 By Region🇮🇳 India 🇺🇸 USA 🇦🇪 Middle East 🇬🇧 UK 🇦🇺 Australia 🌏 SE Asia 🇪🇺 Europe 🌎 LATAMIndia
 Flipkart Real-Time Insights
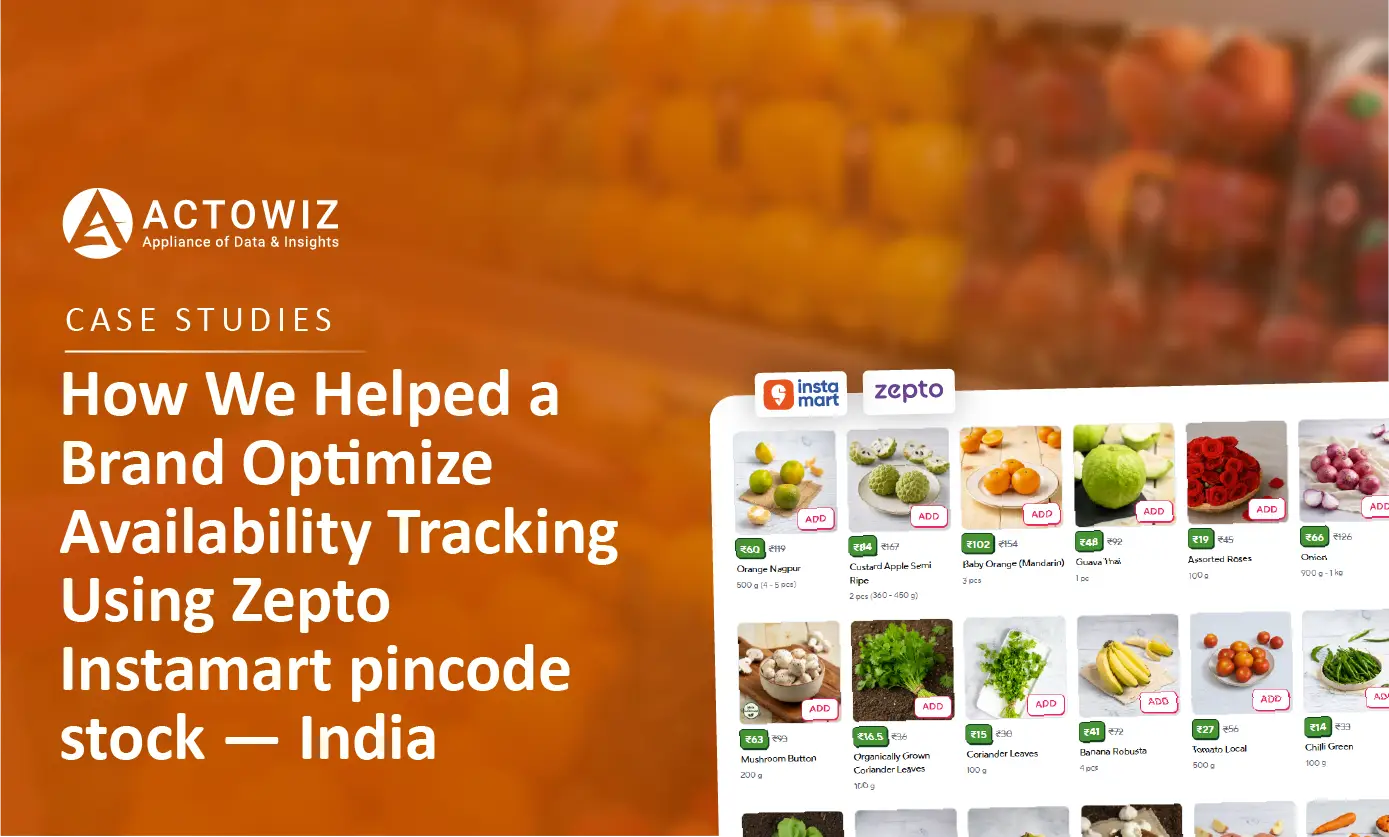
 Quick Commerce — Zepto · Blinkit
 Pincode Price Tracker
Middle East
 GCC Q-Commerce — Talabat · Noon NEW
UK & Australia
 UK Grocery — Tesco, Sainsbury's, Asda
 AU Grocery — Coles & Woolworths NEW
-
Coverage
What we can collect
Sources we already run pipelines against. Download a real sample from any of them.
Browse coverage →30Sources24hSamples🇺🇸 United StatesAmazon #1 Walmart Target NEW Shopify stores HOT TikTok Shop HOT Costco & Best Buy NEW Etsy / Temu NEW DoorDash / Instacart NEW🇬🇧 UK & EuropeTesco / Sainsbury's NEW Ocado / Deliveroo NEW Zalando / Otto NEW Cdiscount / Carrefour NEW Allegro NEW Booking / Airbnb🇮🇳 India & Middle EastFlipkart / Meesho NEW Blinkit / Zepto Zomato / Swiggy BigBasket / JioMart NEW Myntra / Nykaa NEW Noon / Amazon.ae NEW Talabat / Careem NEW🌍 GlobalShopee & Lazada NEW Mercado Libre NEW Rakuten / Coupang NEW eBay AU / Woolworths NEW Netflix / Prime Video Google Maps / Yelp AI Training HOT Cross-Border NEW -
28Tools2SDKsAmazon (Global) #1 Walmart Scraper Target Scraper NEW Shopify Scraper HOT eBay Scraper Flipkart Scraper Shopee Scraper NEW Noon Scraper NEW Mercado Libre NEW Google Maps HOT
 Marketplace Scrapers
Amazon API TikTok Shop API HOT Uber Eats API Airbnb API Zepto / Blinkit API Instacart API NEW Talabat API NEW
 Developer APIsWeb Extract API Reviews API SERP API Pricing Webhook NEW
 Universal APIsStreaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
 Delivery & SDKs
Need it managed instead?
Fixed monthly retainer, named engineer, no per-request metering.
Managed Data API → -
Blog Case Studies HOT Whitepapers Research & Reports Competitor Template NEW
 Knowledge Center
Digital Shelf Playbook MAP Compliance Guide Pricing Intel Guide Scraping Compliance TikTok Shop Guide NEW Cross-Border Guide NEW
 Guides & Playbooks
🎉 Seasonal & event tracking NEWBlack Friday pricing report Festive season, India Ramadan, GCC grocery All seasonal reportsSample Datasets HOT ROI Calculator NEW API Postman Collection Demo Dashboards Free API Playground NEW Press Kit
 Downloads & Tools
Trust Center About Us FAQs Careers
 Trust & CompanyRetail shelf research NEWRetail shelf research
- Contact US
Enterprise Data Extraction
Scalable web, app and AI-powered collection across 40+ countries.
All 58 services → By industryAI Dynamic Pricing
Repricing driven by competitor moves rather than a weekly review.
Explore → Pricing & Promotions
Brand & Intelligence
Digital Shelf & Search
Assortment For RetailersWhich solution fits?
Talk to ExpertWhat we can collect
Sources we already run pipelines against. Download a real sample from any of them.
Browse coverage →GCC Quick Commerce
Talabat, Careem Quik and Noon Minutes across 18 GCC cities.
Launch Demo →UK Grocery Price Tracker
Tesco, Sainsbury's, Asda, Morrisons and Aldi, daily.
Get Early Access → By Industry
E-Commerce Dashboard
Flipkart Insights (Live) #1
Grocery Intelligence
Grocery Price (U.S.)
Quick Commerce (India) HOT
Food & Restaurant
Fashion Intelligence
Automotive
Travel & Hospitality
Real Estate
Food Delivery Intelligence NEW
OTT & Streaming NEW
Fuel & EV Charging Price Tracker NEW
By Use Case
Pricing Intelligence
Digital Shelf Analytics
MAP Monitoring HOT
Cross-Border Price Parity NEW
Share of Search
Review Sentiment
Kitchen Market Gaps NEW
Dynamic Pricing / AI Repricing NEW
Promotions & Deals Alerts NEW
B2B / POI & Lead Data NEW
AI Search Visibility Dashboard NEW
Baby Products on Quick Commerce NEW
Hotel & Flight Rate Parity NEW
By Region Flipkart Real-Time Insights
Quick Commerce — Zepto · Blinkit
Pincode Price Tracker
GCC Q-Commerce — Talabat · Noon NEW
UK Grocery — Tesco, Sainsbury's, Asda
AU Grocery — Coles & Woolworths NEW
Marketplace Scrapers
Developer APIs Universal APIs Delivery & SDKsNeed it managed instead?
Fixed monthly retainer, named engineer, no per-request metering.
Managed Data API → Knowledge Center
Guides & Playbooks
Downloads & Tools
Trust & Company


 4.8/5 Average Rating
 50+ Video Testimonials
 92% Client Retention
 50+ Countries Served