.webp)
Why Tesco data matters more than any other UK grocery source
Tesco is the largest grocery retailer in the UK by market share — around 28.7%, per Kantar Worldpanel's most recently published 12-week grocery share reading. For anyone monitoring UK food and household pricing, it functions as the reference point. When a CPG brand wants to know whether its recommended price is holding, when a challenger grocer benchmarks its basket, when a price comparison site builds a grocery vertical, or when an analyst tracks food inflation at SKU level, Tesco is the first dataset they need and the one everything else is compared against.
There is a second reason Tesco has become the most interesting UK grocery dataset: Clubcard pricing. Tesco's loyalty-linked pricing means a large share of the catalogue carries two prices simultaneously — the standard shelf price and a lower Clubcard price available only to loyalty members. Any price monitoring system that captures only one of these numbers produces misleading output. A brand tracking its promotional depth, or a comparison engine ranking baskets, gets the answer wrong if it records £3.50 when the effective price for most shoppers is £2.50.
Loyalty pricing has also drawn regulatory attention in the UK, with the Competition and Markets Authority reviewing how loyalty prices are presented to shoppers in a formal review launched in January 2024, which reported its findings on 27 November 2024 and concluded that the large majority of loyalty prices examined — Clubcard prices included — offered genuine savings, while cautioning that loyalty prices are not always the cheapest option available. That scrutiny has made accurate, timestamped, auditable loyalty price data commercially valuable to brands, retailers and researchers alike.
What data can you extract from Tesco?
Tesco's public grocery pages expose a rich structured set of attributes. Here is the field schema we work with on production feeds, grouped by category.
Core product identity
| Field |
Description |
Example |
| product_id |
Tesco's internal product identifier (TPNB/TPNC) |
301234567 |
| product_url |
Canonical product page URL |
https://www.tesco.com/groceries/en-GB/products/301234567 |
| product_name |
Full product title as displayed |
Tesco British Semi Skimmed Milk 2.272L, 4 Pints |
| brand |
Brand name, parsed or from structured data |
Tesco |
| pack_size |
Size/weight/volume as listed |
2.272L |
| gtin_ean |
Barcode identifier, where published |
05018374000000 |
| category_path |
Full breadcrumb hierarchy |
Fresh Food > Milk & Butter > Fresh Milk |
| image_urls |
Array of product image URLs |
["https://digitalcontent.api.tesco.com/..."] |
Pricing fields — the part that matters
| Field |
Description |
Example |
| price |
Standard shelf price |
1.75 |
| currency |
ISO currency code |
GBP |
| unit_price |
Price per standard unit |
0.77 |
| unit_of_measure |
Basis for unit price |
per litre |
| was_price |
Previous price where a reduction is shown |
2.10 |
| clubcard_price |
Loyalty-linked price where offered |
1.50 |
| clubcard_price_valid_until |
End date of the loyalty offer |
2026-03-17 |
| promo_type |
Nature of the offer |
clubcard_price / multibuy / price_drop |
| promo_text |
Raw offer text as displayed |
Clubcard Price £1.50 Any 2 for £3 |
| savings_vs_standard |
Derived field — standard minus Clubcard |
0.25 |
Availability and context
| Field |
Description |
Example |
| availability_status |
Stock state at time of capture |
in_stock / out_of_stock / limited |
| delivery_postcode |
Postcode used for this capture |
SW1A 1AA |
| store_id |
Store context where applicable |
3061 |
| rating_average |
Average customer rating |
4.5 |
| review_count |
Number of reviews |
1,284 |
| captured_at |
UTC timestamp of the capture |
2026-03-04T06:12:44Z |
Content and compliance attributes
For brands doing digital shelf work, the descriptive content is as important as the price: product description, ingredients, allergen statements, nutritional panel per 100g, storage instructions, country of origin, and dietary flags (vegan, gluten free, organic). These fields drive content compliance scoring — checking whether your product listing on Tesco actually matches the content you supplied.
The three things that break Tesco scrapers
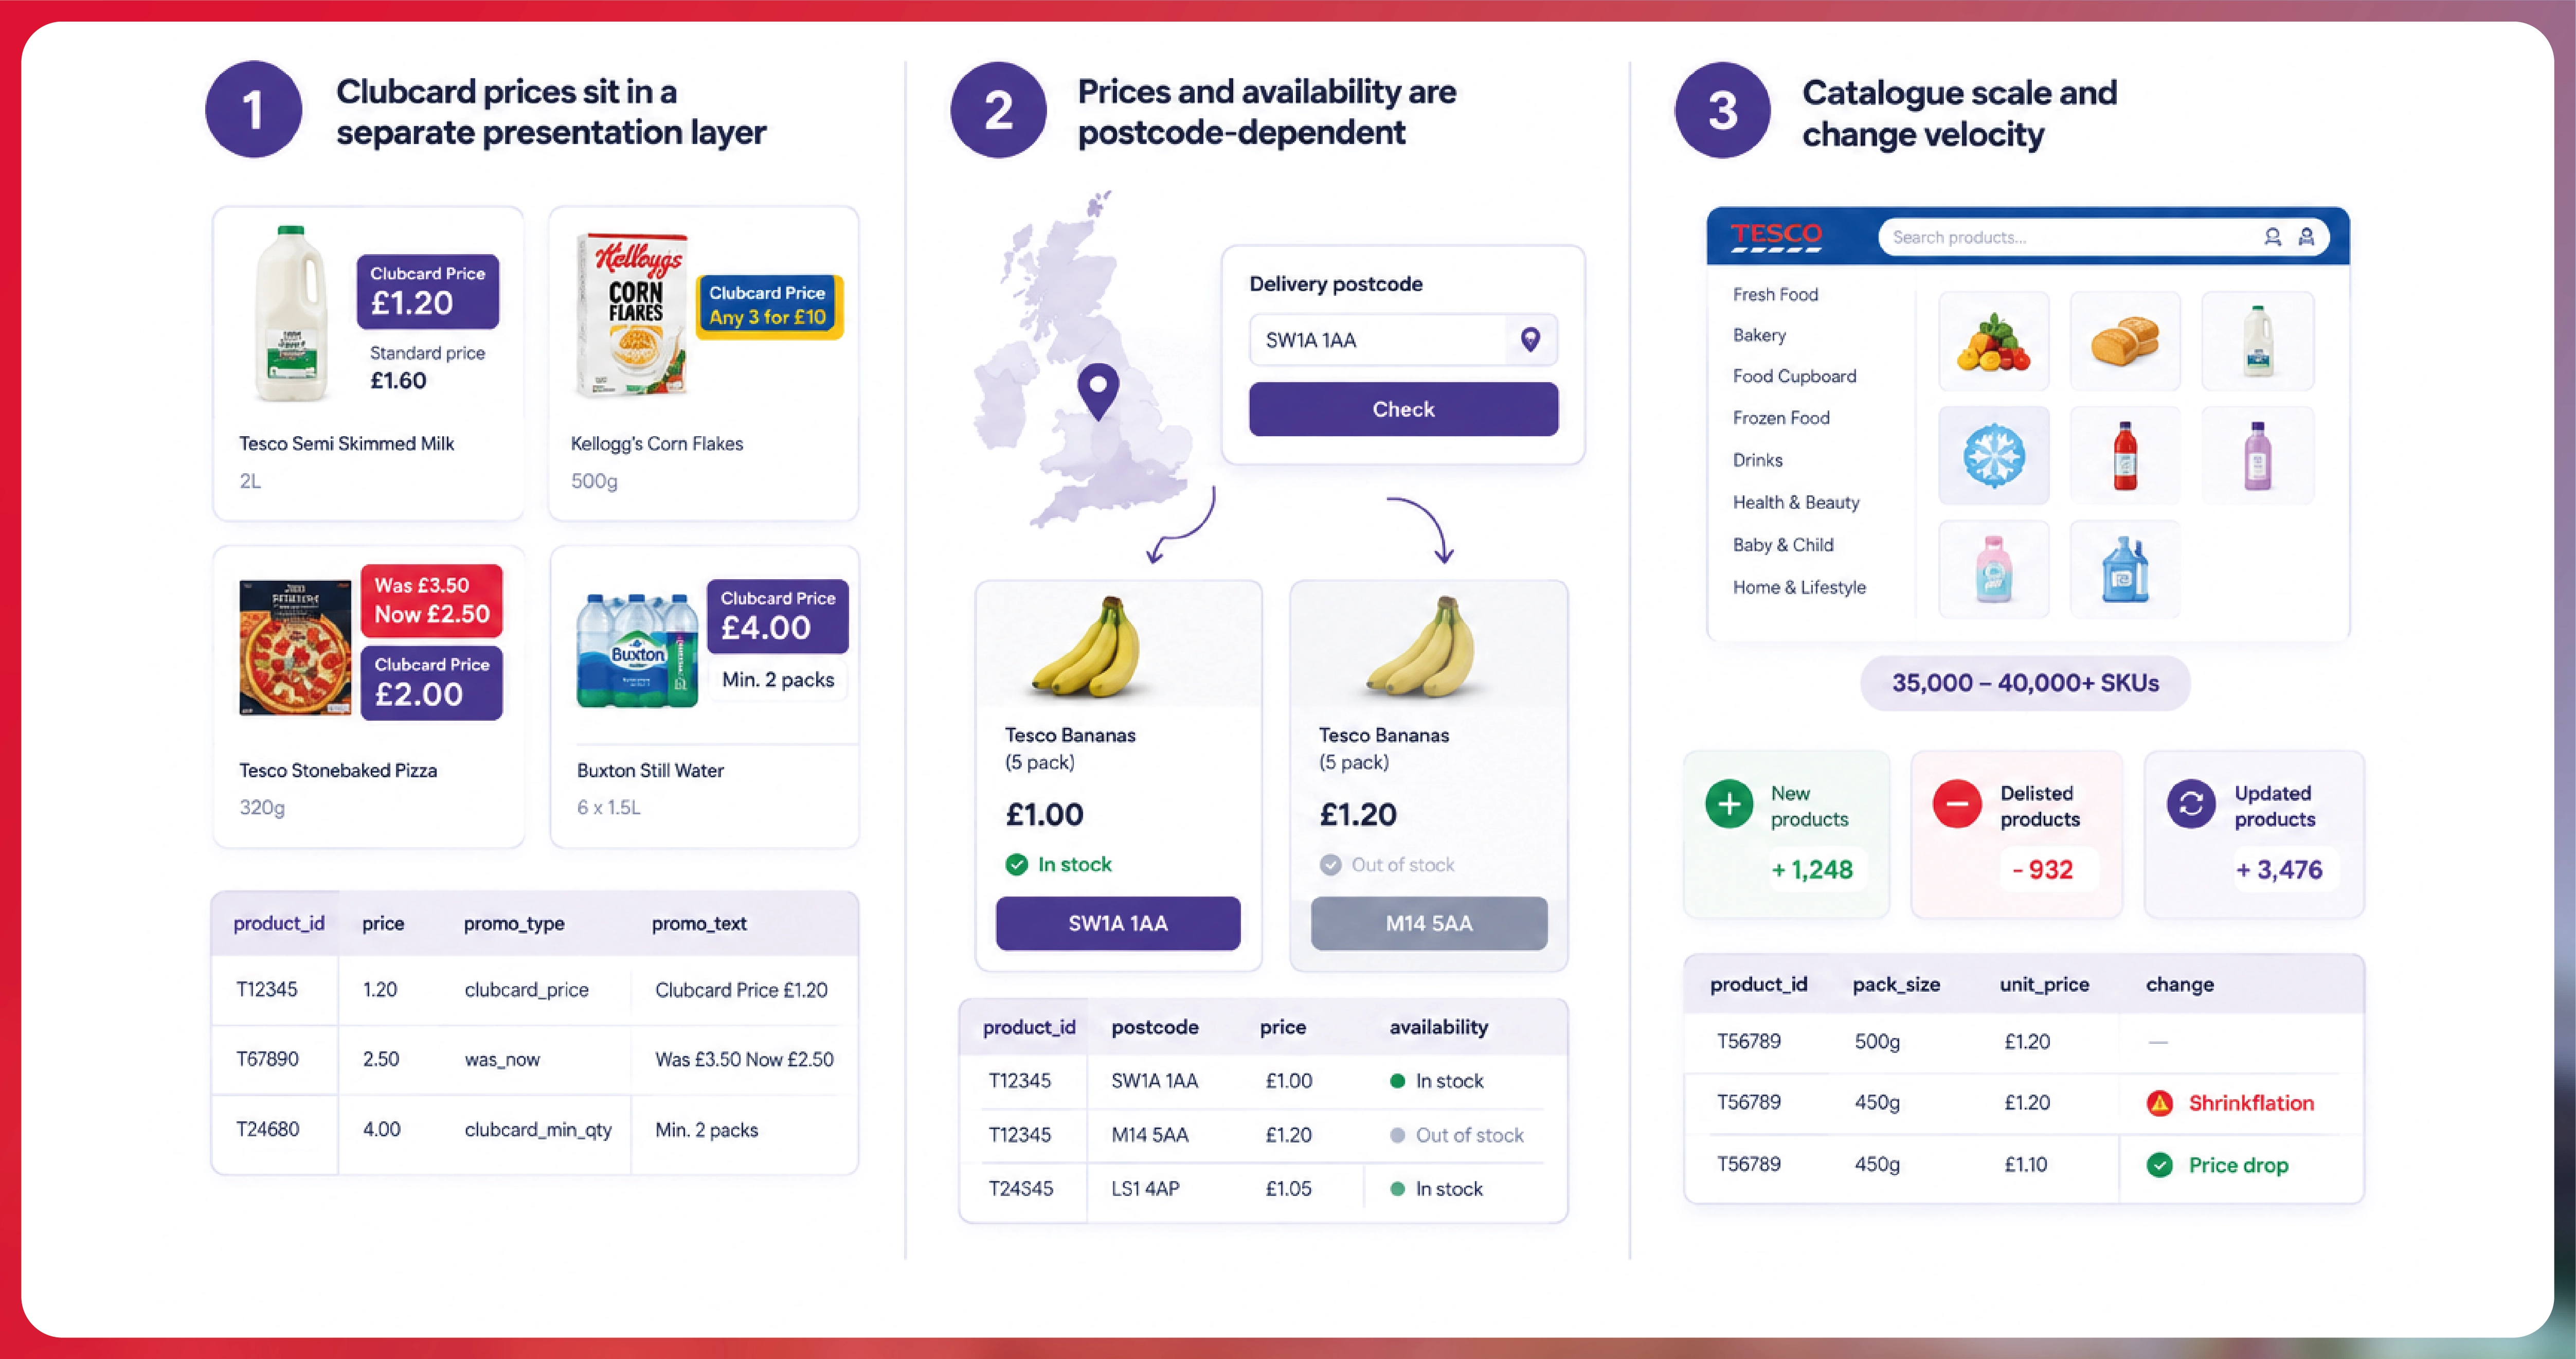
Most teams can pull one Tesco product page in an afternoon. Pulling the whole catalogue, accurately, every day for two years is a completely different engineering problem. These are the three failure modes we see most often.
1. Clubcard prices sit in a separate presentation layer
The standard price and the Clubcard price are not a single field with a discount applied. They are presented as distinct elements, and the way they appear varies by offer type. A product might show a simple Clubcard price. It might show a Clubcard multibuy ("Clubcard Price Any 3 for £10"). It might show a Clubcard price and a standard was/now reduction at the same time. It might show a Clubcard price that only applies above a minimum quantity.
A naive parser that grabs "the lowest price on the page" will conflate all of these. The correct approach is to capture the full offer object — price, price type, qualifying condition, and validity window — rather than flattening everything into one number. When we model this, promo_type and promo_text are treated as first-class fields, not afterthoughts, because they are what lets a downstream analyst reconstruct what a shopper actually paid.
2. Prices and availability are postcode-dependent
This is the single biggest cause of bad UK grocery datasets, and it catches almost every in-house team.
Tesco grocery pricing and availability are resolved in the context of a delivery location. Change the postcode and you can change availability, substitution behaviour, and in some cases the offers surfaced. A dataset captured without a controlled, consistent postcode context is not reproducible — you cannot compare Tuesday's file to Wednesday's file and trust the delta, because you do not know whether the price changed or the location context changed.
The fix is architectural, not clever. Every capture must be pinned to an explicit, recorded location context, and that context must be stored as a field in the output. If you are tracking national pricing, you pick a reference postcode and hold it constant. If you are doing regional analysis, you run parallel captures across a defined postcode panel — for example one per UK region — and every row carries its delivery_postcode. Without this, your "price change" alerts will be full of false positives and your analysts will stop trusting the feed within a month.
3. Catalogue scale and change velocity
Tesco's online grocery catalogue runs to tens of thousands of active SKUs (trade press reporting puts the core Tesco.com grocery range at roughly 35,000–40,000 SKUs, separate from the several-hundred-thousand-SKU Tesco Marketplace of third-party, non-grocery goods), spread across a deep category tree. Products are added, delisted, renamed, repacked and recategorised continuously. Promotions turn over weekly.
The engineering consequence is that a full-catalogue refresh is a scheduling and reconciliation problem, not just a fetching problem. You need:
- Category-tree discovery that re-walks the hierarchy rather than relying on a static seed list, or you will silently miss new categories
- Delisting detection — a product that disappears is a data point, and it needs to be recorded as delisted rather than just vanishing from your file
- Change reconciliation — matching today's capture to yesterday's on a stable key, so you produce a clean change log instead of a full dump your analysts have to diff themselves
- Pack-size change detection — the shrinkflation signal, where the price holds but the pack size drops, which only surfaces if you are storing pack_size and unit_price historically
Sample dataset
Below is an illustrative record showing the output schema. This is a structural example to show field shape and types — the values are synthetic and do not represent live Tesco pricing. Request a live sample if you need real current data.
{
  "product_id": "301234567",
  "product_url": "https://www.tesco.com/groceries/en-GB/products/301234567",
  "product_name": "Example Brand Semi Skimmed Milk 2.272L, 4 Pints",
  "brand": "Example Brand",
  "pack_size": "2.272L",
  "gtin_ean": "05000000000000",
  "category_path": "Fresh Food > Milk & Butter > Fresh Milk",
  "price": 1.75,
  "currency": "GBP",
  "unit_price": 0.77,
  "unit_of_measure": "per litre",
  "was_price": null,
  "clubcard_price": 1.50,
  "clubcard_price_valid_until": "2026-03-17",
  "promo_type": "clubcard_price",
  "promo_text": "Clubcard Price £1.50",
  "savings_vs_standard": 0.25,
  "availability_status": "in_stock",
  "delivery_postcode": "SW1A 1AA",
  "rating_average": 4.5,
  "review_count": 1284,
  "image_urls": ["https://example-cdn/product-301234567.jpg"],
  "captured_at": "2026-03-04T06:12:44Z"
}
And the same data flattened to CSV, which is how most merchandising and category teams prefer to receive it:
| product_id |
product_name |
price |
clubcard_price |
promo_type |
unit_price |
availability |
postcode |
captured_at |
| 301234567 |
Semi Skimmed Milk 4 Pints |
1.75 |
1.50 |
clubcard_price |
0.77/L |
in_stock |
SW1A 1AA |
2026-03-04 |
| 301234568 |
Wholemeal Bread 800g |
1.40 |
— |
— |
0.18/100g |
in_stock |
SW1A 1AA |
2026-03-04 |
| 301234569 |
Salted Butter 250g |
2.35 |
1.95 |
clubcard_price |
0.94/100g |
out_of_stock |
SW1A 1AA |
2026-03-04 |
| 301234570 |
Cheddar 400g |
4.00 |
3.00 |
clubcard_multibuy |
1.00/100g |
in_stock |
SW1A 1AA |
2026-03-04 |
Note what the fourth row tells you that a single-price dataset would not: the effective price for a loyalty shopper is 25% below shelf, and it is conditional on a multibuy. A brand tracking promotional depth needs both halves of that.
Technical approach
Before anything else: check what you are allowed to fetch
Read https://www.tesco.com/robots.txt and honour it. Confine collection to publicly accessible pages — no logged-in areas, no account data, no personal data of any kind. If a path is disallowed, it is out of scope. This is not a formality; it is the boundary between a legitimate data operation and one that will cause your client legal problems.
Parsing structure over parsing markup
The most maintainable approach is to extract from structured data where it exists rather than from visual markup. Many retail pages publish Product schema in JSON-LD, which gives you name, brand, identifiers, images and price in a stable machine-readable form. Markup classes change with every front-end release; structured data changes far less often.
A simplified, polite fetch-and-parse pattern:
import json, time, requests
from bs4 import BeautifulSoup

HEADERS = {"User-Agent": "ActowizDataBot/1.0 (+https://actowizsolutions.com/bot)"}
DELAY_SECONDS = 3  # conservative; tune to stay well within courteous limits

def parse_product(url: str) -> dict | None:
    resp = requests.get(url, headers=HEADERS, timeout=30)
    resp.raise_for_status()
    soup = BeautifulSoup(resp.text, "html.parser")

    for tag in soup.find_all("script", type="application/ld+json"):
        try:
            data = json.loads(tag.string or "")
        except json.JSONDecodeError:
            continue
        if isinstance(data, dict) and data.get("@type") == "Product":
            offer = (data.get("offers") or {})
            return {
                "product_name": data.get("name"),
                "brand": (data.get("brand") or {}).get("name"),
                "gtin_ean": data.get("gtin13"),
                "price": offer.get("price"),
                "currency": offer.get("priceCurrency"),
                "availability_status": offer.get("availability"),
                "product_url": url,
            }
    return None

def crawl(urls: list[str]) -> list[dict]:
    out = []
    for u in urls:
        record = parse_product(u)
        if record:
            out.append(record)
        time.sleep(DELAY_SECONDS)   # rate limiting is not optional
    return out
Two things this snippet deliberately does: it identifies itself honestly in the user agent, and it rate-limits conservatively. Both matter. Aggressive collection degrades the retailer's service for real shoppers, and it is the fastest way to get a project shut down.
Two things it deliberately does not do: it does not attempt to evade any protective measure, and it does not handle the Clubcard layer. The loyalty price is typically rendered as part of the promotional presentation rather than the core offer object, which means you need page-specific parsing logic for it — and that logic is exactly the part that needs ongoing maintenance as the front end evolves.
The maintenance reality
That last point is where most in-house projects quietly die. The first version works. Then Tesco ships a front-end change, the promotional selectors break, and the feed starts returning null in the clubcard_price column — usually without failing loudly. Someone notices three weeks later when a category manager asks why the promo report looks empty.
Production-grade collection therefore needs a validation layer that runs on every batch:
- Null-rate monitoring — if clubcard_price populates on 18% of rows on Monday and 0.2% on Tuesday, that is a parser break, not a market event
- Price sanity bounds — flag any row where price moves more than a configured threshold, and any row where clubcard_price > price
- Volume checks — a category that returned 1,400 SKUs yesterday and 60 today has a discovery failure
- Schema validation — type and required-field checks before the file ships
- Historical continuity — match rate against the previous run; a sudden drop means your keys are breaking
Legal and compliance considerations in the UK
This section is not boilerplate. UK enterprise buyers will ask about it during procurement, and getting it wrong is the main commercial risk in this category.
- Public data only. Collect what any visitor can see without authenticating. No logged-in pages, no account areas, no basket data.
- No personal data. Product prices are not personal data. Customer reviews, however, may contain reviewer names or identifiable content — if you collect reviews, UK GDPR applies, and you need a lawful basis, a retention policy and a minimisation approach. The simplest compliant answer for most price monitoring use cases is to collect review counts and averages only, and not review text or author identity.
- Database rights. The UK retains a sui generis database right, separate from copyright, protecting substantial investment in obtaining, verifying or presenting the contents of a database. Extracting a substantial part of a protected database can infringe it. In practice this means the defensible position is factual price monitoring for analysis and comparison — not wholesale republication of a retailer's catalogue as your own product.
- Terms of service. Site terms are a contractual matter and their enforceability against non-account-holders varies. Treat them as a real consideration, not a technicality, and take legal advice for your specific use case.
- Rate limiting as a legal posture. Courteous collection volumes are not just good manners. Conduct that impairs a service is where scraping disputes tend to escalate. Conservative rates are a risk control.
- Not legal advice. Take advice from a qualified UK solicitor for your specific programme.
Who uses Tesco data, and for what
CPG and FMCG brands monitor their own SKUs for price compliance, promotional execution, share of shelf, content accuracy and availability. The recurring question is simple: is the offer we agreed with the retailer actually live, at the agreed price, on the agreed dates? Clubcard price capture is central here, because promotional depth is where most of the margin conversation happens.
Competing grocers benchmark baskets. A challenger tracking Tesco needs like-for-like matching across differently named products — which is a product matching problem as much as a collection problem, and it is why identifiers like EAN matter so much in the schema.
Price comparison and cashback platforms need broad catalogue coverage refreshed frequently enough that displayed prices are not stale.
Analysts, researchers and journalists track food inflation at SKU level, study shrinkflation by pairing pack_size with unit_price over time, or examine loyalty pricing structures. This is where historical depth matters more than refresh frequency — a two-year backfile is worth more than a real-time feed.
Retail media and agency teams measure search ranking and on-site visibility for client products.
Build in-house or buy a managed feed?
The honest version of this comparison.
Build in-house if you need one or two categories, refresh weekly, have a data engineer with spare capacity, and can tolerate gaps when the site changes. The initial build is genuinely not hard.
Buy a managed feed if you need full-catalogue coverage, daily or intraday refresh, multi-retailer comparison, a guaranteed schema, an SLA, and — most importantly — you do not want a category manager's Monday report to depend on whether someone noticed a parser break on Friday.
The cost comparison that usually decides it is not the build cost. It is the three-year maintenance cost: a scraping engineer's time to keep a multi-retailer UK grocery feed healthy is a recurring line item, and it does not shrink over time. Model it over three years, not three months, and include the cost of the reports that were wrong before anyone noticed.
How the data gets delivered
Collection is half the job. The other half is getting the data into the systems your team already uses, in a shape they can act on.
Formats
CSV and Excel for category and merchandising teams who work in spreadsheets. JSON or JSONL for engineering teams loading into a pipeline. Parquet where volume is high and query cost matters.
Destinations
Direct delivery to S3, Google Cloud Storage or Azure Blob; SFTP for teams with established file-drop workflows; direct load into BigQuery, Snowflake or Redshift; or a REST API endpoint for on-demand querying.
Delivery shape
Two patterns cover most needs. A full snapshot ships the entire catalogue state at each run — simple, easy to reason about, heavier to store. A change log ships only what moved since the last run, with the change type recorded (price_change, promo_started, promo_ended, stock_change, new_listing, delisted). Most mature programmes take a weekly full snapshot for reconciliation plus a daily change log for alerting.
Alerting
For price compliance work, the file is not the deliverable — the alert is. A brand tracking MAP or promotional execution wants an email or Slack message when a specific SKU breaches a threshold, not a 40,000-row CSV to sift through. Threshold alerting on top of the feed is usually what turns a data subscription into something a commercial team uses daily.
Frequently asked questions
Does Tesco have a public product API?
Tesco has historically offered developer API access on a partnership basis rather than as an open public API — Tesco has run developer API programmes in the past (notably its grocery API trials in 2009–2011), but as of 2026 it has no current self-service, publicly documented product/pricing API; any data access is arranged directly with Tesco on a case-by-case partnership basis. For most commercial monitoring use cases, structured extraction from public pages is the practical route. If an official data partnership is available for your use case, it is worth pursuing first.
Can you capture Clubcard prices without a Clubcard account?
Yes. Clubcard prices are displayed publicly on product pages so that shoppers can see the loyalty saving before signing in. Capturing them requires no account and no authentication — which is exactly why it stays on the right side of the public-data line.
How often should Tesco pricing be refreshed?
Daily is the standard for price monitoring and covers most promotional cycles, since UK grocery promotions typically turn over weekly. Twice-daily or intraday is worth it for volatile categories or for availability tracking, where stock state changes through the day. Weekly is sufficient for long-run inflation research.
Can pricing be captured for specific regions?
Yes, by running parallel captures across a defined postcode panel, with delivery_postcode stored on every row. This is the only reliable way to produce regional price comparisons.
Is scraping Tesco legal in the UK?
Collecting publicly displayed factual pricing information for analysis is a widely practised commercial activity. The risk areas are personal data, database rights, contractual terms, and conduct that impairs the service. Stay on public pages, avoid personal data, rate-limit conservatively, and take legal advice for your specific programme.
What about the other UK supermarkets?
The same schema extends to Sainsbury's (including Nectar prices), ASDA (including Rollback), Morrisons, Aldi, Lidl, Waitrose, Co-op, Iceland and Ocado. Cross-retailer comparison needs a product matching layer on top, keyed on EAN where published and fuzzy-matched on title and pack size where not.
Get a sample dataset
If you want to evaluate the data before committing, the fastest path is a live sample. Actowiz Solutions delivers UK grocery datasets covering Tesco and the other major UK retailers, with Clubcard and loyalty price capture, postcode-level context, validated schemas and scheduled delivery to S3, SFTP, BigQuery or API.
Free proof of concept: 1,000 Tesco SKUs from a category of your choice, delivered in 48 hours, in your preferred format.
Request Your Free Tesco Sample

 Pricing & Promotions
MAP Violations Brand Protection Counterfeit Detection Price Intelligence AI HOT Data Intelligence
 Brand & Intelligence
Share of Search Content Audit & PDP Reviews & Ratings Retail Media Buy Box Monitoring Social Commerce HOT Live Commerce NEW Agentic Commerce NEW
 Digital Shelf & Search
Assortment Planning Competitive Benchmarking Product Availability Q-Commerce NEW
 AssortmentE-commerce Intelligence Hyperlocal Insights POI & Store Locator DTC Brand Analytics NEW
 For Retailers
 E-Commerce Dashboard
 Flipkart Insights (Live) #1
 Grocery Intelligence
.svg) Grocery Price (U.S.)
.svg) Quick Commerce (India) HOT
 Food & Restaurant
 Fashion Intelligence
 Automotive
 Travel & Hospitality
 Real Estate
 Food Delivery Intelligence NEW
 OTT & Streaming NEW
 By Use Case
 Pricing Intelligence
 Digital Shelf Analytics
 MAP Monitoring HOT
 Cross-Border Price Parity NEW
 Share of Search
 Review Sentiment
 Kitchen Market Gaps NEW
 Dynamic Pricing / AI Repricing NEW
 Promotions & Deals Alerts NEW
 B2B / POI & Lead Data NEW
 By Region🇮🇳 India 🇺🇸 USA 🇦🇪 Middle East 🇬🇧 UK 🇦🇺 Australia 🌏 SE Asia 🇪🇺 Europe 🌎 LATAMIndia
 Flipkart Real-Time Insights
 Quick Commerce — Zepto · Blinkit
 Pincode Price Tracker
Middle East
 GCC Q-Commerce — Talabat · Noon NEW
UK & Australia
 UK Grocery — Tesco, Sainsbury's, Asda
 AU Grocery — Coles & Woolworths NEW
 Marketplace Scrapers
Amazon API TikTok Shop API HOT Uber Eats API Airbnb API Zepto / Blinkit API Instacart API NEW Talabat API NEW
 Developer APIsWeb Extract API Reviews API SERP API Pricing Webhook NEW
 Universal APIsStreaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
 Delivery & SDKs
 Knowledge Center
Digital Shelf Playbook MAP Compliance Guide Pricing Intel Guide Scraping Compliance TikTok Shop Guide NEW Cross-Border Guide NEW
 Guides & Playbooks
🎉 Seasonal & event tracking NEWBlack Friday pricing report Festive season, India Ramadan, GCC grocery All seasonal reportsSample Datasets HOT ROI Calculator NEW API Postman Collection Demo Dashboards Free API Playground NEW Press Kit
 Downloads & Tools
Trust Center About Us FAQs Careers
 Trust & CompanyRetail shelf research NEWRetail shelf research


 4.8/5 Average Rating
 50+ Video Testimonials
 92% Client Retention
 50+ Countries Served