Core services
Enterprise Data Extraction

Scalable web, app and AI-powered collection across 40+ countries.

All 58 services →
New 2026
AI Training Data

Corpus building with provenance and opt-out compliance.

Learn more →
Free pilot
24-hour sample

We run collection on your own sources before you commit.

Get a sample →
58Services
40+Countries
DEVELOPER

Ready-Made Scrapers

Pre-built for top platforms. Self-serve, no setup.

View All →
TRY FREE

API Playground

Test endpoints instantly. No credit card.

Start Free →
28Tools
2SDKs
icons Delivery & SDKs
Streaming Crawl API Scheduler Realtime Alerts Webhook Delivery 🐍 Python SDK 💚 Node.js SDK
Need it managed instead?

Fixed monthly retainer, named engineer, no per-request metering.

Managed Data API →
HOT

Case Studies

How brands use Actowiz, with named outcomes.

Read →
FREE

Sample Datasets

Real output, no signup.

Download →
NEW

ROI Calculator

Model the return on a data engagement.

Calculate →
Navratri Mega Sale Price Tracking

Introduction

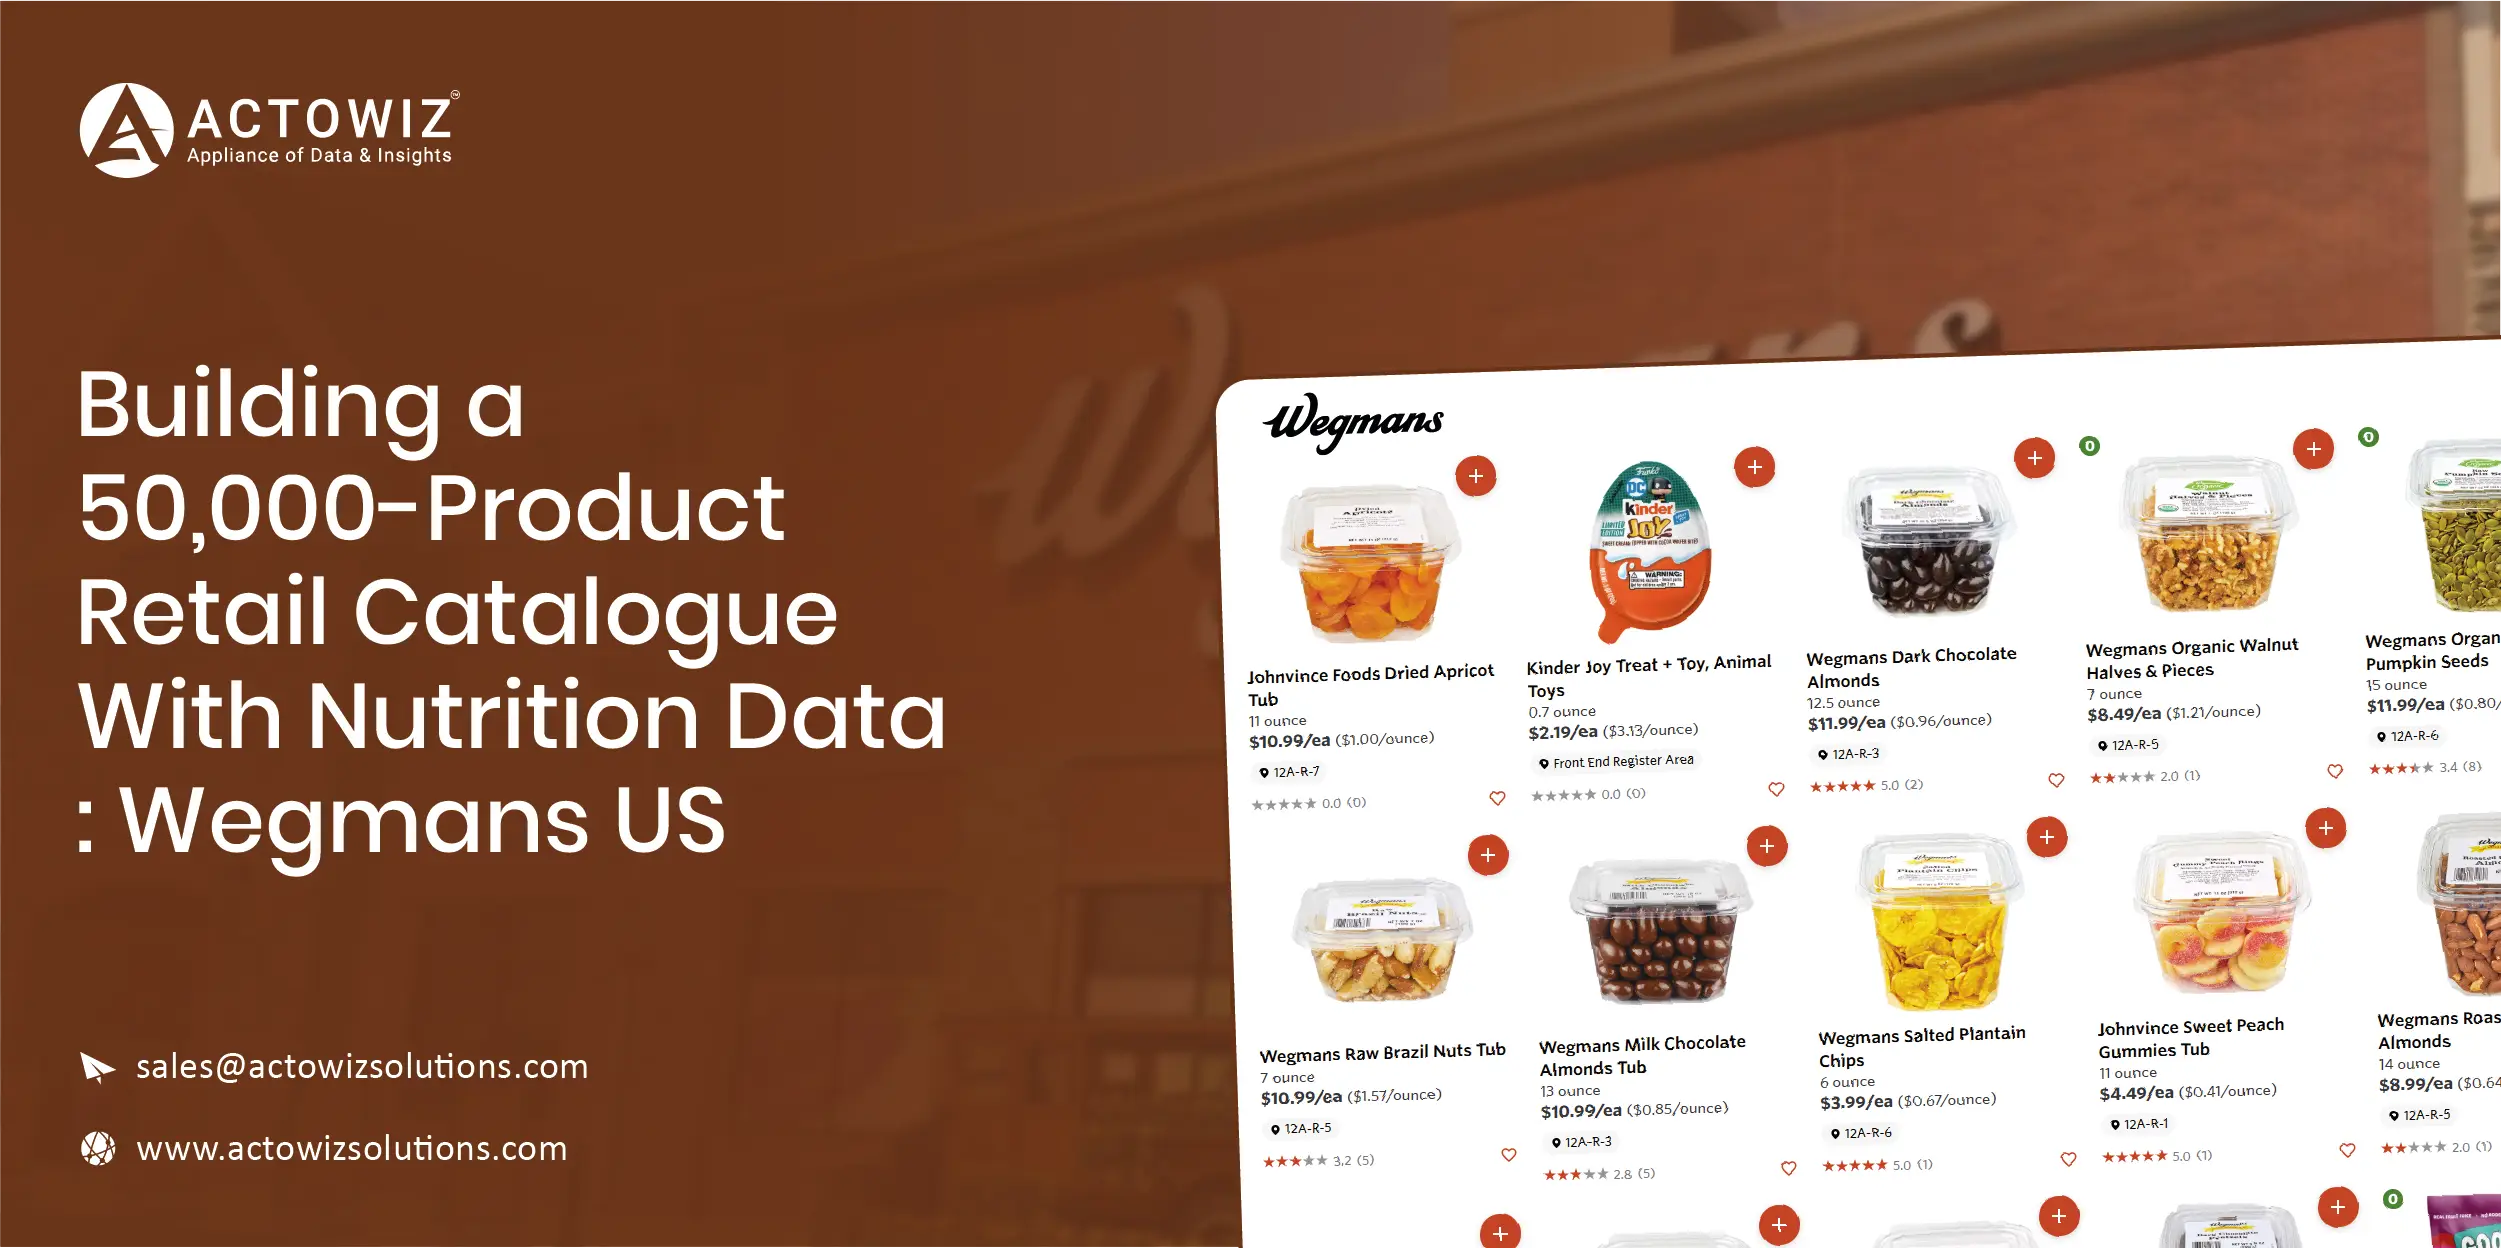
A research team needed a complete snapshot of a US grocery retailer's catalogue — up to 50,000 products across selected categories, with pricing and nutrition attributes, from one defined store location. A once-off extraction at this scale succeeds or fails on two decisions made before collection starts: locking the location, and defining what "complete attributes" means per product type. Delivered as a structured Excel dataset for market analysis and competitive benchmarking.

The Problem: Bulk Catalogue Extractions Fail Quietly

Navratri Mega Sale Price Tracking

A once-off catalogue pull looks like the simplest possible data engagement. No scheduling, no change detection, no ongoing maintenance. Pull everything once, hand it over.

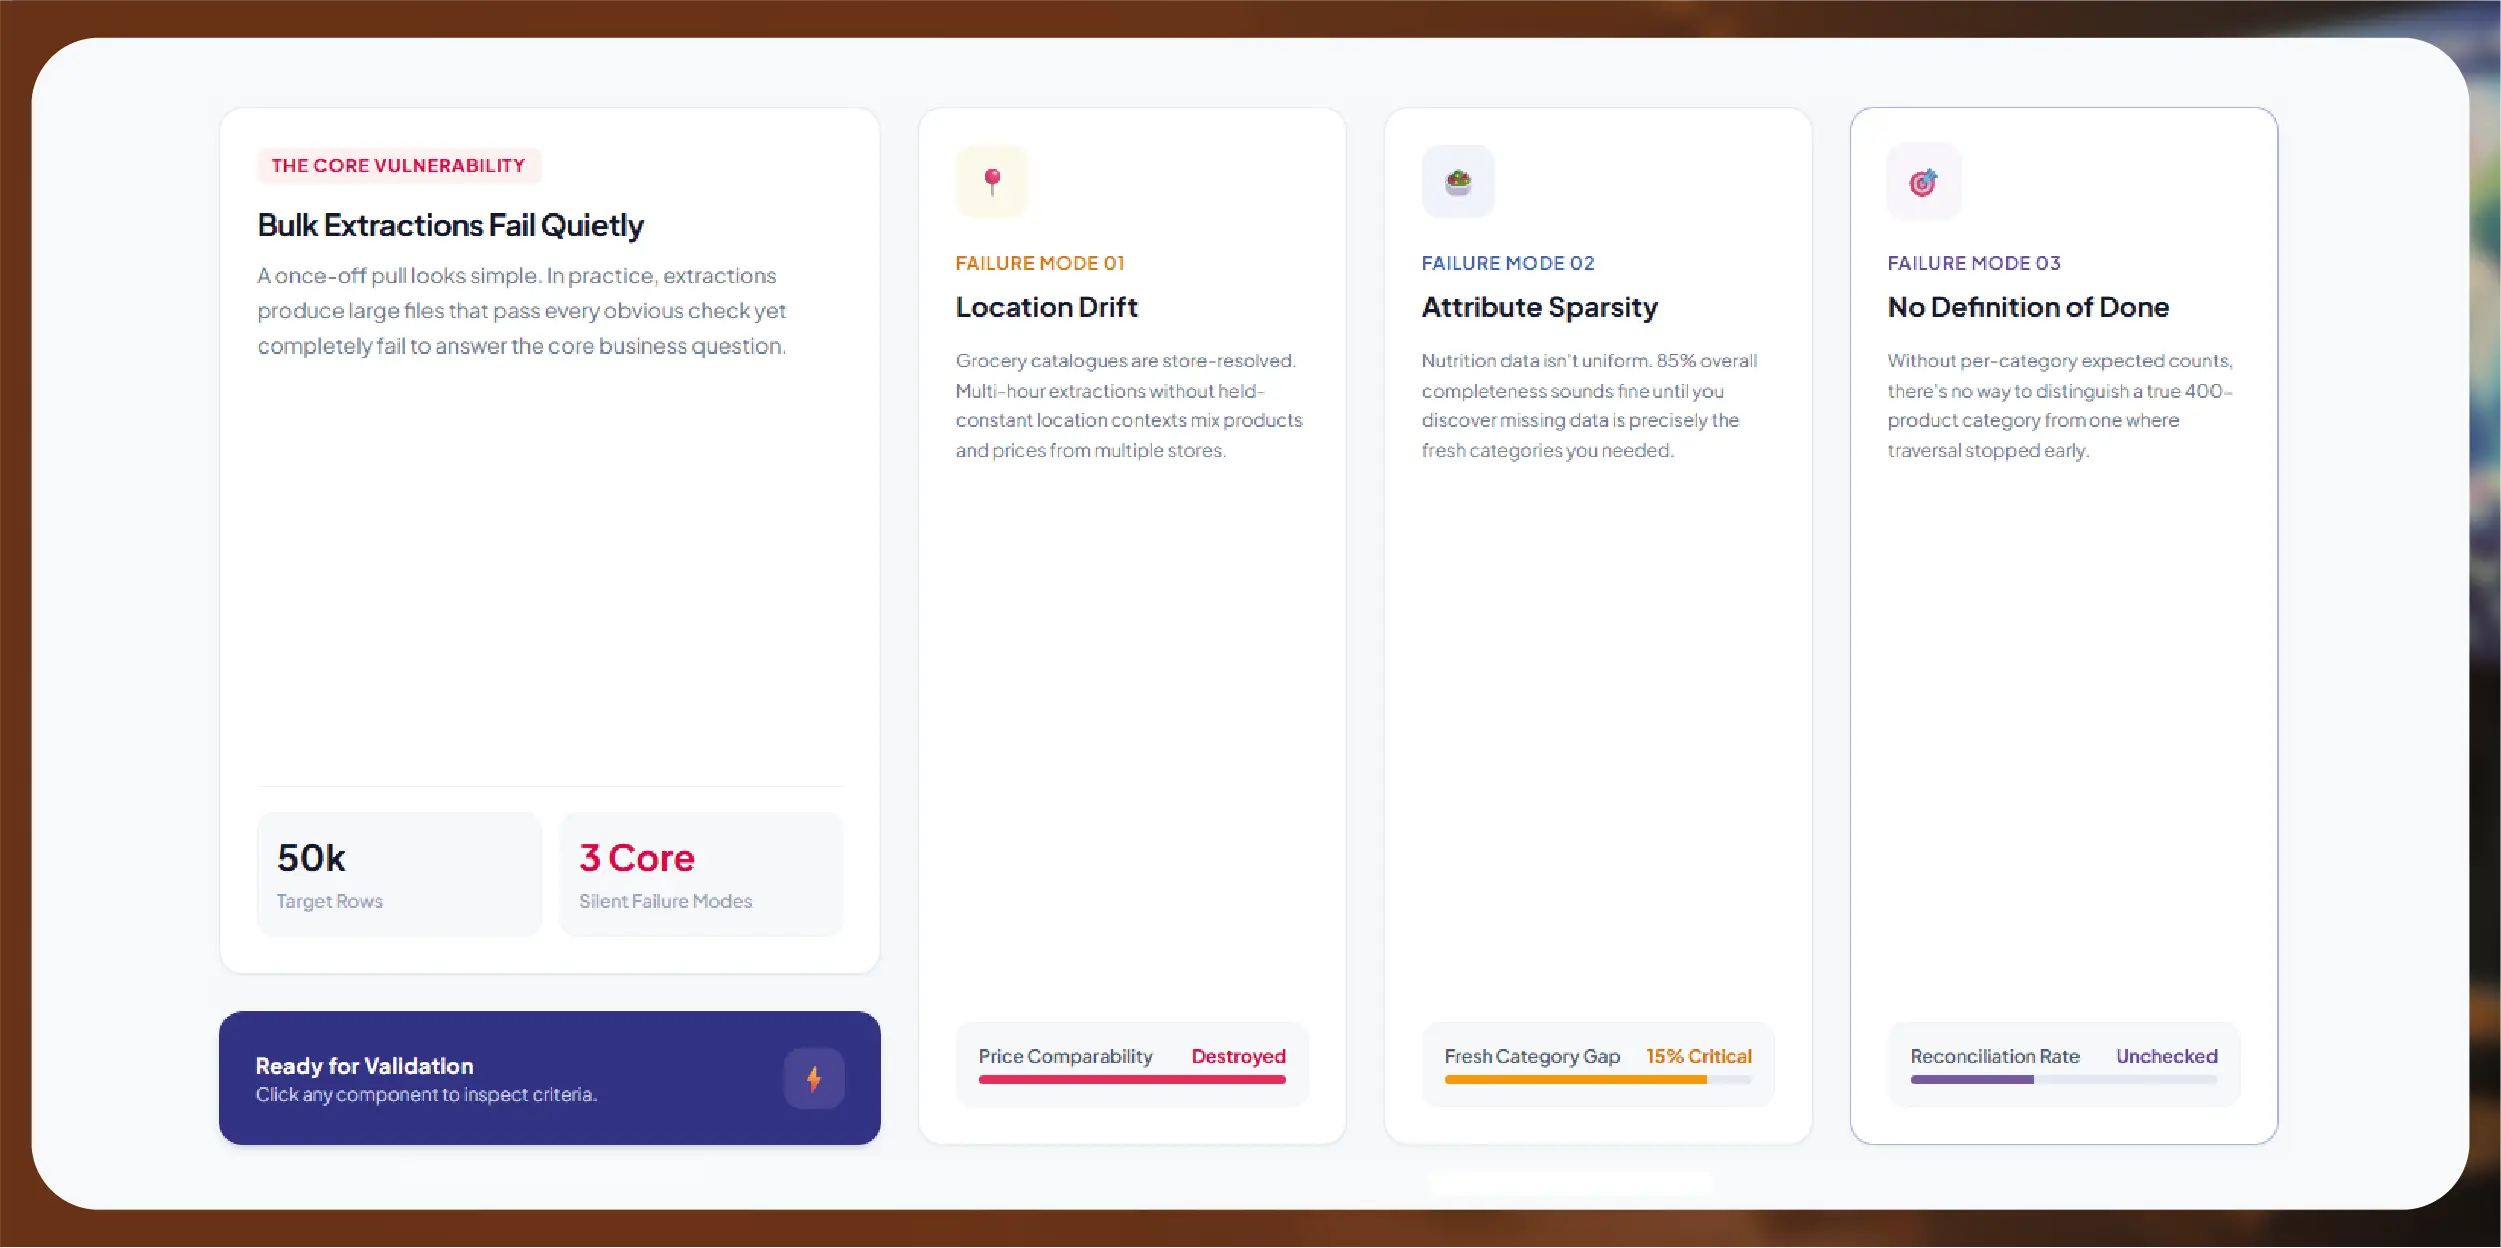
In practice, bulk extractions produce a specific and frustrating failure: a large file that passes every obvious check and cannot answer the question it was commissioned for. Usually for one of three reasons.

  • Location drift. Grocery catalogues are store-resolved. If a 50,000-row extraction runs over many hours and the location context isn't held constant, the file contains products and prices from more than one store. Nothing in the output reveals this. Every price is a real price; they are simply not comparable to each other, which destroys the file's use for price analysis.
  • Attribute sparsity where it matters most. Nutrition data is not published uniformly. A packaged product may carry a full nutrition panel and ingredient list; fresh produce, bakery and deli items frequently carry none. A file that is 85% complete on nutrition sounds acceptable until you discover the missing 15% is precisely the fresh categories the analysis was about.
  • No definition of done. "Up to 50,000 products across selected categories" has to be reconciled against something. Without a per-category expected count, there is no way to distinguish a category that genuinely holds 400 products from one where traversal stopped early at 400.

What We Built

Scope definition, before collection

Three parameters were fixed in writing first:

  • One defined store location, held for the entire extraction. Every row in the file resolves to the same store, making prices internally comparable.
  • A defined category list with per-category expected product counts, used later for reconciliation.
  • A mandatory attribute list supplied by the client, with each attribute classified as universally available, conditionally available by product type, or best-effort.

That third classification is the one that turns a bulk pull into a usable dataset. It converts "nutrition data is missing" from a delivery dispute into a documented, expected property of specific product categories.

Attributes captured
Field group Attributes
Identity Product name, brand, size/pack, product ID, product URL, UPC where published
Commercial Regular price, sale price, unit price, promotional label, price-per-unit measure
Categorization Full category path, department, sub-category
Nutrition Serving size, calories, macronutrients, sodium, sugars, full nutrition panel fields (where published)
Composition Ingredient list, allergen declarations, dietary flags (where published)
Media Primary image URL
Provenance Store location, extraction date
Reconciliation and quality control
  • Per-category count reconciliation against expected volumes, so an early-terminating traversal is caught rather than shipped
  • Location constancy verification across the full extraction window — every row confirmed against the same resolved store
  • Attribute-completeness reporting by category, delivered alongside the dataset, so the client knows before analysis where nutrition coverage is thin and why
  • Duplicate resolution on product ID, with size and pack variants preserved as separate rows rather than collapsed

The completeness report is the deliverable clients don't ask for and rely on most. It is the difference between an analyst wondering whether the data is broken and an analyst knowing that deli items carry no nutrition panel at source.

Delivery

Structured Excel dataset in the client's mandated attribute schema, delivered by email as a single one-time handover, with the accompanying completeness report.

Results

Before After
No catalogue baseline Up to 50,000 products in a single comparable snapshot
Nutrition data unavailable at scale Nutrition and ingredient attributes captured where published
Store-level price comparability uncertain All rows from one verified location
Unknown coverage gaps Documented attribute completeness by category

Business outcomes reported by the client:

  • A single-location catalogue baseline suitable for price-architecture and assortment analysis
  • Nutrition and ingredient attributes at catalogue scale, supporting product-composition and health-positioning research
  • Category-level completeness documentation, which shaped the analysis scope rather than surprising it mid-project
  • [FILL: final delivered product count and number of categories]
  • [FILL: nutrition attribute coverage rate by department]

Scope, location constraint, format and delivery channel come from the project record. Final counts and coverage rates must be sourced from the delivery report before publication.

What Made It Work

  • Lock the location, verify it throughout. On a store-resolved catalogue, a multi-hour extraction that doesn't hold location produces a file where every value is real and the aggregate is meaningless. This is the single highest-risk element of a bulk grocery pull.
  • Classify attributes by expected availability before collecting. Universally available, conditional by product type, best-effort. Doing this up front turns a delivery argument into a documented finding.
  • Reconcile per category, not in total. A total row count near target hides a category that stopped at a third of its products. Only per-category expected counts catch it.
  • Ship the completeness report with the data. Analysts trust a dataset that tells them where it is thin far more than one that presents itself as uniformly complete.

Where Once-Off Catalogue Builds Make Sense

Once-off extraction is the right model — and often the only sensible model — for market-entry and category-sizing research, competitive assortment benchmarking, product-composition and nutrition studies, catalogue seeding for a new platform, taxonomy and attribute-schema design, and academic or consulting research with a fixed question.

It is the wrong model for anything involving change over time. Price tracking, availability monitoring and promotional analysis all require repeated collection; a single snapshot cannot support them regardless of how large it is.

Once-off work makes up a substantial share of our delivery — 379 of our active feed configurations are once-off scoped — alongside recurring monthly, weekly and daily programs.

Actowiz Solutions has delivered catalogue-scale extractions across US, UK, Australian and Indian grocery and retail chains, including Wegmans, Sam's Club, Costco, Sainsbury's, Metro Cash & Carry and Taobao.

FAQ

How many products can be extracted in a single once-off project?

Catalogue-scale extractions in the tens of thousands of products are routine; this engagement was scoped at up to 50,000. The practical limits are the source catalogue size and the requirement to hold location constant across the collection window.

Can nutrition and ingredient data be extracted from grocery sites?

Where the retailer publishes it. Packaged goods commonly carry full nutrition panels, ingredient lists and allergen declarations on the product page. Fresh produce, bakery, deli and prepared foods frequently do not. Coverage is documented per category rather than assumed.

Why does the store location matter for a grocery extraction?

Grocery catalogues and prices are store-resolved. If location changes mid-extraction, the resulting file mixes prices from different stores while looking entirely valid, which makes it unusable for price analysis. Location is fixed and verified throughout.

What format is a bulk catalogue delivered in?

Excel, CSV or JSON in your specified attribute schema. Excel suits analyst-facing one-time datasets; CSV or JSON suits ingestion into a database or application.

Is a once-off extraction enough for price tracking?

No. A snapshot captures state at one moment. Price tracking, stockout monitoring and promotional analysis all need repeated collection — at minimum weekly, more often daily or several times daily.

Do you provide a data completeness report?

Yes. Attribute completeness by category is delivered alongside catalogue-scale datasets, so gaps that exist at source are documented rather than mistaken for extraction failures.

Social Proof That Converts

Trusted by Global Leaders Across Q-Commerce, Travel, Retail, and FoodTech

Our web scraping expertise is relied on by 4,000+ global enterprises including Zomato, Tata Consumer, Subway, and Expedia — helping them turn web data into growth.

4,000+ Enterprises Worldwide
50+ Countries Served
20+ Industries
Join 4,000+ companies growing with Actowiz →
Real Results from Real Clients

Hear It Directly from Our Clients

Watch how businesses like yours are using Actowiz data to drive growth.

1 min
★★★★★
"Actowiz Solutions offered exceptional support with transparency and guidance throughout. Anna and Saga made the process easy for a non-technical user like me. Great service, fair pricing!"
TG
Thomas Galido
Co-Founder / Head of Product at Upright Data Inc.
2 min
★★★★★
"Actowiz delivered impeccable results for our company. Their team ensured data accuracy and on-time delivery. The competitive intelligence completely transformed our pricing strategy."
II
Iulen Ibanez
CEO / Datacy.es
1:30
★★★★★
"What impressed me most was the speed — we went from requirement to production data in under 48 hours. The API integration was seamless and the support team is always responsive."
FC
Febbin Chacko
-Fin, Small Business Owner
icons 4.8/5 Average Rating
icons 50+ Video Testimonials
icons 92% Client Retention
icons 50+ Countries Served

Join 4,000+ Companies Growing with Actowiz

From Zomato to Expedia — see why global leaders trust us with their data.

Why Global Leaders Trust Actowiz

Backed by automation, data volume, and enterprise-grade scale — we help businesses from startups to Fortune 500s extract competitive insights across the USA, UK, UAE, and beyond.

icons
7+
Years of Experience
Proven track record delivering enterprise-grade web scraping and data intelligence solutions.
icons
4,000+
Projects Delivered
Serving startups to Fortune 500 companies across 50+ countries worldwide.
icons
200+
In-House Experts
Dedicated engineers across scrapers, AI/ML models, APIs, and data quality assurance.
icons
9.2M
Automated Workflows
Running weekly across eCommerce, Quick Commerce, Travel, Real Estate, and Food industries.
icons
270+ TB
Data Transferred
Real-time and batch data scraping at massive scale, across industries globally.
icons
380M+
Pages Crawled Weekly
Scaled infrastructure for comprehensive global data coverage with 99% accuracy.

AI Solutions Engineered
for Your Needs

LLM-Powered Attribute Extraction: High-precision product matching using large language models for accurate data classification.
Advanced Computer Vision: Fine-grained object detection for precise product classification using text and image embeddings.
GPT-Based Analytics Layer: Natural language query-based reporting and visualization for business intelligence.
Human-in-the-Loop AI: Continuous feedback loop to improve AI model accuracy over time.
icons Product Matching icons Attribute Tagging icons Content Optimization icons Sentiment Analysis icons Prompt-Based Reporting

Connect the Dots Across
Your Retail Ecosystem

We partner with agencies, system integrators, and technology platforms to deliver end-to-end solutions across the retail and digital shelf ecosystem.

icons
Analytics Services
icons
Ad Tech
icons
Price Optimization
icons
Business Consulting
icons
System Integration
icons
Market Research
Become a Partner →

Popular Datasets — Ready to Download

Browse All Datasets →
icons
Amazon
eCommerce
Free 100 rows
icons
Zillow
Real Estate
Free 100 rows
icons
DoorDash
Food Delivery
Free 100 rows
icons
Walmart
Retail
Free 100 rows
icons
Booking.com
Travel
Free 100 rows
icons
Indeed
Jobs
Free 100 rows

Latest Insights & Resources

View All Resources →
thumb
Blog

How the US Grocery Price Inflation Tracker 2026 Helps Retailers Manage Rising Food Costs and Pricing Decisions

Track the US Grocery Price Inflation Tracker 2026 to monitor food price trends, category changes, and inflation insights for smarter decisions.

thumb
Case Study

How We Helped a Retail Brand Leverage Sobeys and Walmart Retail Data for Assortment and Pricing Optimization

Discover how Sobeys and Walmart retail data scraping helps brands track prices, products, promotions, and assortment for smarter retail decisions.

thumb
Report

Zomato Restaurant & Menu Data Intelligence Report 2026

Zomato Restaurant & Menu Data Intelligence Report 2026 reveals restaurant, menu, pricing, ratings, and food delivery trends for smarter decisions.

Start Where It Makes Sense for You

Whether you're a startup or a Fortune 500 — we have the right plan for your data needs.

icons
Enterprise
Book a Strategy Call
Custom solutions, dedicated support, volume pricing for large-scale needs.
icons
Growing Brand
Get Free Sample Data
Try before you buy — 500 rows of real data, delivered in 2 hours. No strings.
icons
Just Exploring
View Plans & Pricing
Transparent plans from $500/mo. Find the right fit for your budget and scale.

Request Free Sample Data

Our team will reach out within 2 hours with 500 rows of real data — no credit card required.

+1
Free 500-row sample · No credit card · Response within 2 hours